# Welcome to Vectra Fusion
Start here to log in, onboard data, and navigate Vectra Fusion.
## Logging in to Fusion
If you are setting up Fusion for the first time, or using it without centralized SSO, you will receive an email with your account information and a link to log in to your Fusion instance when your account is created. If you use an existing Fusion instance that is already deployed and connected to your corporate SSO, contact your Fusion admin for the correct login link.
## Deploying Fusion
Deploy Fusion in two stages:
1. Ingest network traffic logs and context.
* For cloud onboarding, see [Fusion Onboarding for Cloud Engineers](/cloud-onboarding/fusion-onboarding-for-cloud-engineers).
* For on-premises networks, see [Ingest NetFlow & sFlow](/ingest-network-traffic-logs/netflow-sflow).
* For context enrichment integrations *(native cloud context is covered in cloud onboarding)*, see [Context Integrations](/settings/data-management/context-integrations).
2. Add supporting configuration.
* [Traffic Classification](/settings/data-management/traffic-classifications)
* [SSO](/settings/user-management/index-2)
* [Automating Response in Fusion](/automate-responses/response)
* [Add a Dashboard](/dashboards/manage/add-dashboard)
* [Adding a Detection Model](/detection-models/add-detection-models)
## Using the Fusion Portal
Use the Fusion Portal for two primary tasks beyond configuration:
1. Viewing [Events](/events/viewing), which are triggered by [Detection Models](/detection-models/overview).
2. Observing traffic for use cases such as network investigations, operational security, compliance and governance, and network management. This is done through [System Dashboards](/dashboards/system) and [Custom Dashboards](/dashboards/manage/your-dashboards), tailored to your environment and use cases.
Fusion's Network Query Language (NQL) is used to filter traffic in the Portal, tailor dashboards, and create detection models. To learn how to use it, see [NQL Overview and Syntax](/network-query-language/nql-overview-and-basics).
{% hint style="info" icon="diagram-sankey" %}
**Fusion Admin: Initial Home**
If you are setting up Fusion for the first time, the Fusion Portal will show a limited setup view directing you to configure a traffic source. The full Fusion Portal appears automatically once the first traffic log is successfully ingested.
{% endhint %}
{% hint style="info" icon="house-chimney-window" %}
**The Home screen is a dashboard and can be changed**
You can set a new dashboard to be **Your Homepage** *(only for you)* or **Your Company Homepage** *(for all users by default)* by clicking the **⋯** next to the dashboard name and selecting **Set as Your Homepage** or, if you are an administrator, **Set as Company Homepage**.
{% endhint %}
#### Select a New Dashboard
Display a system or custom dashboard by selecting it from the **Select dashboard** dropdown in the top-right corner of the Home screen. Once you select a dashboard, Fusion opens it directly. This is often faster than navigating back to the full dashboards list.
For more details, see [About Dashboards](/dashboards/about).
## Using Fusion with AI
The Vectra Fusion MCP Server is an open-source, local Model Context Protocol (MCP) server that enables direct, natural language interaction with Vectra Fusion through AI workflows. With the Vectra MCP Server, users can conduct network forensics, investigate suspicious activity, and analyze security events by chatting with their AI in plain English.
Get started in the [neto-mcp GitHub repository](https://github.com/netography/neto-mcp).
## Using Fusion with API
The Fusion Portal is an API-driven interface, so everything you can see in the Portal is also available via the API. For the full API, see: [Fusion API Reference](https://docs.fusion.vectra.ai/api-reference).
## ✋ Need Help?
{% embed url="" %}
## About Fusion
Vectra Fusion is a SaaS network observability and threat detection platform.
It ingests network traffic logs, including cloud VPC flow logs, DNS logs, and on-premises NetFlow, then enriches them with context. It provides security detections and analytics based on the enriched network metadata it collects.
You can use the Fusion Portal to create and view dashboards and conduct incident investigations. You can use the Fusion API to interact with the system programmatically, the Fusion MCP to integrate with AI workflows, and Response Policies to deliver events from Fusion to systems such as SIEM, SOAR, and other third-party products.
Vectra Fusion supports the following flow log types:
* AWS VPC flow logs, AWS Transit Gateway flow logs
* Microsoft Azure VNet flow logs, Microsoft Azure NSG flow logs
* Google Cloud Platform (GCP) VPC flow logs
* Oracle Cloud (OCI) VCN flow logs
* IBM Cloud VPC flow logs
* NetFlow v5, NetFlow v9, NetFlow v10 (IPFIX), sFlow
Vectra Fusion supports the following DNS resolver log types:
* AWS Route 53, GCP Cloud DNS
Vectra Fusion supports the following context enrichment sources:
* Cloud Providers (AWS, Azure, GCP, IBM, Oracle)
* Asset Management (Axonius, Device42, RunZero, Tanium)
* Endpoint Protection (CrowdStrike, Microsoft Defender, SentinelOne)
* Cloud Security (Wiz), Vulnerability Management (Tenable), OT Security (Claroty)
* Generic Sources (S3, CSV, local files, REST API, custom modules)
{% hint style="info" icon="bullhorn" %}
Netography Fusion is the previous name for Vectra Fusion
You may still see references to **Netography** or **Netography Fusion** in parts of the documentation or product. Vectra acquired Netography in October 2025 and rebranded Netography Fusion to Vectra Fusion. See the [acquisition announcement](https://www.vectra.ai/about/news/vectra-ai-acquires-netography-to-expand-its-ai-driven-cybersecurity-platform-with-pioneering-cloud-native-network-observability).
{% endhint %}
# Fusion Onboarding for Cloud Engineers
A guide to Vectra Fusion for cloud engineers who have been asked by the security team to assist with onboarding.
## Quick introduction to Vectra AI and Fusion
This guide helps cloud engineers answer these questions:
1. [Who is Vectra AI?](#who-is-vectra-ai)
2. [What is Vectra Fusion?](#what-is-fusion)
3. [Why is the cloud team involved?](#why-your-team-is-involved)
4. [What are the deployment options and details for my cloud(s)?](#cloud-specific-deployment-guidance)
{% hint style="info" icon="forward" %}
**TL;DR: You will need to configure logging and permissions in the cloud, and then onboard those sources to Fusion**
1. You configure in-scope logs to be written to a compatible logging destination (typically S3 in AWS, storage blobs in Azure, Pub/Sub topics in GCP, and object storage in OCI) and provide Fusion with the permission to read those logs.
2. You configure context enrichment by either providing cross-account permission for Fusion to read resource metadata from your cloud or by deploying a cloud function that reads resource metadata from within your cloud and then pushes it to the Fusion API.
3. You onboard log sources to Fusion by creating traffic source(s) in Fusion using the Fusion portal, API, or CLI. You onboard context enrichment to Fusion by creating context integration(s) in Fusion using the Fusion portal, API, or CLI, OR by deploying a cloud function that uses a Fusion API key.
4. Vectra provides Terraform-based cloud onboarding automation for AWS, Azure, and GCP that can handle onboarding to Fusion and context enrichment for you. It can also manage flow log and DNS log configuration according to a policy you define, if you want it to. Vectra also provides guides for manual configuration and onboarding, and examples for integrating with your IaC.
{% endhint %}
## Who is Vectra AI?
{% embed url="" %}
Security teams use Vectra AI for detecting and responding to threats.
Vectra helps security teams understand attacker behavior across network, identity, cloud, and SaaS environments. It is not a firewall, a CSPM, SIEM, or a general-purpose logging platform — it is a detection and response layer that uses telemetry from multiple environments to surface meaningful attacker signals and support analyst investigation workflows.
#### When cloud teams get involved
* A request from the security team to connect cloud logs to an external platform
* A need for IAM role approval, logging configuration, log routing, or IaC deployment
* A conversation about scope, permissions, cost, and governance
## What is Vectra Fusion?
Vectra Fusion is used to collect and process cloud logs, including VPC flow logs, DNS resolver logs, and cloud context metadata. That data can then be used for search, analytics, dashboards, retention, and alerting.
Fusion is closest to a managed network log ingestion and analytics layer. It is not a replacement for your cloud logging platform, data lake, Terraform pipeline, or cloud governance process. It fits alongside tools and patterns your team already knows.
Fusion is a SaaS; there is no backend or sensor deployment to the cloud involved.
| Familiar tool / concept | How Fusion relates |
| --------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Cloud logging (CloudWatch, Azure Monitor, Cloud Logging, OCI Logging) | Fusion consumes selected logs and metadata for security use cases |
| SIEM | Fusion can complement downstream security workflows and alerts; some organizations decide to stop sending high-volume network metadata log sources directly to these sinks and have Vectra send prioritized events at low volume instead |
| Terraform / CloudFormation / IAC | Deployment should happen through customer-controlled IaC or approved cloud-native methods; for a POC or small environments this could be done with manual configuration |
| IAM / RBAC | Permissions are reviewed, scoped, and approved by the cloud team |
| VPC / VNet flow logs | Fusion uses flow logs for providing network observability and detection without the need to use traffic mirroring, packet brokers, or agents |
| DNS logs | Fusion can use cloud DNS resolver logs as context for traffic and investigation |
| Dashboards / observability tools | Fusion can also be used as its own standalone search and analytics platform for ingested telemetry |
## What is cloud context?
Context is resource metadata from the cloud provider that is combined with flow logs in Fusion. In addition to ingesting flow logs and DNS logs, Vectra Fusion enriches the logs with context from the cloud environment. For example, in AWS, a flow log may tell you that IP `1.2.3.4` in VPC `vpc-01234567` is the source IP. Describing the resources in that AWS account can determine that this IP belongs to an EC2 instance, along with a name and other attributes that provide valuable context about that traffic.
#### Two deployment options for context enrichment
{% columns %}
{% column %}
#### Option 1: Cross-account access
You provide read-only permission for Vectra Fusion to read asset metadata from your cloud.
This is accomplished with a cross-account IAM role in AWS, an Entra ID app in Azure, and a service account in GCP and OCI.
{% endcolumn %}
{% column %}
#### Option 2: Cloud-deployed function
You deploy a cloud function that reads asset metadata from your cloud and then uses a Vectra Fusion API key to upload this context to Vectra Fusion.
This is accomplished with a Lambda function in AWS, an Azure Function in Azure, and a Cloud Function in GCP. These can be deployed as part of Vectra Fusion cloud onboarding automation or through your own IaC. The source code for these functions is provided in the automation repo.
{% endcolumn %}
{% endcolumns %}
## Why your team is involved
The security team needs the data, but cloud teams usually own the path to it.
Security teams often need visibility into cloud traffic, DNS activity, and cloud context. But they typically do not own the infrastructure required to enable, route, scope, or govern that telemetry. That is why the cloud team is part of this conversation — because the logging path runs through infrastructure you own and operate.
The goal is not to bypass cloud governance. The goal is to help the SOC get useful telemetry through a deployment model the cloud team can approve and operate. Every permission, scope decision, and deployment method is subject to your team's approval and action.
### Key ownership areas
* **IAM / RBAC**\
Your team reviews and approves all IAM roles, trust relationships, RBAC assignments, and custom role definitions before deployment proceeds.
* **IaC pipelines**\
All infrastructure changes occur through your existing IaC and cloud configuration pipelines. If you use Vectra's Terraform-based cloud onboarding automation, you can optionally let it make logging configuration changes through a deployed cloud function according to a policy.
* **Log routing**\
Your team controls where logs land, how they are routed, what gets sent, and what retention and cost guardrails apply at every stage.
* **Scope decisions**\
Which accounts, regions, VPCs, and supported log types are included is defined as part of the deployment. Vectra works within the boundary you define.
## Activation journey
{% stepper %}
{% step %}
## Which cloud(s)?
AWS, Azure, GCP, OCI, IBM
{% endstep %}
{% step %}
## Define initial scope
* **AWS:** Org, OUs, Accounts, Regions, VPCs
* **Azure:** Tenant, Management Groups, Subscriptions, Regions, VNets
* **GCP:** Org, Folders, Projects, VNets, Subnets
* **OCI:** Tenancy, Compartments, VCNs
{% endstep %}
{% step %}
## Data source types
* **AWS:** VPC flow logs, transit Gateway flow logs, Route 53 DNS logs, cloud context
* **Azure:** VNet flow logs, cloud context
* **GCP:** VPC flow logs, Cloud DNS logs, cloud context
* **OCI:** VCN flow logs, cloud context
{% endstep %}
{% step %}
## Deployment method
* Cloud configuration: Vectra-provided automation, Customer-developed automation, Manual console/CLI steps
* Fusion configuration: Fusion console, Fusion API, Fusion CLI
{% endstep %}
{% step %}
## Validate ingest
Confirm logs and context are being successfully ingested to Fusion.
{% endstep %}
{% step %}
## Use in Vectra Fusion
Search, dashboards, alerting, investigations.
{% endstep %}
{% step %}
## Tune scope
Add or modify scope (e.g. new OUs, accounts, VPCs, etc.).
{% endstep %}
{% endstepper %}
## Cloud-specific deployment guidance
Each cloud has its own logging model, IAM system, deployment tooling, and logging path. Select the tab for your environment(s).
{% tabs %}
{% tab title="AWS" %}
**AWS VPC flow logs, AWS Transit Gateway flow logs, AWS Route 53 DNS resolver logs, AWS cloud context**
#### Deployment options
| Option | Best for | Next steps |
| ---------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Manual onboarding | Organizations with a small number of VPCs that rarely change, or for an initial PoC. |
|
| Vectra onboarding automation | Organizations that want a complete, supported, end-to-end solution for managing flow log configuration and onboarding to Fusion. | [Vectra Terraform / CloudFormation StackSet Cloud Onboarding Automation for AWS Organizations](/cloud-onboarding/aws-cloud-onboarding/neto-onboarding-aws) |
| Custom IaC automation | Organizations experienced with AWS IaC that already provision VPCs or flow log configurations through automation and want to extend that workflow to Fusion. |
|
#### Decisions to make
* What deployment method will be used?
* What OUs, accounts, and VPCs are in scope for the initial deployment?
* What log ingest method will be used?
* S3 — recommended
* Kinesis — alternative
* What cloud context enrichment model will be used?
* Cross-account read-only IAM role
* Lambda cloud function
* Is there a centralized logging account, or will one be designated for this purpose?
{% endtab %}
{% tab title="Azure" %}
**VNet flow logs, cloud context**
#### Deployment options
| Option | Best for | Next steps |
| ---------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| Manual onboarding | Organizations with a small number of VNets and subscriptions that rarely change, or for an initial PoC. |
|
| Vectra onboarding automation | Organizations that want a complete, supported, end-to-end solution for managing flow log configuration and onboarding to Fusion. | [Vectra Terraform Cloud Onboarding for Azure Tenants](/cloud-onboarding/azure-cloud-onboarding/neto-onboarding-azure) |
| Custom IaC automation | Organizations experienced with Azure IaC that already provision VNets or flow log configurations through automation and want to extend that workflow to Fusion. |
|
#### Decisions
* What deployment method will be used?
* Which tenant, management groups, subscriptions, and VNets are in scope?
* Which subscription should host the Azure storage accounts that receive VNet flow logs?
* Is Network Watcher enabled in the required subscriptions?
* What cloud context enrichment model will be used?
* Read-only Entra ID application
* Azure Function
{% endtab %}
{% tab title="GCP" %}
**VPC flow logs, Cloud DNS logs, cloud context**
#### Deployment options
| Option | Best for | Next steps |
| ---------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Manual onboarding | Organizations with a small number of projects that rarely change, or for an initial PoC. |
|
| Vectra onboarding automation | Organizations that want a complete, supported, end-to-end solution for managing flow log configuration and onboarding to Fusion. | [Vectra Terraform Cloud Onboarding for GCP Organizations](/cloud-onboarding/gcp-cloud-onboarding/neto-onboarding-gcp) |
| Custom IaC automation | Organizations experienced with GCP IaC that already provision VPCs, DNS logging, or related resources through automation and want to extend that workflow to Fusion. |
|
#### Decisions
* What deployment method should be used?
* Which organization, folders, projects, and VPCs are in scope?
* What log sink architecture will be used? See [Aggregated sink design patterns](https://docs.fusion.vectra.ai/ingest-network-traffic-logs/flow-logs/gcp-flow-logs-via-pubsub#id-3-create-a-cloud-logging-sink-pubsub).
{% endtab %}
{% tab title="OCI" %}
**VCN flow logs, cloud context**
#### Deployment options
| Option | Best for | Next steps |
| --------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Manual onboarding | Organizations with a small number of VCNs that rarely change, or for an initial PoC. |
|
| Custom IaC automation | Organizations experienced with OCI IaC that already provision resources or log configurations through automation and want to extend that workflow to Fusion. | [OCI Cloud Onboarding](/cloud-onboarding/oci-cloud-onboarding) |
#### Decisions
* What deployment method should be used?
* Which tenancy, compartments, and VCNs are in scope?
{% endtab %}
{% endtabs %}
## Success Criteria
A successful first onboarding is validated, and useful.
A good first onboarding is measured by whether the security team can do something useful with the data, whether the cloud team understands and can modify what was deployed, and whether the next tuning decision is clear. For larger organizations, start with a narrow, well-understood scope and validate, then expand.
* Cloud team understands what Vectra is and what Fusion does
* Deployment method is approved and executed through the IaC pipeline
* IAM and RBAC permissions are reviewed and scoped by the cloud team
* Initial scope is agreed to
* Flow logs, DNS logs, if applicable, and cloud context are flowing and confirmed in Vectra Fusion
* Log volume is understood
* Initial use case(s) are validated
* Next tuning/scoping decision is clear and owned
## Working session planner
Build the activation plan together. Use this section as a lightweight planning tool during a working session between the security and cloud teams.
| Field | Options / Notes |
| ------------------- | --------------------------------------------------------------------------------------------- |
| Primary cloud | AWS / Azure / GCP / OCI / Multi-cloud |
| Cloud team owner | Name and team responsible for deployment, IAM, and operational support |
| Security team owner | Name and team responsible for validation, use case, and ongoing analysis |
| Deployment method | Vectra onboarding automation, Custom IaC, Console/CLI |
| Initial scope | Org/OU/Account/VPC; Tenant/Management Group/VNet; Org/Folder/Project/VPC; Org/Compartment/VCN |
| Telemetry sources | Flow logs / DNS logs / Cloud context metadata |
| Initial use case | Security team cloud network observability |
Generated activation summary format:
We will start with \[cloud] for \[initial use case]. The cloud team owner is \[team]. The SOC owner is \[team]. The initial deployment method is \[method]. The first scope is \[scope]. The telemetry sources are \[sources]. Next step: \[action].
# AWS Cloud Onboarding
{% hint style="info" %}
New to Fusion cloud onboarding? Start with [Fusion Onboarding for Cloud Engineers](/cloud-onboarding/fusion-onboarding-for-cloud-engineers) for deployment models, scope planning, and cloud-specific guidance.
{% endhint %}
Use one of these three paths to configure AWS VPC flow logs, Route 53 Resolver logs, and onboarding to Fusion.
Choose the path that fits your environment:
* **Manual onboarding** — best for a small number of VPCs or an initial PoC
* **Vectra onboarding automation** — best for large or dynamic AWS environments
* **Custom IaC automation** — best if you prefer integrating to your existing IaC
### 1. Manual onboarding
Follow step-by-step guides to configure AWS and Fusion and onboard each VPC.
**Best for**
Organizations with a small number of VPCs that rarely change, or for an initial PoC.
**Next steps**
* [AWS VPC via S3 Setup (AWS Console method)](/ingest-network-traffic-logs/flow-logs/aws-vpc-flow-logs-via-s3-aws-console-setup-method)
* [AWS VPC via S3 Setup (CloudFormation method)](/ingest-network-traffic-logs/flow-logs/aws-vpc-flow-logs-via-s3-aws-cloudformation-setup-method-recommended)
* [Quickstart: AWS](/cloud-onboarding/aws-cloud-onboarding/quickstart-aws)
* [AWS Context Integration](/enrich-traffic-with-context/configure-context-integrations/aws)
### 2. Vectra Cloud Onboarding Automation for AWS Organizations
For detailed documentation, see [Vectra Terraform / CloudFormation StackSet Cloud Onboarding Automation for AWS Organizations](/cloud-onboarding/aws-cloud-onboarding/neto-onboarding-aws).
{% hint style="info" icon="robot" %}
**Using Terraform to automate onboarding**
Access Vectra's Terraform automation at .
For access to the repo, reach out to your Vectra contact with your GitHub ID or request the latest release package.
Vectra provides the `neto-onboarding` Terraform project for AWS Organizations, Azure Tenants, and GCP Organizations.
This automation can:
* Enable and configure AWS VPC flow logs, Azure VNet flow logs, and GCP VPC flow logs based on policy and tags
* Deploy the infrastructure required to integrate with Fusion across multiple accounts, subscriptions, or projects
* Adds VPCs/VNets configured for flow logging to Vectra Fusion as traffic sources.
* Deploy a single AWS Lambda, Azure Function, or Google Cloud Function for context enrichment across all in-scope environments
* Monitor for VPC and VNet changes, onboard new in-scope networks, and offboard networks that leave scope
{% endhint %}
**Best for**
Organizations that want a complete, supported, end-to-end solution for managing flow log configuration and onboarding to Fusion. This is usually the fastest path for large, dynamic, or multi-cloud environments.
**Next steps**
* Reach out to your Vectra contact and request access to the GitHub repo.
* Include your GitHub ID, or request the latest release package.
### 3. Custom IaC automation
Use your existing automation pipelines or scripts to:
* Deploy the IAM policy and custom role needed for Vectra to read flow logs from S3 buckets
* Configure VPC Flow Logs on each VPC to write to S3
* Call the Fusion API to create a Fusion traffic source for each VPC, or for each account and region when using a centralized S3 destination
**Best for**
Organizations experienced with AWS IaC that already provision VPCs or VPC flow log configurations through automation and want to extend that workflow to Fusion.
**Next steps**
* [AWS Custom IAC Onboarding for Cloud Automation Engineers](/cloud-onboarding/aws-cloud-onboarding/aws-configuration-automation-for-multiple-vpcs)
# AWS Custom IAC Onboarding for Cloud Automation Engineers
AWS onboarding details for cloud automation engineers using Vectra Fusion.
## Introduction
If you are not familiar at all with Fusion yet, see: [Fusion Onboarding for Cloud Engineers](/cloud-onboarding/fusion-onboarding-for-cloud-engineers).
If you have not yet reviewed the options for how to onboard AWS to Fusion, see: [AWS Cloud Onboarding](/cloud-onboarding/aws-cloud-onboarding).
This page provides the technical details and working examples needed for a cloud automation engineer to onboard AWS to Fusion within your existing IAC. Vectra's cloud onboarding automation is a fully operational example that you may also wish to leverage as you develop your own custom IAC.
*This guide covers VPC flow logs configured to write to S3. Vectra also supports using Kinesis to deliver flow logs to Vectra. Kinesis provides a lower latency approach to delivering flow logs to Fusion, but it comes at a significantly higher cost from AWS. As a result, most Vectra customers use the S3 method, and that is what is documented here.*
**To skip right to the CloudFormation deployment:**
[AWS VPC CloudFormation Stack Automation](/cloud-onboarding/aws-cloud-onboarding/netography-aws-cloudformation-automation)
### Integration Steps
1. Create S3 bucket to write VPC flow logs (and Route 53 DNS logs) to
2. Create IAM policy and role for Fusion to read from S3 bucket
3. Configure VPC flow logs in AWS
4. Configure Route 53 DNS logs in AWS (following same pattern as VPC flow logs)
5. Create traffic source(s) in Fusion for the VPC flow logs and DNS logs
6. Create cross-account IAM role for Fusion to read resource meta-data via context integration in Fusion
7. Create context integration in Fusion to read resource meta-data
## AWS VPC Flow Log Configuration Steps (via S3)
### 1. Create a S3 bucket to Write VPC Flow Logs to
#### S3 Bucket Region Recommendations
We recommend creating a S3 bucket for each region you have VPCs in, and directing the flow logs for each VPC to a S3 bucket in the same region. This minimizes write latency and cost.
If you want to use a single S3 bucket instead for simplicity, we recommend creating the S3 bucket in `us-east-1`. This minimizes read latency and cost, at the expense of write latency.
The configuration to avoid is having a single S3 bucket in a region that is NOT `us-east-1`. This will double your cross-region data transfer cost. This is a supported configuration, just not optimized for cost.
#### **ℹ️ Why regional alignment of S3 bucket(s) matter**
Although you can write VPC Flow Logs to a bucket in any region, co-locating the bucket with either the VPC or Vectra’s ingest endpoint (`us-east-1`) minimizes both latency and data-transfer fees:
* **Latency**
* Same-region writes (co-located with the VPC) or reads ( `us-east-1`) avoid extra network hops.
* **Cost**
* Intra-region data transfers are free.
* Cross-region writes (e.g. eu-west-1 → us-east-1) incur standard AWS cross region data transfer fees.
* Cross-region reads (S3 → us-east-1) likewise incur cross region data transfer fees **unless** the bucket lives in `us-east-1` where Vectra ingest reads from.
**Deployment patterns**
| Bucket Location | Cross-Region Write | Cross-Region Read | Notes |
| ------------------------------------- | --------------------------------- | --------------------------------- | -------------------------------------------------------------------------------- |
| **Same as VPC** | No | Yes, unless VPC is in `us-east-1` | Best for low-latency writes; one cross-region hop. |
| **`us-east-1` (Fusion ingest)** | Yes, unless VPC is in `us-east-1` | No | One cross-region hop on write; zero on read. |
| **Neither same as VPC nor us-east-1** | Yes | Yes | Two cross-region hops—write and read—double the cross region data transfer fees. |
### 2. IAM Policy and Custom Role for Vectra to read flow logs from your S3
In order for Vectra to automatically ingest flow logs from AWS, it needs to have permissions to fetch objects from S3.
#### Option 1: CloudFormation Stack
To make this process easier, we've provided the `netography-base.yaml` CloudFormation template, which can be found along with detailed instructions here:
[AWS VPC CloudFormation Stack Automation](/cloud-onboarding/aws-cloud-onboarding/netography-aws-cloudformation-automation#id-1-iam-policy-and-custom-role-for-vectra)
To deploy only the IAM roles, **follow step 1** - only deploying the roles with no lambdas.
#### Option 2: Manual Deployment
If you would rather navigate through this process manually, see the documentation below.
[AWS VPC via S3 Setup (AWS Console method)](/ingest-network-traffic-logs/flow-logs/aws-vpc-flow-logs-via-s3-aws-console-setup-method)
[AWS VPC via S3 Setup (CloudFormation method)](/ingest-network-traffic-logs/flow-logs/aws-vpc-flow-logs-via-s3-aws-cloudformation-setup-method-recommended)
Additionally, if you would like to use a SNS topic or SQS queue, these steps from the AWS Quickstart Guide also provide some additional step by step instructions:
[Create IAM policy](/cloud-onboarding/aws-cloud-onboarding/quickstart-aws/create-iam-policy)
[Create custom role](/cloud-onboarding/aws-cloud-onboarding/quickstart-aws/create-custom-role)
Note: These are optional. You can omit the optional SQS/SNS related permissions. Using SQS/SNS provides a trigger based mechanism for Vectra to read new flow log files as they are written to S3. However, the latency difference may not be that critical to your use case, and so if you are building out your own automation you can simplify things by not using the optional SQS/SNS triggers. The examples shown below also omit these for simplicity.
### 3. Enabling VPC Flow Logs and Onboarding to Fusion
There are 2 steps for ingesting VPC flow logs to Fusion that must be completed for each VPC:
1. Enable VPC flow logs in AWS for the VPC, specifying a log destination in S3 to write the flow logs to. *Refer to the next section for details on supported S3 log destinations.*
2. Ensure Fusion has a traffic source configured to read the flow logs:
1. If each VPC flow log is configured with a unique S3 log destination *(e.g. a folder or prefix is added to the S3 bucket path to differentiate it from other VPC flow logs in the same S3 bucket at the top-level directory)*, create a AWS VPC S3 traffic source in Fusion for each VPC.
2. If the same S3 log destination is used for all the VPC flow log configurations, create a AWS VPC S3 traffic source in Fusion for each unique account and region that is writing flow logs to that destinaton.
#### AWS Flow Log Configuration Requirements
To see the exact configuration required for a single AWS VPC flow log configuration, refer to one of these documentation links:
1. [Quickstart: AWS](/cloud-onboarding/aws-cloud-onboarding/quickstart-aws)
2. [AWS VPC via S3 Setup (AWS Console method)](/ingest-network-traffic-logs/flow-logs/aws-vpc-flow-logs-via-s3-aws-console-setup-method)
3. [AWS VPC via S3 Setup (CloudFormation method)](/ingest-network-traffic-logs/flow-logs/aws-vpc-flow-logs-via-s3-aws-cloudformation-setup-method-recommended)
**S3 Log Destination**
Using a single S3 bucket for multiple VPC flow log configurations across multiple VPC and accounts **IS SUPPORTED** by Fusion. When using a single bucket, there is a design choice to make between specifying a unique top-level folder in the S3 bucket (also called a prefix, as it is added before AWS writes to `AWSLogs`), or using the exact same log destination for all VPCs.
{% hint style="info" %}
**Explaining the relationship between Fusion traffic sources and AWS VPC flow log configurations**
The Fusion traffic source configuration contains the S3 bucket, folder/prefix name, account ID, and region. It then constructs the exact S3 path where flow logs are being written for that traffic source.
When using the same log destination across all flow log configurations, that path will contain all the flow logs for the account and region in the traffic source configuration. Therefore, you must create 1 traffic source per account and region that is writing flow logs to the S3 bucket.
When using a unique log destination for each flow log configuration (whether that's a unique S3 bucket or a single S3 bucket with a unique folder/prefix), that path will contain the flow logs for ONLY that one flow log configuration. Therefore, you must create 1 traffic source per flow log configuration.
{% endhint %}
#### S3 Log Destination Option 1: Differentiate flow logs by folder/prefix in the same S3 bucket
You can differentiate each flow log configuration by adding a unique folder name after the S3 bucket ARN in the flow log configuration. If you do so, then you **add a Fusion traffic source to correspond to each VPC (technically each VPC flow log configuration)**, each in its own folder.
This approach has the benefit of allowing you to uniquely configure settings on a per VPC basis within both AWS and Fusion, and maintain a 1:1 mapping between VPCs with flow logs and Fusion traffic sources.
Example: Assume you have `vpc-1` and `vpc-2` and are configuring flow logs for both VPC to write to S3 bucket `arn:aws:s3:::acme-myflowlogs-bucket`
In the AWS flow log configuration for `vpc-1` set the S3 ARN to: `arn:aws:s3:::acme-myflowlogs-bucket/flowlogs-for-vpc-1`
In the AWS flow log configuration for `vpc-2` set the S3 ARN to: `arn:aws:s3:::acme-myflowlogs-bucket/flowlogs-for-vpc-2`
AWS will then write flow logs for `vpc-1` to `acme-myflowlogs-bucket/flowlogs-for-vpc-1/AWSLogs/12345789012/vpcflowlogs/us-east-1/` and for `vpc-2` to `acme-myflowlogs-bucket/flowlogs-for-vpc-2/AWSLogs/12345789012/vpcflowlogs/us-east-1/`
You will configure 2 Fusion traffic sources for `vpc-1` and `vpc-2`.
This differentiates the flow logs by path `BEFORE` the `AWSLogs` directory that AWS writes automatically. The directory structure under `AWSLogs` changes depending on the hive prefix and hourly partitioning settings.
You do not need to use/include the VPC ID or name for that folder name as is done in this example - it can be any string that is unique across all the VPC flow logs pointing to that bucket.
#### S3 Log Destination Option 2: Use the same S3 log destination across accounts and VPCs
You can use the same S3 log destination across accounts and VPCs. If you do so, then you **add a Fusion traffic source to correspond to each unique account and region combination writing flow logs to this log destination**.
This has the benefit of being able to maintain a consistent S3 log destination across an AWS Organization.
Example: Assume you have `vpc-1` and `vpc-2` and are configuring flow logs for both VPC to write to S3 bucket `arn:aws:s3:::acme-myflowlogs-bucket`
In the AWS flow log configuration for `vpc-1`AND `vpc-2` set the S3 ARN to: `arn:aws:s3:::acme-myflowlogs-bucket`
AWS will then write flow logs for `vpc-1` to `acme-myflowlogs-bucket/AWSLogs/12345789012/vpcflowlogs/us-east-1/` and for `vpc-2` to `acme-myflowlogs-bucket/AWSLogs/12345789012/vpcflowlogs/us-east-1/` *(assuming the VPC are in same account and region; if not the number and region will differ).*
You will configure a Fusion traffic source for account `123456789012` and region `us-east-1`.
This differentiates the flow logs in different accounts and regions by the path `AFTER` the `AWSLogs` directory that AWS writes automatically. The directory structure under `AWSLogs` changes depending on the hive prefix and hourly partitioning settings.
{% hint style="danger" %}
**Limitations when using the same S3 log destination for multiple VPCs**
**Consistent VPC flow log configuration settings**
If you use the same S3 log destination, then you must ensure that all VPC flow logs configured to write to that log destination use the same configuration setting for these fields *(you can choose any setting you want, it just must be the same)*.
1. Log file format
2. Hive-compatible S3 prefix setting
3. Per Hour Partition Setting
**Fusion configuration is per traffic source (per unique account/region), not per VPC**
Fusion configuration settings like setting a sample rate and configuring tags operate at the traffic source level. When you use this approach, you will have 1 traffic source per unique account and region combination, so configuration operates at that level. If you need more granular control, such as setting a unique sample rate to an individual VPC, you need to use option 1 above (adding a prefix/folder and creating a traffic source per VPC) instead.
**Scalability limitations for high volumes**
If you will be delivering over 10,000 flow records per second to Vectra across VPCs in a single account and region (pre-sampling), please reach out to Vectra Support to discuss and agree on the right design for your environment, as there may be scalability reasons to distribute the ingest across traffic sources per VPC rather than per account/region.
{% endhint %}
### 4. AWS Route 53 DNS Ingest
In addition to ingesting VPC flow logs, Vectra Fusion also ingests Route 53 DNS resolver logs. Configuration and ingest for these logs follows a similar pattern to VPC flow logs. See [AWS Route 53 DNS Logs via S3 Setup (Console)](/ingest-network-traffic-logs/dns-logs/dns-source-aws) for more details on this support.
### 5. AWS Context Integrations
In addition to ingesting VPC flow logs, Vectra Fusion provides context enrichment for AWS through the use of [Context Integrations](/settings/data-management/context-integrations).
Refer to [AWS Context Integration](/enrich-traffic-with-context/configure-context-integrations/aws) for the additional permission requirements and options for context enrichment.
## Automating Fusion Traffic Source Creation
The single VPC steps linked above show how to create a new traffic source for a VPC in the Fusion Portal. However, if you are ingesting numerous VPC, or flow log configuration occurs as part of an automation, you can also automate this step.
{% hint style="info" %}
**Traffic Source and Flow Source mean the same thing in Fusion**
When Fusion only ingested flow logs, the term **flow source** was used, but since DNS was added to the product, not all sources are for flow, so the more generic term **traffic source** is now used. Some code and documentation may still refer to a flow source. They are the same thing and use the same API endpoints.
{% endhint %}
### Automation for creating a single Fusion traffic source
#### Option 1: Use the Vectra Fusion REST API
The API endpoints for creating, updating, and deleting a traffic source is documented here:
[Create VPC](https://docs.netography.com/api-reference/netography-apis/traffic-sources-vpcs#post-api-v1-vpc)
[Update VPC](https://docs.netography.com/api-reference/netography-apis/traffic-sources-vpcs#put-api-v1-vpc-id)
[Delete VPC](https://docs.netography.com/api-reference/netography-apis/traffic-sources-vpcs#delete-api-v1-vpc-id)
To create a new traffic source, you would construct a POST request with type `aws`.
In the Fusion API, the S3 ARN you specified earlier in the AWS flow log configuration is broken out into 2 separate fields, `bucket`, the ARN to the S3 bucket itself, and `prefix`, which is the folder name you added to end of the S3 bucket ARN to separate the directories for this flow log configuration from others.
In the previous example, we configured the S3 ARN for `vpc-1` to be `arn:aws:s3:::acme-myflowlogs-bucket/flowlogs-for-vpc-1`. In the API call, set: `"bucket": "acme-myflowlogs-bucket"` and `"prefix": "flowlogs-for-vpc-1"`
{% hint style="info" %}
**Authenticating to the API**
Before you call the `vpc` API endpoint to create a traffic source, you must authenticate to the API, which will return a bearer token that you include in the `authorization` header in subsequent calls. For details, see:[Authentication](https://docs.netography.com/api-reference/netography-apis/authentication)
You can use the shell script provided in this recipe to perform the authentication and get the bearer token to use:
🔑
curl: Authenticate to API using NETOSECRET
Open Recipe
{% endhint %}
{% tabs %}
{% tab title="cURL" %}
```
curl --request POST \
--url https://api.netography.com/api/v1/vpc \
--header 'accept: application/json' \
--header 'content-type: application/json' \
--header 'authorization: Bearer INSERT_JWT_BEARAR_TOKEN' \
--data '
{
"flowtype": "aws",
"flowresource": "s3",
"enabled": true,
"awsauthtype": "RoleARN",
"role": {
"arn": "ROLE_ARN"
},
"name": "FLOW_SOURCE_NAME",
"traffictype": "flow",
"bucket": "S3_BUCKET_NAME",
"bucketregion": "S3_BUCKET_REGION",
"prefix": "FOLDER_NAME_IF_APPLICABLE",
"region": "VPC_REGION",
"accountid": "VPC_ACCOUNT_ID",
"tags": [
"VPC_ID"
]
}
```
{% endtab %}
{% endtabs %}
Here is the curl command with example values for the fields:
{% tabs %}
{% tab title="Shell" %}
```
curl --location 'https://api.netography.com/api/v1/vpc' \
--header 'accept: application/json' \
--header 'authorization: Bearer eyJhbGciOiJSUzI1NiIsInR5cCI6IkpXVCIsImtpZCI6IlE1V1Z6Uk1CM1JxR0sxOEJDU2k3Yk1Gb0pNcUlHZTZCQlU0In0.eyJleHAiOjE3NTMwMjUyMDAsImlhdCI6MTc1MjkxODgwMCwianRpIjoiZTRlZTVjMzMtOTUzNS00YTk0LWE1ZDYtMmMwYjczNmI1MzFkIiwiaXNzIjoiaHR0cHM6Ly9hdXRoLmZha2UtcHJvZy5jb20vYXV0aC9yZWFsbXMiLCJhdWQiOiJhcGktY2xpZW50Iiwic3ViIjoiYWRtaW4tNzk4N2U2NzAtNzM1Ni00ODFhLTk5NzUtMTYyOTg5OGVkODJhIiwidHlwIjoiQmVhcmVy' \
--header 'content-type: application/json' \
--data '
{
"flowtype": "aws",
"flowresource": "s3",
"enabled": true,
"awsauthtype": "RoleARN",
"role": {
"arn": "arn:aws:iam::1234567890123:role/NetoFlowLogReader"
},
"name": "vpc-01",
"samplerate": 1,
"bucket": "neto-myflowlogs-bucket-example",
"bucketregion": "us-east-1",
"prefix": "myflowlogs-for-vpc-01",
"region": "us-east-1",
"accountid": "1234567890123",
"tags": [
"vpc-01"
]
}
```
{% endtab %}
{% endtabs %}
#### Option 2: Use the `neto` CLI tool
`neto` is a Python-based CLI tool that serves as a front-end to the REST API. It can also be useful if you are developing your own Python code to use as a reference as it has working code for interacting with these API endpoints encapsulated into a Python class. This tool is in development and is currently available from *TestPyPi* as a Python `pip` package.
`neto` documentation and links to install the Python package are available at:
Here are examples of how you can use `neto` from a shell:
{% tabs %}
{% tab title="shell" %}
```shell
> neto aws traffic create -h
usage: neto aws traffic create [-h] [--prefix PREFIX] [--name-prefix NAME_PREFIX] --vpcid VPCID --region REGION --accountid ACCOUNTID --rolearn ROLEARN --logbucket LOGBUCKET
options:
-h, --help show this help message and exit
--prefix PREFIX Folder prefix for the S3 logs. This is the path in the bucket where logs will be stored.
--name-prefix NAME_PREFIX
Prefix for the traffic source name
--vpcid VPCID VPC ID
--region REGION AWS region
--accountid ACCOUNTID
AWS account ID
--rolearn ROLEARN AWS role ARN
--logbucket LOGBUCKET
Log bucket
> neto aws traffic create --prefix /vpc-1234/ --name-prefix neto --vpcid vpc-1234 --region us-east-1 --accountid 123456789 --rolearn arn:aws:iam::123456789:role/NetoFlowLogReader --logbucket neto-one-for-all
INFO: neto v1.1.10 - Netography Fusion CLI tool
INFO: Using profile DEFAULT
INFO: Authenticating to Netography Fusion API for qa-customer at https://api.netography.com/api/v1
INFO: Successfully authenticated to Netography Fusion API for qa-customer at https://api.netography.com/api/v1
INFO: ++++ Successfully added flow source neto-123456789-vpc-1234 to Netography Fusion
> neto aws traffic delete -h
usage: neto aws traffic delete [-h] [--name-prefix NAME_PREFIX] --vpcid VPCID --accountid ACCOUNTID --region REGION
options:
-h, --help show this help message and exit
--name-prefix NAME_PREFIX
Traffic source name prefix
--vpcid VPCID VPC ID
--accountid ACCOUNTID
AWS account ID
--region REGION AWS region
> neto aws traffic delete --name-prefix neto --vpcid vpc-1234 --accountid 123456789 --region us-east-1
INFO: neto v1.1.10 - Netography Fusion CLI tool
INFO: Using profile DEFAULT
INFO: Authenticating to Netography Fusion API for qa-customer at https://api.netography.com/api/v1
INFO: Successfully authenticated to Netography Fusion API for qa-customer at https://api.netography.com/api/v1
INFO: Retrieved 2 Netography Fusion traffic sources for account qa-customer
INFO: Deleted Netography Fusion flow source 924227113
INFO: Deleted flow source for VPC vpc-1234
```
{% endtab %}
{% endtabs %}
#### Option 3: Use Python
**3a. Minimal Python code to interact with API**
This recipe provides basic Python code you can call to authenticate to the API and create a traffic source.
🦉
Create a Traffic Source in Python
Open Recipe
**3b. Instantiate a Python class to interact with Fusion API**
This recipe provides a subset of the Python class, NetoAPI, that you can use to interact with the API. This is effectively the same thing as 3a, but separates out the API code.
🦉
NetoAPI Python class to create traffic sources in Fusion
Open Recipe
### Triggering Fusion Traffic Source Creation in AWS
The previous section covered how to create a single Fusion traffic source programatically. For building your own automation, the next step is to have whichever method you choose to use triggered when you create a new VPC flow log in AWS (and for the complete lifecycle, this should also cover when a flow log configuration is modified or deleted).
{% hint style="info" %}
**This example differentiates flow logs by prefix (S3 log destination option 1)**
If your preferred design is to use a consistent S3 log destination (S3 log destination option 2 above), you will need to adjust the examples to omit the prefix and create a traffic source per account/region instead of per VPC.
{% endhint %}
#### Option 1. Lambda-backed custom resource in CloudFormation Stack
If you are using CloudFormation to create VPCs and/or configure flow logs, you can use a Lambda-backed custom resource to call a Python function as part of the CloudFormation stack. **This will then be applied to all newly created VPCs, and will work regardless of how the CloudFormation stack itself is deployed.** If you are using AWS Service Catalog to deploy a CloudFormation stack to create new VPCs and configure flow logs already, you can add the final step of creating the Fusion traffic source for the VPC with this approach.
More information on this stack, and detailed instructions for installation can be found here: [https://docs.netography.com/docs/netography-aws-cloudformation-automation](/cloud-onboarding/aws-cloud-onboarding/netography-aws-cloudformation-automation). Follow the instructions to install the `Flow` feature. If you have already installed the base StackSet from the previous step, simply modify it when following the associated prerequisite steps.
{% hint style="warning" %}
**The CloudFormation example is not meant to be used without modification**
The example contains two CloudFormation templates that demonstrate how you can use CloudFormation to create a VPC, configure VPC flow logs, and onboard them to Vectra Fusion. These templates are intended to provide an example for an engineer familiar with CloudFormation to integrate into their existing automation workflows.
If you are looking for a complete end-to-end solution that does not require CloudFormation expertise, consider using the Vectra Cloud Onboarding Automation for AWS Organizations instead.
{% endhint %}
#### Option 2. Custom Lambda linked to EventBridge VPC Creation event
The example in the previous option includes a Lambda function that can be executed to create a new Fusion traffic source for a VPC. Instead of triggering that Lambda via a CloudFormation Lambda-backed custom resource, it can be triggered by an EventBridge VPC Creation event.
The 2 events to configure these triggers are:
```
vpc_create_event_pattern = {
"source": ["aws.ec2"],
"detail-type": ["AWS API Call via CloudTrail"],
"detail": {
"eventSource": ["ec2.amazonaws.com"],
"eventName": ["CreateVpc"],
},
}
delete_vpc_event_pattern = {
"source": ["aws.ec2"],
"detail-type": ["AWS API Call via CloudTrail"],
"detail": {
"eventSource": ["ec2.amazonaws.com"],
"eventName": ["DeleteVpc"],
},
}
```
Vectra's Cloud Onboarding Automation for AWS Organizations uses this method, deploying a CloudFormation StackSet via Terraform. It serves as a fully built out production quality example for how to configure AWS to trigger a Lambda for these events and Lambda code for performing the full lifecycle including deletions.
#### Option 3. Adapting a custom automation from Vectra’s Cloud Onboarding Automation for AWS Organizations
If you are concerned about the overall complexity of Vectra's full onboarding automation, even if you configure it to only execute a subset of its capabilities, it may still serve as a good working example of how to use CloudFormation, EventBridge, Lambda, and the Fusion API to build out your own automation.
## Automating Fusion Context Creation
If you would like to automatically add context integrations for all accounts to see asset labels within Vectra, you can follow the instructions for installing the `Context` feature here: [https://docs.netography.com/docs/netography-aws-cloudformation-automation](/cloud-onboarding/aws-cloud-onboarding/netography-aws-cloudformation-automation). Be sure to modify the base StackSet as described.
# AWS VPC CloudFormation Stack Automation
Use CloudFormation to onboard AWS VPC resources into Vectra Fusion.
If your company is using CloudFormation Stacks to manage and deploy VPC resources across your AWS organization, this guide should serve as a starting point for onboarding new devices to Vectra Fusion and importing existing EC2 asset information as context labels.
### 0. Prerequisites
Vectra offers several deployment variations depending on your organization's needs.
| Feature | Description |
| -------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Basic | Creates role needed to manually add Flow Sources to Vectra Fusion. |
| Flow/DNS | All of Basic + A stack to create a VPC with a lambda-backed custom resource, automatically uploading *new* VPCs to Vectra Fusion. Optionally enable Route53 DNS query logging via the `DnsLogsEnabled` parameter to upload query logs as well. |
| Context | All of Basic + A stackset with a lambda-backed custom resource, automatically creating context integrations for all AWS accounts. |
#### For all deployments
1. Add the following policy to the bucket where flow logs and/or DNS logs are stored. If you have an existing policy, you can add the statements directly (ensure it does not conflict). Replace
`BUCKET_NAME` with the name of your logging bucket and
`ROOT_ORG_ID` with your AWS organization ID.
{% tabs %}
{% tab title="JSON" %}
````
```
{
"Version": "2012-10-17",
"Id": "AWSNetoLogDeliveryPolicy",
"Statement": [
{
"Sid": "AllowRoute53ResolverandFlowLogging",
"Effect": "Allow",
"Principal": {
"Service": [
"delivery.logs.amazonaws.com",
"route53resolver.amazonaws.com"
]
},
"Action": [
"s3:PutObject",
"s3:GetBucketAcl",
"s3:ListBucket"
],
"Resource": [
"arn:aws:s3:::BUCKET_NAME",
"arn:aws:s3:::BUCKET_NAME/*"
],
"Condition": {
"StringEquals": {
"aws:SourceOrgID": "ROOT_ORG_ID"
}
}
}
]
}
```
````
{% endtab %}
{% endtabs %}
2. Assuming you have obtained a
`NETOSECRET` from the Vectra portal, add it to AWS secrets manager like so:
{% tabs %}
{% tab title="Shell" %}
````
```
aws secretsmanager create-secret \
--name NETOSECRET \
--description "Vectra API credentials" \
--secret-string $NETOSECRET
```
````
{% endtab %}
{% endtabs %}
1. If you have not done so already, you need to setup `SELF_MANAGED` permissions for AWS. Follow the instructions here to deploy both the `AWSCloudFormationStackSetAdministrationRole` and `AWSCloudFormationStackSetExecutionRole` in the logging account (where you will deploy the Vectra stackset).
### 1. IAM Policy and Custom Role for Vectra
The first step is to deploy a CloudFormation stack that creates the necessary IAM roles and stacksets, depending on your deployment setup. These roles allow Vectra to read flow logs from your S3 buckets and, if you choose to automate, deploy the necessary resources for automatic traffic and DNS source creation. It also can deploy a Lambda to create context integrations automatically.
To make this process easier, we've provided the `netography-base.yaml` CloudFormation template at . When deploying the CF template, you should see these options:

1. First, set a name for your Stack. For the sake of this example, we're calling it `NetographyBase`.
2. Navigate to `Settings > AWS Custom Trust Policy` inside Vectra Fusion to find your `VectraExternalID`. Enter that in the corresponding field.
1. If you do NOT wish to deploy either lambda, set `DeployFlowlogLambda` and `DeployContextLambda` to `false` and create the stack. *Once the stack completes, check the output to get your RoleARN. You should be good to start adding sources to Fusion! Skip the rest of these steps.*
3. Copy your organization ID as shown below inside `AWS Organizations`, and paste it inside `OrganizationID`.

5. While inside AWS Organization, also grab the `Root` id which should look something like `r-123456`. Copy that and paste inside the `RootId` parameter.
6. Set the `DeploymentRegions` to all the regions you want to ingest Flow and DNS logs from.
7. If you wish to enable DNS query logging, in the `DNS Logging Settings` section set `ResolverQueryLogConfigBucketName` to the name of an S3 bucket where Route53 query logs will be stored. Logs will be saved under `vpc-dns-logs/` in that bucket.
8. Deploy the stack!
The CloudFormation template will create a role with the following permissions if `DeployFlowAndDNSLambda` is set to false:
| Role | Description | Permission (Scope) |
| ---------- | ---------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------- |
| VectraRole | Role Vectra assumes to read flow logs from S3 into Fusion. |
|
{% hint style="warning" %}
**🚧This scope can (and should) be limited to the buckets you intend to read flow logs from. To do so, edit the YAML file directly.**
{% endhint %}
### 2. Flow - Automatically onboarding new VPCs into Vectra Fusion
If you are using CloudFormation to create VPCs and/or configure flow logs, you can use a Lambda-backed custom resource to call a Python function as part of the CloudFormation stack. **This will then be applied to all newly created VPCs, and will work regardless of how the CloudFormation stack itself is deployed.** If you are using AWS Service Catalog to deploy a CloudFormation stack to create new VPCs and configure flow logs already, you can add the final step of creating the Fusion traffic source for the VPC with this approach.
Once you've deployed the IAM policy and custom role for Vectra, you can deploy the `vpc-cf.yaml` template found here:
{% tabs %}
{% tab title="Shell" %}
```
aws cloudformation create-stack \
--stack-name $VPC_STACK_NAME \
--template-body file://../examples/vpc-cf-template/vpc-cf.yaml \
--parameters \
ParameterKey=VpcCidr,ParameterValue=10.0.0.0/16 \
ParameterKey=CentralizedLoggingAccountId,ParameterValue=$CENTRALIZED_ACCOUNT_ID \
ParameterKey=EnableDnsLogging,ParameterValue=False
```
{% endtab %}
{% endtabs %}
### 3. DNS - Automatically onboarding new DNS sources into Vectra Fusion
DNS logging can be enabled with a modified version of the same command (assuming the base stack has been deployed in Fusion).
{% tabs %}
{% tab title="Shell" %}
```
aws cloudformation create-stack \
--stack-name $VPC_STACK_NAME \
--template-body file://../examples/vpc-cf-template/vpc-cf.yaml \
--parameters \
ParameterKey=VpcCidr,ParameterValue=10.0.0.0/16 \
ParameterKey=CentralizedLoggingAccountId,ParameterValue=$CENTRALIZED_ACCOUNT_ID \
ParameterKey=EnableDnsLogging,ParameterValue=False
ParameterKey=ResolverQueryLogConfigID,ParameterValue=$RESOLVER_QUERY_LOG_CONFIG_ID
```
{% endtab %}
{% endtabs %}
#### Notes on deploying this example
* The `NetographyBase` stack must be deployed before any VPC stacks.
* If you delete the roles stack, all VPC stacks will fail until roles are recreated.
* S3 permissions are set to `"*"` in this example to allow access to any bucket across all VPCs; this should be restricted to the actual set of bucket(s) that are required in a production deployment.
#### Cleanup
To remove these stacks if you are testing a deployment:
1. Delete all VPC stacks first:
{% tabs %}
````
```
aws cloudformation delete-stack --stack-name my-vpc-1
aws cloudformation delete-stack --stack-name my-vpc-2
# ... etc
```
````
2. Then delete the base stack:
{% tabs %}
````
```
aws cloudformation delete-stack --stack-name NetographyBase
```
````
### 3. Context - Automatically adding AWS Context Information to Vectra Fusion
Vectra Fusion supports ingesting EC2 device info as context labels, which are then linked to relevant IPs and flow traffic. To enable this deployment, when deploying the `NetographyBase` stack toggle `DeployContextLambda` to `true`.
Once the stack instances have been deployed, you should see context integrations populate inside of Vectra Fusion!
# Vectra Terraform / CloudFormation StackSet Cloud Onboarding Automation for AWS Organizations
{% hint style="info" %}
This page is a mirror from the private Github repo for Vectra Fusion's cloud onboarding automation. For direct access to this github repo or a release package of it, reach out to your Vectra contact.
{% endhint %}
## Overview
The automation can perform these functions for onboarding AWS (you may choose to use all or a subset of these):
1. Deploy all the infrastructure required to integrate to Fusion across multiple accounts and regions in an AWS organization.
2. Enable and configure VPC flow logging to S3 based on a policy and tags that defines which VPC are in scope.
3. Add VPCs configured for flow logging to Vectra Fusion as traffic sources.
4. Push AWS context labels to Vectra Fusion for context enrichment.
5. Monitor for VPC changes and trigger enabling, configuring, and onboarding to Fusion new VPCs that are in scope.
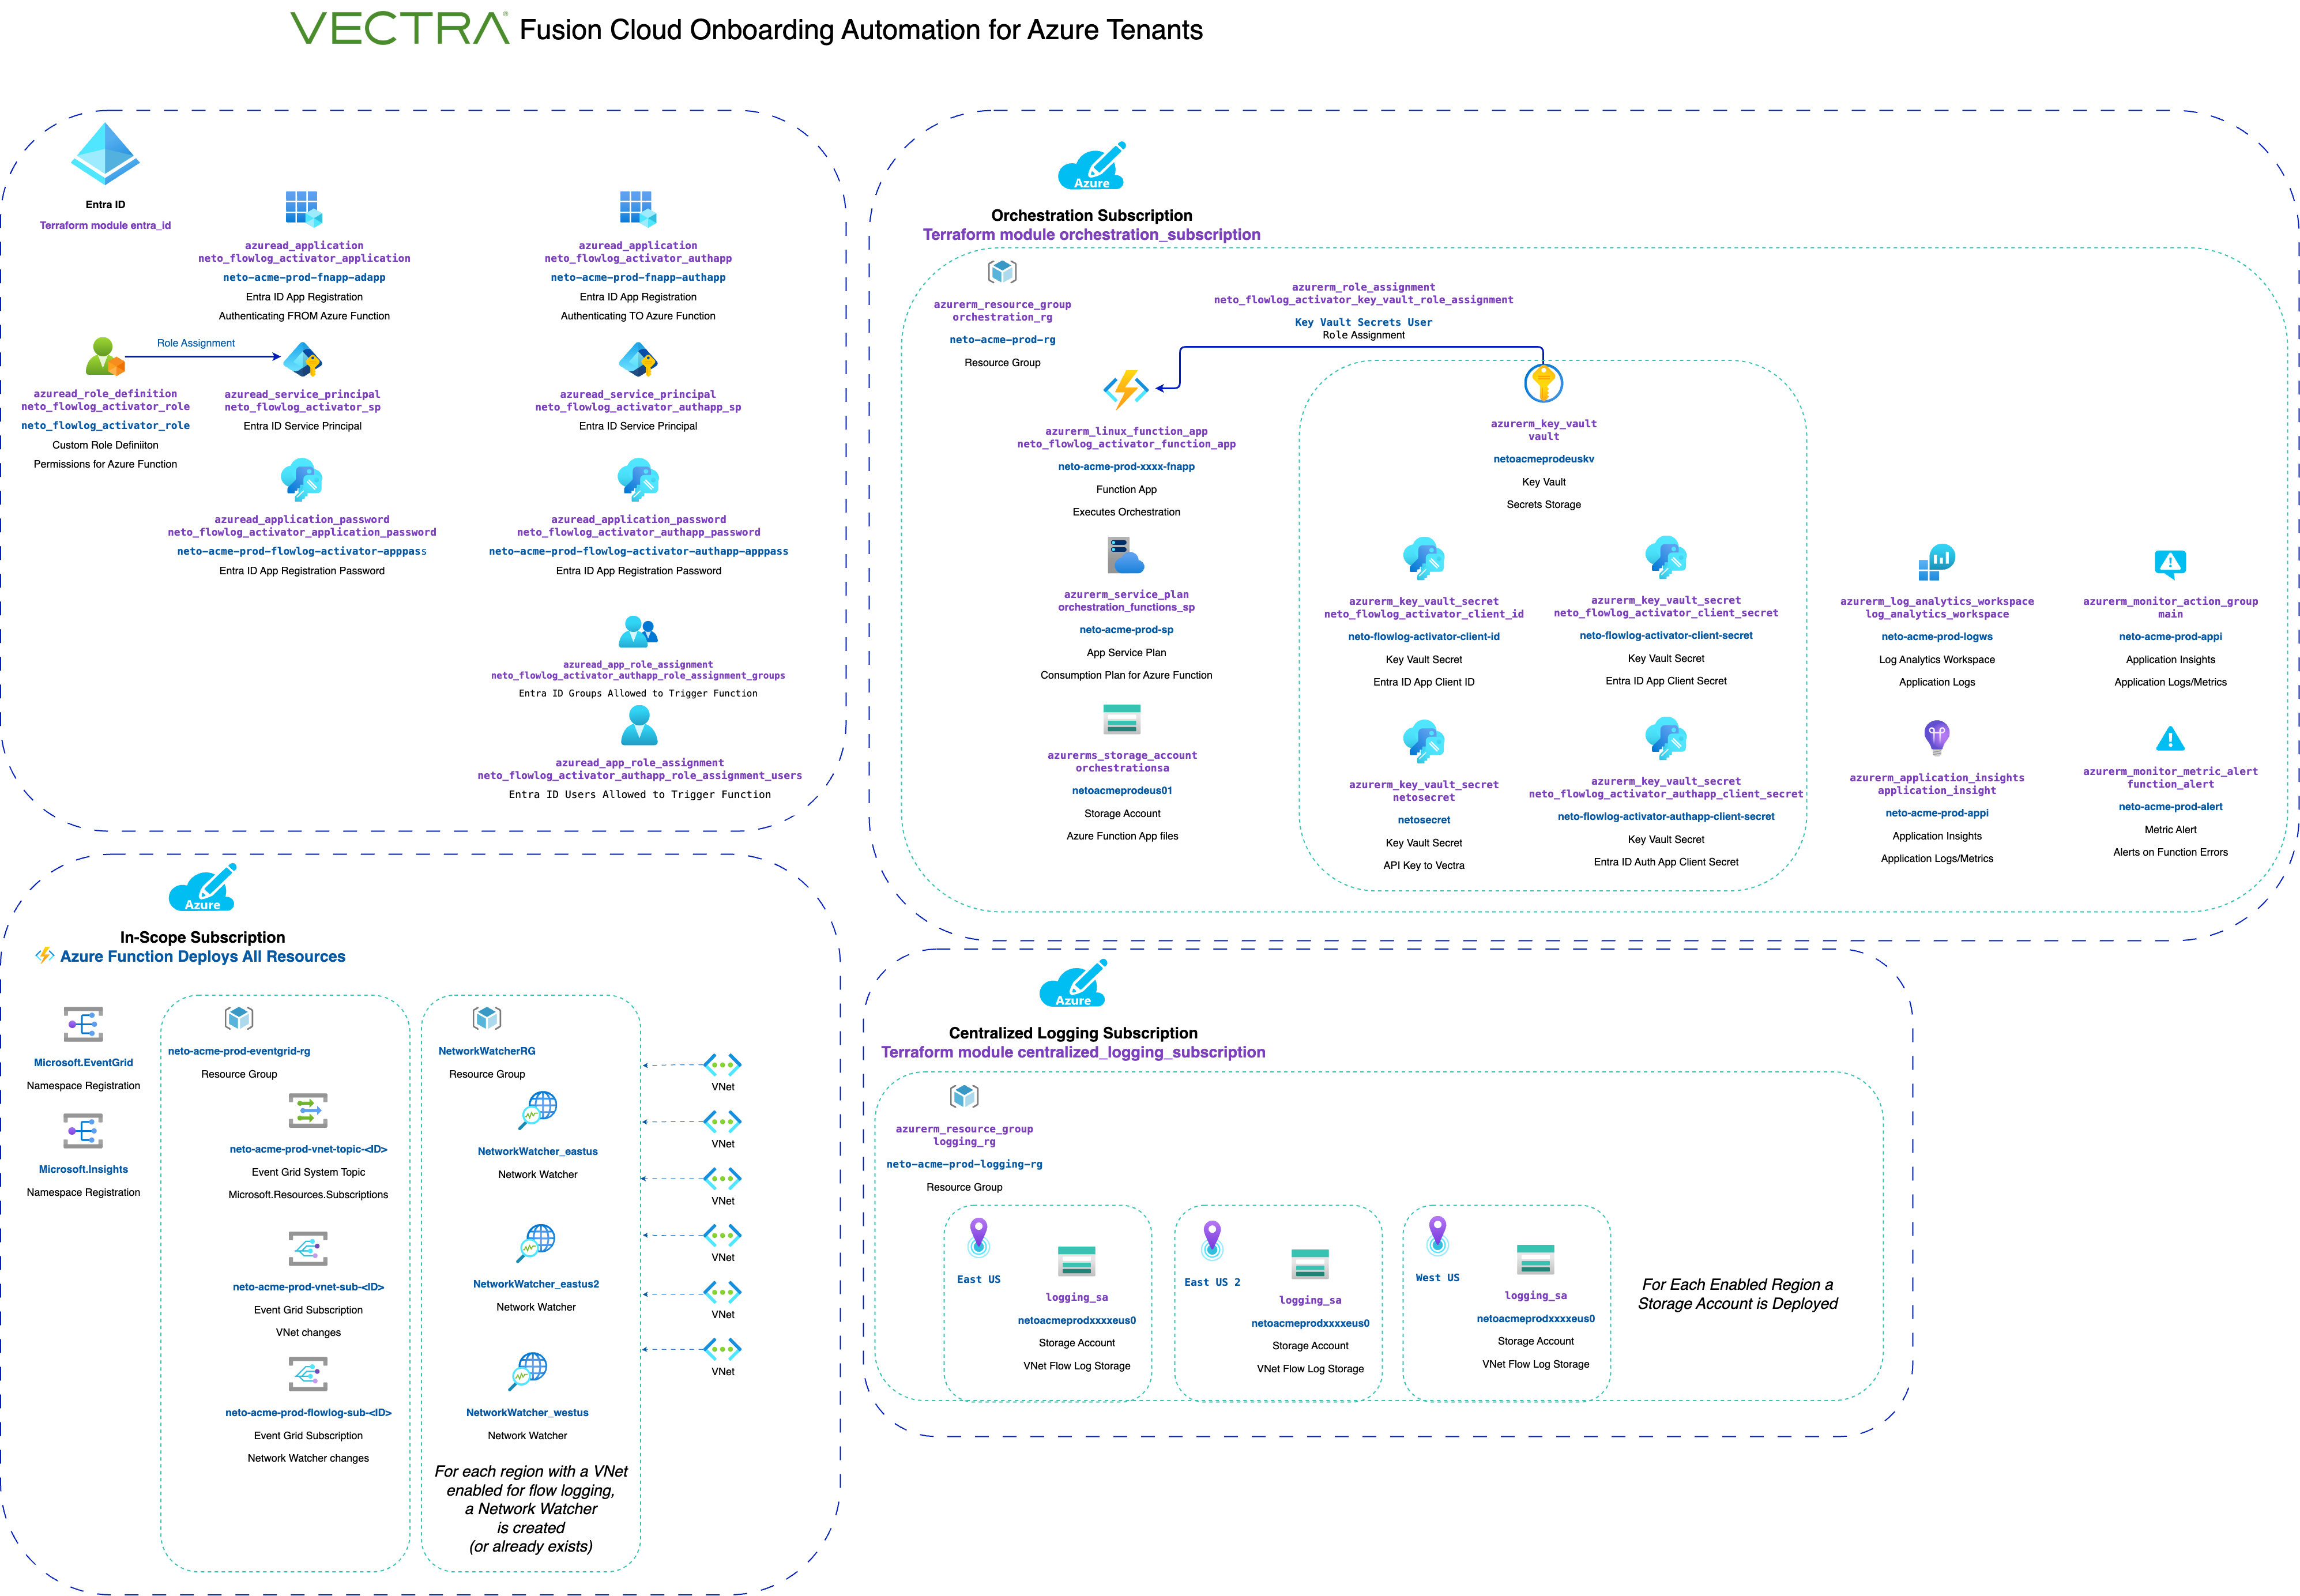
## Architecture Diagram
## Deployment Components
### Terraform deployment
* `aws/terraform/deployments/neto-onboard-aws-full` - terraform to deploy the modules below; all configuration is set here
* `aws/terraform/deployments/vectra-onboard-aws-cfn` - Vectra CloudFormation-oriented deployment path that can be run with Terraform or launched manually in the AWS console from hosted template URLs
### Terraform modules
* `aws/terraform/modules/hub_orchestration_account` - deploys the Lambda function and EventBridge event bus to automatically enable flow logs, add the flow source to Vectra Fusion, and send AWS resource context to Fusion for context enrichment.
* `aws/terraform/modules/centralized_org_logging_account` - create an s3 bucket per AWS region in this account to store logs. Using a separate bucket per region reduces cost.
* `aws/terraform/modules/management_account` - applies the CloudFormation StackSet to the management account for the AWS organization, which then deploys the necessary permissions and events in each child account in the organization.
### CloudFormation Templates
* `aws/cloudformation` - CloudFormation templates used by AWS onboarding deployments, including the versioned StackSet templates used by the full Terraform deployment.
* `aws/cloudformation/cfn_only` - CloudFormation templates used by the CloudFormation-only deployment.
### AWS Lambda Function
* `NetoFlowLogActivator` - the Lambda function discovers changes in VPCs, enables (or disables) flow logs, enables (or disables) Route53 dns logs, adds (or removes) flow sources to Vectra Fusion, and if `context_enrichment` is enabled, discovers resources associated with IP addresses and sends context to Fusion. It is triggered by EventBridge upon a VPC change, runs on a schedule, and/or is manually triggered.
### Terraform Deployment and Modules README
* `terraform/deployments/neto-onboard-aws-full/README.md`
* `terraform/deployments/vectra-onboard-aws-cfn/README.md`
* `terraform/modules/hub_orchestration_account/README.md`
* `terraform/modules/centralized_org_logging_account/README.md`
* `terraform/modules/management_account/README.md`
## Prerequisites
To simplify checking and configuring prerequisites, a set of scripts are provided in the `scripts/` directory that wrap the `aws` CLI.
See `scripts/README.md` for more details on the scripts. It assumes you have `aws` installed and configured with a profile that has the necessary permissions to run the script actions.
### 1. Account administrator access on the AWS organization management account
Required to deploy the CloudFormation StackSet.
### 2. AWS Organization has `all features` enabled
AWS Organizations with only consolidated billing features can not be used (see ).
### 3. AWS Accounts designated as the orchestration hub account and centralized logging account
You need to create or identify the AWS accounts in your organization that you want to use for the orchestration hub (where the Lambda function is created) and the centralized logging (where the S3 buckets for each region are created that flow logs are written to).
You can use the same account for orchestration and logging if you prefer.
### 4. AWS Regions enabled
The default settings apply to all commercially available regions (both standard and opt-in regions) (excluding `cn` and `gov` partitions). This can be modified in the tfvars `logging_regions` variable. See the *AWS Regions* section below for more details.
The logging account and hub orchestration account must have:
1. Every opt-in region set in `logging_regions` enabled. You must manually enable the opt-in regions in the account.
2. STS active in every region. STS is active by default in all regions, but can be manually disabled in standard regions (opt-in regions will always have STS active and can not be disabled). If it has been manually disabled by any standard regions, you must re-enable it.
### 5. Service control policy (SCP) permits automation deployment and orchestration
If you have a service control policy applied to your AWS organization, it could restrict the permissions of the automation to create the resources it needs to work, even if you are an account administrator. This could require updating the service control policy to give the automation the permissions required. See the **AWS Roles** section below for more details.
### 6. Vectra Fusion API Key (`netosecret`)
You will need to create a Vectra Fusion API key. See: [API Keys](/settings/user-management/index#user-management---api-keys)
This value is set in `terraform.tfvars` (or via an environment variable) and terraform will store it in AWS SSM as the `netosecret` parameter in the orchestration account.
Store and export it in your environment for using later in the deployment:
```sh
export NETOSECRET=your-api-key
```
On a Mac, you can copy it from your clipboard directly by running:
```sh
export NETOSECRET=$(pbpaste)
```
### 7. Vectra Fusion CLI tool
It is helpful to use the neto CLI tool as part of deploying to validate its operation. This package is in the repo `/neto/` directory.
See `../neto/README.md` for more details.
To install this into a Python virtual environment (recommended - this will ensure you don't have any conflicts, and allows you to run `neto` wheneveer you have activated this environment):
From the root of repo directory `neto-onboarding/`, run:
```sh
python3 -m venv venv
source venv/bin/activate
cd neto
pip install .
neto --version
neto -h
```
To exit the virtual environment, run `deactivate`.
To enter the virtual environment again, from repo root `neto-onboarding` run `source venv/bin/activate`.
### 8. Basic terraform knowledge
This automation has been built for engineers with basic familiarity using terraform.
## AWS Regions
The automation can detect, enable, and onboard VPC flow logs in all available commercially available regions (excluding `cn` and `gov` partitions). Regions to include are defined in the `logging_regions` variable in your `terraform.tfvars` file. Ensure that all opt-in regions included in `logging_regions` are enabled in your logging account.
If you remove regions from the `logging_regions` variable, you may wish to ensure you have another control in place that restricts the ability to enable new regions or VPCs in new regions (i.e. a service control policy is in place with region restrictions) in order to prevent a coverage gap.
#### Removing a region from automation
If you do not want to monitor all default regions, you can select a subset of regions to deploy to by modifying `logging_regions` in your tfvars.
#### Adding a new region to automation
As AWS adds new regions, Vectra will add them to the automation. When this occurs, follow these steps:
1. Enable the new region in the logging account.
2. Update to the latest `neto-onboarding` version that includes the new region.
3. Add the new region to the `logging_regions` variable in your tfvars (if you are not using the default value).
4. Re-deploy the automation.
If you ever need to manually add a region, follow these steps:
1. In `aws/terraform/modules/centralized_org_logging_account/main.tf`, add a module block for the new region, following the pattern of the existing regions.
2. In `aws/terraform/modules/centralized_org_logging_account/provider.tf`, add a provider block for the new region, following the pattern of the existing regions.
3. Add the new region to `logging_regions` in your tfvars.
4. Re-deploy the automation.
#### DNS Query Logging Regions
If the `ingest_dns` terraform variable is enabled, the automation will enable DNS query logging in the same regions as flow logs are enabled. However, some regions in AWS do not support query logging (ususally the newest regions). To exclude these regions, use the `dns_exclude_regions` variable in your tfvars file. The default should be sufficient for most cases.
## Configuring the scope of OUs and Accounts to onboard
### Scope Policy
The scope policy determines whether an account is in-scope for orchestration. The scope policy is defined in JSON, containing a list of rules. To make every account in your AWS organization in scope, add the Root OU to the scope policy. Example scope policies are provided in the `aws/terraform/deployments/neto-onboard-aws-full` directory. Copy one of these to `scope-policy.json` and edit it to define the OUs and accounts in scope for your deployment.
Each rule has a **type** (`OU` or `Account`), **action** (`include` or `exclude`), and **members** (list of IDs).
```json
{
"comment": "Sample AWS scope policy.",
"tip": "Run 'neto policy validate --file scope-policy.json' to validate the policy after changing it.",
"policy": [
{
"comment": "Rule to include all accounts that are descendants of an OU in members list. Use the Root OU to include all accounts",
"format-help": "Use the OU ID",
"type": "OU",
"action": "include",
"members": [
"ou-zzzz-abcdefg123",
"ou-zzzz-hijklmn456"
],
},
{
"comment": "Rule to include specific accounts.",
"format-help": "Use the ID of the account",
"type": "account",
"action": "include",
"members": [
"999999999999",
"999999999999",
],
}
]
}
```
Policy rules are always inherited, with the most closely scoped rule to the account having precedence (eg account rules take precedence over a rule for its parent OU which takes precedence over a rule for the root OU.)
### Configuring VPC and Subnet Scope
Within an account rule, you can use **subpolicies** to control which VPCs and subnets are in scope, and to override configuration at the VPC or subnet level. Subpolicy rules are evaluated against VPCs and subnets discovered in each in-scope account.
Each subpolicy rule has a **type** (`vpc` or `subnet`), **members** (list of VPC or subnet IDs), and a **config** block. Subnet rules also require a **vpc** field to specify which VPC the subnet belongs to, and can optionally include a **regions** field to restrict the rule to specific regions.
#### Excluding a VPC
To exclude a specific VPC from onboarding, add a subpolicy rule with `"enable": false` in the config:
```json
{
"type": "account",
"action": "include",
"members": ["123456789012"],
"subpolicy": [
{
"type": "vpc",
"members": ["vpc-0abc123def456"],
"config": {
"enable": false
}
}
]
}
```
#### Setting flow sampling per VPC
To set a specific flow sampling rate for a VPC:
```json
{
"type": "account",
"action": "include",
"members": ["123456789012"],
"config": {
"flowSampling": 0.1
},
"subpolicy": [
{
"type": "vpc",
"members": ["vpc-0abc123def456"],
"config": {
"flowSampling": 0.5
}
}
]
}
```
#### Subnet-level configuration
Subnet rules require a **vpc** field and can optionally restrict to specific **regions**:
```json
{
"type": "account",
"action": "include",
"members": ["123456789012"],
"subpolicy": [
{
"comment": "Override sampling for a specific subnet",
"type": "subnet",
"vpc": ["vpc-0abc123def456"],
"members": ["subnet-0aaa111bbb222"],
"config": {
"flowSampling": 0.3
}
},
{
"comment": "Only applies to subnets in us-east-1",
"type": "subnet",
"vpc": ["vpc-0abc123def456"],
"members": ["subnet-0aaa111bbb222"],
"regions": ["us-east-1"],
"config": {
"flowSampling": 0.4
}
}
]
}
```
Subpolicy rules are evaluated in order. The first matching rule wins. If no subpolicy matches, the account-level config applies.
## Deploying the full automation
{% stepper %}
{% step %}
## 1. Apply `neto-onboard-aws-full` Terraform Project
* This terraform project is targeted towards your organization's management, orchestration, and centralized logging accounts
* From the root directory of this repository: `cd aws/terraform/deployments/neto-onboard-aws-full`
* Change the `backend.tf` file to the backend your organization uses
* `cp terraform.tfvars.template terraform.tfvars` and define the variables in the file.
* `cp scope-policy.json.example scope-policy.json` and define the OUs and accounts in scope for your deployment.
* `terraform init`
* `terraform apply`
{% endstep %}
{% step %}
## 2. Onboarding existing VPCs
* Trigger the `FlowLogActivator` Lambda (it will be named `ACCOUNTID--NetoFlowLogActivator` to execute in the hub orchestration account to evaluate all VPCs in all configured regions in all child accounts in the organization (or in the targeted OUs if you specified a list of OUs during deployment) and to enable, configure, and on-board VPC flow logs for all in scope VPCs.
You can either use `scripts/run` or the AWS console to trigger the function and view the logs.
Simple all in one onboarding:
```sh
scripts/run all
```
Step by step onboarding:
```sh
# Start log tail (run this in separate terminal to keep logs visible)
scripts/tail -c &
# Initial onboarding of accounts
scripts/run onboard
read -p "Press enter to continue once function execution completes"
# Get logs and review after execution completes
scripts/log -n 15 -c
read -p "Press enter to continue to next step once you have reviewed the logs"
# Initial orchestration of flow logs
scripts/run orchestrate
read -p "Press enter to continue once function execution completes"
# Get logs and review after execution completes
scripts/log -n 15 -c
```
```sh
Usage: ./run [options] [aws options]
Triggers the AWS Lambda function to run
Commands:
all Run full flow log activator (onboarding, orchestration, offboarding) and context enrichment function
onboard (or 1) Onboarding step 1: Create EventBridge rules in each region in in-scope accounts
orchestrate (or 2) Flow log orchestration for onboarded accounts
context (or 3) Context enrichment for onboarded accounts
offboard (or 4) Offboarding of out of scope accounts (disable flow logs, remove EventBridge rules)
destroy Destroy all resources created by function (complete offboarding before a terraform destroy)
show Show the current AWS account, region, function name, and log group
Options:
-a Target a single account for the function run (default: all in-scope accounts)
-s Synchronous execution (default: asynchronous)
-v Verbose output
-h, --help Show this help message
-- [aws options] Additional options to pass to the AWS CLI
Ensure that your AWS CLI is configured with the correct profile and region where the Lambda function is deployed.
```
From AWS Console:
* From your AWS hub orchestration account, go to the Functions page of the AWS Lambda console (), choose the `FlowLogActivator` function, Test`tab, under`Test event`select`Create new event\`, and use the following event JSON:
```json
{
"detail-type": "Scheduled Event"
}
```
* View the logs by going to CloudWatch Logs and selecting the log group that ends in `-FlowLogActivator`.
#### Live tail the function logs
Start a live tail of the function logs before triggering the function, by opening a new terminal and running `scripts/tail`.
```sh
Usage: ./tail [options] -- [AWS options]
View logs related to AWS Lambda functions.
Options:
-i Use AWS interactive mode for live log tail
-f Pretty text format for logs (default)
-t Unparsed text format for logs
-j JSON format for logs
-c Enable color output for logs (only applies with -f)
-k KEYWORDS Highlight specified keywords in color (implies -f and -c)
-e Show only ERROR logs
-w Show WARNING and ERROR logs
-p Print function name, log group, and other AWS details
-v Enable verbose output
-h Show this help message
-- [AWS options] Additional options to pass to the AWS CLI
Environment Variables:
NETO_FORMAT Output format (default: pretty). Valid values: pretty, json, text.
NETO_COLOR Set to True to enable color output for logs by default.
NETO_THEME Color theme for parsed logs (default: basic). Use python3 --list-themes to view themes.
NETO_KEYWORD Additional keywords to highlight in parsed logs (adds to -k).
Tips:
- Ensure your AWS CLI is configured with the correct profile and region where the Lambda function is deployed.
```
#### Review logs after function executes
You can get the logs from command line using `scripts/log` or using CloudWatch Logs in the AWS Console.
```sh
Usage: ./log [options] -- [AWS options]
View logs from AWS Lambda functions.
Options:
-n MINUTES Shortcut for --after MINUTESm --before 0m
--after DURATION Start offset from now (e.g. 2h15m means "from 2h15m ago")
--before DURATION End offset from now (e.g. 30m means "until 30m ago", default: 0m)
-o OUTPUT_FILE Specify output file name (default: neto-aws-TIMESTAMP.log)
-s Save logs but do not view output (default: save and view output)
-f Pretty text format for logs (default)
-t Unparsed text format for logs
-j JSON format for logs
-c Enable color output for logs (only applies with -f)
-k KEYWORDS Highlight specified keywords in color (implies -f and -c)
-e Show only ERROR logs
-w Show WARNING and ERROR logs
-v Enable verbose output
-h Show this help message
-- [AWS options] Additional options to pass to the AWS CLI
Environment Variables:
NETO_FORMAT Output format (default: pretty). Valid values: pretty, json, text.
NETO_COLOR Set to True to enable color output for logs by default.
NETO_THEME Color theme for parsed logs (default: basic). Use python3 --list-themes to view themes.
NETO_KEYWORD Additional keywords to highlight in parsed logs (adds to -k).
NETO_CLI_PAGER Pager for output (default: code if available, else less). Use cat to disable paging.
Tips:
- To remove color from logs generated with -c, use:
awk '{ gsub(/\x1b\[[0-9;]*m/, ""); print }' neto.log
- Ensure your AWS CLI is configured with the correct profile.
- Example window: --after 2h15m --before 30m
```
{% endstep %}
{% step %}
## 3. Running Context Enrichment One Time
Context enrichment should be run on a scheduled basis, but before enabling the schedule, it is prudent to run it and verify that it is fully working.
To run context enrichment manually:
```sh
scripts/run context
```
{% endstep %}
{% step %}
## 4. Enabling Schedules
Once the initial onboarding of existing VPCs is complete and you have tested the context lambda is properly populating context labels into Fusion, you should enable the Lambda function to run on a scheduled basis.
In `terraform.tfvars` set `enable_schedule = true`. The schedule interval is defined by `lambda_schedule` (default: hourly).
When the Lambda runs on a schedule it will onboard new in-scope accounts, orchestrate VPCs (supplementing event triggers to ensure nothing is missed), remove Fusion flow sources for inactive VPCs that exceed the `inactive_vpc_timeout`, and if `context_enrichment = true`, discover new and changed resources and deliver updated context labels to Fusion.
{% endstep %}
{% step %}
## 5. Tear Down
Command Line:
* Trigger the function by running `scripts/run destroy`
* Note: This will disable the `NetoFlowLogTagTimerRule` before triggering the function, to prevent the next scheduled run from re-onboarding resources. You can re-enable the scheduler by running `aws events enable-rule --name NetoFlowLogTagTimerRule`.
* WARNING: Terraform will not re-enable the scheduler when running an apply if it is disabled via the `aws` CLI. If you disable it by running destroy, then re-onboard resources, the scheduler will be disabled until you manually enable it.
AWS Console:
* To avoid the scheduled Lambda from re-onboarding resources when it runs on a schedule the next time, first go to EventBridge in the AWS Console, select Buses, Rules, then select the `NetoFlowLogTagTimerRule` and click *Disable*.
* From your AWS hub orchestration account, go to the Functions page of the AWS Lambda console (), choose the `FlowLogActivator` function, Test`tab, under`Test event`select`Create new event\`, and use the following event JSON:
```json
{
"detail-type": "Offboard Event"
}
```
After this completes, run `terraform destroy` to remove remaining resources.
{% endstep %}
{% endstepper %}
### Deploying only context enrichment (without flow log orchestration)
If you only want to deploy context enrichment (i.e., you already have onboarded your flow logs or have separate automation to manage that), follow the same deployment steps above but set these feature toggles in `terraform.tfvars`:
```
ingest_flow = false
orchestrate_flow = false
context_enrichment = true
```
Then follow steps 3-4 to run context enrichment manually and enable the schedule.
## Configuration Options
### `inactive_vpc_timeout`
Traffic sources will be created in Vectra Fusion when flow logs are enabled for a VPC. However, you may have many VPCs (such as default VPCs) in your AWS organization that do not generate any traffic. In this case, Fusion will be continually polling looking for flow logs for VPCs that have never produced flow logs and may never.
To limit the traffic sources in Fusion to only active VPCs with flow logs, the `inactive_vpc_timeout` is used to check each VPC that has been previously enabled by the automation to see if it has ever generated any flow logs (by identifying if the directory structure is created by AWS upon writing the logs to the log bucket). If a VPC has a traffic source in Fusion, but has never generated a flow log in AWS, it will be removed from Fusion after this timeout period.
If an inactive VPC generates flow logs at any point in the future, the automation will identify that and re-add the VPC as a traffic source to Fusion on its next scheduled function run.
To disable this behavior, set `inactive_vpc_timeout = 0` in the `terraform.tfvars`.
### `ingest_dns`
If you want to ingest DNS query logs from Route 53, set `ingest_dns = true` in the `terraform.tfvars`. This will enable DNS query logging in the same regions as flow logs are enabled. Some regions do not support DNS query logging, and these are excluded by default. If you want to exclude additional regions, set the `dns_exclude_regions` variable in the `terraform.tfvars` to a list of regions to exclude.
### AWS Roles
The automation creates and uses the following roles. Please note that if you have Service Control Policy (SCP) policy in your organization, you need to add these roles and their permissions to the allowlist (see below).
| Roles | Policy | Accounts | Purpose |
| ------------------------------------- | --------------------------------------- | --------------------- | ----------------------------------- |
| `NetoListOrgAccountsAssumeRole` | `NetoListAccountsPolicy` | Management Account | List accounts in the organization |
| `NetoFlowLogActivatorRole` | `NetoFlowLogActivatorPolicy` | Orchestration Account | Assume into accounts to orchestrate |
| `NetoFlowLogBucketValidatorRole` | `NetoS3AccessPolicy` | Logging Account | Check if logs exist in S3 buckets |
| `NetoFlowLogReader` | `NetoS3AccessPolicy` | Logging Account | Allow Vectra to read logs |
| `NetoFlowLogHubAssumeRole` | `NetoVPCFlowLogEnablerPolicy` | In-Scope Accounts | Enable flow logs, read context |
| `NetoFlowLogTagSpokeRuleDeliveryRole` | `NetoFlowLogTagSpokeRuleDeliveryPolicy` | In-Scope Accounts | Send events to hub event bus |
#### Management Account Role
* `NetoListOrgAccountsAssumeRole` - Created in the AWS organization management account. This role allows the Lambda function in the Hub Orchestration Account to assume it to list accounts in the organization/OUs to operate against. The policy for this role is:
```json
statement {
actions = [
"organizations:ListAccounts",
"organizations:ListAccountsForParent",
"organizations:ListOrganizationalUnitsForParent",
"organizations:ListChildren"
]
resources = ["*"]
}
```
#### Hub Orchestration Account Role
* `NetoFlowLogActivatorRole` - Role the Flow Log Activator Lambda function runs as. It gives `sts:AssumeRole` permissions to the `NetoFlowLogHubAssumeRole` in in-scope accounts and `NetoListOrgAccountsAssumeRole` in the management account.
#### Logging Account Roles
* `NetoFlowLogReader` - Role assumed by Vectra Fusion in Vectra's AWS account to read flow logs from S3.
* `NetoFlowLogBucketValidatorRole` - Role assumed by FlowLogActivator Lambda function to read the S3 buckets to check if logs have been written to the bucket for a VPC.
#### In-Scope / Child Account Roles
The roles for child accounts are created by the `NetoIntegrationStackSet` CloudFormation StackSet `cloudformation/vectra_stackset_14.yaml` that is automatically deployed to all accounts within the tfvars `scope_root_ou` OU. This is what gives permissions throughout the organization to perform orchestration.
* `NetoFlowLogHubAssumeRole` - Role assumed by FlowLogActivator Lambda function to enable flow logs for the VPC, describe assets to retrieve context, and create EventBridge rules to trigger the function.
* `NetoFlowLogTagSpokeRuleDeliveryRole` - Role used to send EventBridge events to the hub orchestration account Event Bus when a VPC is created, deleted, or tagged.
#### Service Control Policy (SCP)
If you receive an error indicating you are `not authorized to perform` an action due to `service control policy`, you need to add `Allow` statements to your service control policy to allow the automation to perform those actions. In addition to allowing the initial automation resources to be created, you may also need allow the actions defined in the IAM policies for the roles described in the **AWS Roles** section.
The permissions described below are intended as a starting point for adjusting your organization's Service Control Policy, and you should ensure you fully understand the intended behavior and changes to a Service Control Policy before applying.
For the `hub_orchestration_account` terraform:
```json
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "AllowRequiredServicesForTerraform",
"Effect": "Allow",
"Action": [
"iam:CreateRole",
"iam:PutRolePolicy",
"lambda:CreateFunction",
"lambda:AddPermission",
"lambda:InvokeFunction",
"logs:CreateLogGroup",
"logs:PutMetricFilter",
"cloudwatch:PutMetricAlarm",
"sns:CreateTopic",
"sns:SetTopicAttributes",
"sns:Subscribe",
"cloudwatch:PutRule",
"cloudwatch:PutTargets",
"events:PutRule",
"events:PutTargets",
"events:CreateEventBus",
"events:PutEventBusPolicy",
"sts:AssumeRole",
"ec2:CreateVpc",
"ec2:DeleteVpc",
"organizations:ListAccounts"
],
"Resource": "*"
}
]
}
```
For the `centralized_org_logging_account` terraform:
```json
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "AllowS3AndRelatedServices",
"Effect": "Allow",
"Action": [
"s3:*",
"iam:CreateRole",
"iam:AttachRolePolicy",
"iam:PutRolePolicy",
"iam:PassRole",
"cloudwatch:PutMetricAlarm",
"logs:CreateLogGroup",
"logs:CreateLogStream",
"logs:PutLogEvents",
"organizations:ListAccounts"
],
"Resource": "*"
}
]
}
```
For the `management_account` terraform:
```json
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Action": [
"cloudformation:CreateStackSet",
"cloudformation:CreateStackInstances",
"cloudformation:DeleteStackInstances",
"cloudformation:DeleteStackSet",
"cloudformation:DescribeStackSet",
"cloudformation:DescribeStackSetOperation",
"cloudformation:ListStackInstances",
"cloudformation:UpdateStackSet",
"cloudformation:UpdateStackInstances",
"iam:CreateRole",
"iam:DeleteRole",
"iam:GetRole",
"iam:PassRole",
"iam:PutRolePolicy",
"iam:AttachRolePolicy",
"iam:DetachRolePolicy",
"iam:DeleteRolePolicy",
"organizations:ListAccounts",
"organizations:ListAccountsForParent",
"sts:AssumeRole",
"s3:*"
],
"Resource": "*"
}
]
}
```
See:
### S3 Prefixes
* Each VPC's flow log is represented as a single flow source in Vectra. When a flow source is created in AWS, it is automatically configured to send to a specific prefix in the S3 Bucket matching the region where that flowlog is coming from. This prefix is then used to create the Flow Source in Vectra Fusion so that Fusion can look in that specific prefix for the flow source for that VPC.
* Example: Your company is called `netocustomer` and the environment you want to apply this automation to is `production`. The `centralized_org_logging_account` would create a bucket for each AWS commercial region. One such bucket will be called `netocustomer-neto-production-us-east-1`. This assumes you assign the `customer_name` variable to `NetoCustomer` and the `environment` variable `production`.
* VPC `vpc-09e7a3a9639646404` in Region `us-east-1` is created in account `208426436839`.
* The flow logs will be sent to the S3 prefix `s3://netocustomer-neto-production-us-east-1/208426436839/us-east-1/vpc-09e7a3a9639646404`
# Quickstart: AWS
Getting started with Amazon AWS
The quickstart guide for AWS shows step by step instructions on how to on-board a single VPC to Fusion.
### How Fusion integrates to AWS
Netography Fusion has the following integration points to AWS:
1. **Fusion ingests VPC flow logs from AWS.**
2. **Fusion ingests asset context from AWS for context enrichment.**
3. **Fusion ingests Route 53 DNS resolver logs from AWS.**
### Video Guides
See the AWS [🎥 Video Guides](/cloud-onboarding/aws-cloud-onboarding/quickstart-aws/video-guides-1) to watch videos of the setup steps.
### Steps to integrate to AWS
Each page in these instructions will walk you through the steps to integrate AWS with Netography Fusion using the AWS Console:
* Create an S3 bucket
* Create an SNS topic
* Create an SQS queue - using the provided JSON to create an Advanced Access Policy
* Subscribe the SQS queue to the SNS topic
* Create custom IAM permissions using the provided JSON
* Create an IAM user
* Create an Access Key
* Create an event notification for the SQS queue
* Enable VPC flow logs via CloudShell using the provided CLI command
* Add AWS VPC flow logs as a traffic source in Netography Fusion
* Add permissions for context enrichment integration
* Enable context integration
* Enable DNS query logging in AWS
* Add Route53 DNS query logs as a traffic source in Netography Fusion
### Additional AWS setup options
The AWS quick start guide is for manually configuring your first AWS account to integrate into Fusion using the AWS console and CloudShell. If you have multiple accounts or want to explore other setup options, you can also integrate to AWS using CloudFormation, with Kinesis instead of S3, using AWS Transit Gateway flow logs instead of VPC flow logs.
* [AWS VPC via S3 Setup (CloudFormation method)](/ingest-network-traffic-logs/flow-logs/aws-vpc-flow-logs-via-s3-aws-cloudformation-setup-method-recommended)
* [AWS VPC via S3 Setup (AWS Console method)](/ingest-network-traffic-logs/flow-logs/aws-vpc-flow-logs-via-s3-aws-console-setup-method)
* [AWS VPC via Kinesis Setup](/ingest-network-traffic-logs/flow-logs/aws-vpc-flow-logs-via-kinesis)
* [AWS S3 Transit Gateway Flow Logs](/ingest-network-traffic-logs/flow-logs/aws-transit-gateway-flow-logs)
{% hint style="info" %}
**🤖Using Terraform to automate onboarding**
Access Netography's Terraform automation at our GitHub repo: . For access to the repo, email with your GitHub ID or with a request for access to the latest release package.
Netography provides a Terraform project, `neto-onboarding,` that provides Netography Fusion Cloud Onboarding Automation for AWS Organizations, Azure Tenants, and GCP Organizations.
This automation provides the following capabilties, which you can use in whole or part:
* Enables and configure AWS VPC flow logs, Azure VNet flow logs, and GCP VPC flow logs based on a simple policy and tags that defines which VPC/VNet are in scope.
* Deploy all the infrastructure required to integrate to Fusion across multiple accounts (AWS), subscriptions (Azure), and projects (GCP) in a single deployment
* Adds VPCs/VNets configured for flow logging to Netography Fusion as traffic sources.
* Deploys a single AWS Lambda function, Azure Function, or Google Function that provides context enrichment across all the accounts/subscriptions/projects as an outbound push from your cloud to the Fusion API, eliminating the need to add context integrations from the Fusion portal, to grant Netography permissions to directly enumerate resource properties, or to add individual context integrations in Fusion for each cloud account.
* Monitor for VPC/VNet changes and trigger enabling and configuring flow logs, and onboarding to Fusion new VPCs/VNets that are in scope, and offboarding VPCs/VNets that are removed or no longer in scope.
{% endhint %}
# Video Guides
Below is a video series based on the steps in the Quickstart: AWS guide for Flow Log Ingestion , Context Enrichment , and DNS Ingestion . These videos augment the written guides but can't replace them
Below is a video series based on the steps in the [Quickstart: AWS](/cloud-onboarding/aws-cloud-onboarding/quickstart-aws) guide for **Flow Log Ingestion**, **Context Enrichment**, and **DNS Ingestion**.
These videos augment the written guides but can't replace them; you'll still need to reference them throughout the setup process.
### Integrating AWS VPC Flow Logs with Fusion
{% embed url="" %}
### Adding AWS Context Integration for Context Enrichment in Fusion
{% embed url="" %}
### Integrating AWS Route 53 DNS resolver logs to Fusion
{% embed url="" %}
# Create S3 bucket
Navigate to S3 in the AWS console Create a bucket. Note: You'll want to create the S3 bucket in same region as your VPC. Give your bucket a name. Leave all settings as default, or follow the policies
1. Navigate to S3 in the AWS console

2. Create a bucket.\
Note: You'll want to create the S3 bucket in same region as your VPC.

3. Give your bucket a name.\
Leave all settings as default, or follow the policies set by your organization.

5. Scroll to the bottom and click **Create bucket**

6. Save the S3 bucket ARN in a text file. This will come in handy later.

# Create the SNS topic
Navigate to SNS in the AWS console Create a topic Leave all settings as default and click Create Topic Save the SNS topic ARN in a text file. This will come in handy later.
1. Navigate to SNS in the AWS console

2. Create a topic

3. Leave all settings as default and click **Create Topic**

4. Save the SNS topic ARN in a text file. This will come in handy later.

# Create the SQS queue
Navigate to SQS in the AWS console Create a queue Give the queue a name Under Configuration , Set Message retention to 1 day Under Access policy , click Advanced . Delete the default JSON in the Advan
1. Navigate to SQS in the AWS console

2. Create a queue

3. Give the queue a name

4. Under **Configuration**, Set **Message retention** to **1 day**

5. Under **Access policy**, click **Advanced**.

6. Delete the default JSON in the Advanced Access policy.
7. Copy and paste in the following JSON, changing `` to be the name of the S3 bucket you created in an earlier step.
{% tabs %}
{% tab title="JSON" %}
```json
{
"Version": "2012-10-17",
"Id": "PushMessageToSQSPolicy",
"Statement": [
{
"Sid": "allow-sns-to-send-message-to-sqs",
"Effect": "Allow",
"Principal": {
"AWS": "*"
},
"Action": "sqs:SendMessage",
"Resource": "*",
"Condition": {
"StringLike": {
"aws:SourceArn": "arn:aws:s3:::"
}
}
}
]
}
```
{% endtab %}
{% endtabs %}
The result should look like this:

{% hint style="info" %}
**Leave all other settings set as default, or follow the policies set by your organization.**
{% endhint %}
8. Click **Create queue**

9. Save the SQS queue ARN in a text file. This will come in handy later.

# Subscribe to Amazon SNS topic
After you've completed the previous step of creating the SQS queue, you'll find the Subscribe to Amazon SNS topic button on the lower half of the Amazon SQS page. Click Subscribe to Amazon SNS topic S
After you've completed the previous step of creating the SQS queue, you'll find the **Subscribe to Amazon SNS topic** button on the lower half of the **Amazon SQS** page.
1. Click **Subscribe to Amazon SNS topic**

2. Select the **SNS topic** you created in a previous step from the dropdown menu and click **Save**

# Create IAM policy
Navigate to IAM in the AWS console Under Access management in the sidebar menu click Policies Click Create policy Select the JSON tab and delete the default text. Copy and paste in the JSON below. Rep
1. Navigate to IAM in the AWS console

2. Under **Access management** in the sidebar menu click **Policies**

3. Click **Create policy**

4. Select the **JSON** tab and delete the default text.
5. Copy and paste in the JSON below. Replace `` with the SQS ARN you saved in an earlier step.\
Using the example from this document `` would be replaced with `arn:aws:sqs:us-east-2:307946633993:netflow1-queue`. Replace `` with your S3 bucket name created in a previous step.
{% tabs %}
{% tab title="JSON" %}
```json
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "VisualEditor0",
"Effect": "Allow",
"Action": [
"sqs:DeleteMessage",
"sqs:GetQueueUrl",
"sqs:ReceiveMessage",
"sqs:GetQueueAttributes",
"s3:ListBucket*",
"s3:GetObject*",
"s3:DeleteObject*"
],
"Resource": [
"",
"arn:aws:s3:::/*",
"arn:aws:s3:::"
]
}
]
}
```
{% endtab %}
{% endtabs %}
6. The result should look like the following

7. Click **Next**

8. Give the policy a name

9. Click **Create policy**

# Create custom role
On the IAM page under Access management in the sidebar menu click Roles Click Create role Select AWS account You're going to need Vectra's Account ID and the custom External ID created in your Fus
1. On the **IAM** page under **Access management** in the sidebar menu click **Roles**

2. Click **Create role**

3. Select AWS account

4. You're going to need Vectra's **Account ID** and the custom **External ID** created in your Fusion account for the next step
These settings can be found in Vectra Fusion, under **Settings** -> **Overview**.

5. In AWS select **Another AWS account** before pasting in the **Account ID** you copied from Vectra Fusion, then check the box for **Require external ID** and paste in the External ID. Click **Next**.

6. Search for the policy name you created during the [Create IAM policy](/cloud-onboarding/aws-cloud-onboarding/quickstart-aws/create-iam-policy) step and check the box. **Permissions policies** should show **1**.

7. Search for AmazonEC2ReadOnlyAccess and check the box. **Permissions Policies** should show **2**.
This will add permissions for context enrichment.

8. Click **Next**

9. Give your role a name.

10. The **Trust policy** is created by default and should contain the AWS Account ID and External ID you entered earlier, nothing needs to be done here, it's just to verify everything looks correct.

11. Click **Create role**

12. Next you'll need to copy and save the ARN of your newly created role. You will need it to authenticate Vectra Fusion in a later step. Search for the name you gave your role and click your role name.

13. Copy and save your role ARN for later.

# Create an event notification
Navigate to S3 in the AWS console Click on your S3 bucket created in a previous step Click the Properties tab Scroll down to event notifications and click Create event notification Give this event a n
1. Navigate to S3 in the AWS console

2. Click on your S3 bucket created in a previous step

3. Click the **Properties** tab

4. Scroll down to event notifications and click **Create event notification**

5. Give this event a name

6. Under **Event types** select **All object create events**

7. Under **Destination** select**SQS queue** and choose the **SQS queue** created in a previous step.\
Click **Save changes**.

# Enable VPC flow logs
Navigate to VPC in the AWS console Under Resources by Region Select VPCs The next step will use the CloudShell, where you'll copy and paste a CLI command to more efficiently and accurately enable work
1. Navigate to VPC in the AWS console

2. Under **Resources by Region** Select **VPCs**

3. The next step will use the CloudShell, where you'll copy and paste a CLI command to more efficiently and accurately enable working flow log configuration for your VPC.
Flow logs will be enabled with the following settings preconfigured:
* Traffic type: ALL
* Resource ID:
* Log destination type: S3
* Max aggregation interval: 1 minute
4. Open Cloudshell\
You'll see a command prompt open up on the lower half of the screen

5. Copy and paste the command below, replace `` with the VPC ID you want to enable flow logs for, and replace `` with the name of your S3 bucket created in a previous step.
{% tabs %}
{% tab title="CLI" %}
```shell
aws ec2 create-flow-logs \
--resource-type VPC \
--resource-ids \
--traffic-type ALL \
--log-destination-type s3 \
--log-destination arn:aws:s3::: \
--log-format '${version} ${account-id} ${interface-id} ${srcaddr} ${dstaddr} ${srcport} ${dstport} ${protocol} ${packets} ${bytes} ${start} ${end} ${action} ${log-status} ${tcp-flags} ${type} ${pkt-dstaddr} ${pkt-srcaddr} ${instance-id} ${vpc-id} ${az-id} ${sublocation-id} ${sublocation-type} ${subnet-id}' \
--max-aggregation-interval 1
```
{% endtab %}
{% endtabs %}

{% hint style="warning" %}
**🚧If the log format isn't specified exactly as it is in the above command, your integration will fail.**
{% endhint %}
6. Once you've pasted in the command, it should look like this:

7. Hit the enter key to run the command.
If you see the below, your flow logs have been successfully created.\
`"Unsuccessful":[]` means you were successful and no errors were indicated.

# Add AWS as a new traffic source in Fusion
Add AWS as a traffic source in Vectra Fusion.
1. In Netography Fusion navigate to **Settings** -> **Traffic Sources** -> **Add Traffic Source**

2. Select **AWS S3 VPC**

3. Fill out the AWS S3 VPC Traffic Source flow form:
**Name:** This will be the Name of your configuration in Netography Fusion. You can use anything you like here.
**Polling:** Leave set as default which is enabled.
**Down Sample:** Leave as default unless you know how to use this feature.
**Account ID:** Your AWS Account ID
**Region:** Your AWS account **Region**
**Bucket Name:** S3 Bucket where you're sending your DNS query logs
**Bucket Region:** The **Region** of your S3 bucket
**Prefix:** S3 bucket storage location typically used if you're sharing a bucket with multiple applications or purposes
Copy your **Account ID** from the upper right dropdown in the AWS console

Under **Authentication Type** leave the toggle set to the default of **ROLE**.\
Paste in the ARN you saved during the [Create custom role](/cloud-onboarding/aws-cloud-onboarding/quickstart-aws/create-custom-role) step
Click **SAVE**

# Add context integration to Fusion
Context permissions were already granted via the Custom role created in a previous step. This document is all that is needed to enable context enrichment for AWS in Vectra Fusion. Navigate to Setti
Context permissions were already granted via the [Custom role](/cloud-onboarding/aws-cloud-onboarding/quickstart-aws/create-custom-role) created in a previous step.
This document is all that is needed to enable context enrichment for AWS in Vectra Fusion.
1. Navigate to **Settings** -> **Context Integrations** -> **Add Integration**

2. Select **Amazon Web Services**

Under **Authentication Type** leave the toggle set to the default of **ROLE**.\
Paste in the ARN you saved during the [Create custom role](/cloud-onboarding/aws-cloud-onboarding/quickstart-aws/create-custom-role) step
Click **SAVE**

# Enable DNS query logging in AWS
📘 It is recommended to create a new S3 bucket to be used only for DNS query log storage See our Create S3 bucket steps. Navigate to Route53 in the AWS console Under Resolver in the sidebar, click Que
{% hint style="info" %}
**📘It is recommended to create a new S3 bucket to be used only for DNS query log storage**
{% endhint %}
See our [Create S3 bucket](/cloud-onboarding/aws-cloud-onboarding/quickstart-aws/create-s3-bucket) steps.
1. Navigate to Route53 in the AWS console

2. Under **Resolver** in the sidebar, click **Query logging**

3. Click **Configure query logging**

4. Enter a name

5. Select **S3 bucket**
6. Enter the S3 URI to the S3 bucket to send your DNS query logs

7. Click **Add VPC**

8. Check the box of the VPCs to log DNS queries for, then click **Add**

9. Save the **VPC ID** as you'll need this later in Netography Fusion.

10. Click **Configure query logging** at the bottom of the page to save.

## Add the S3 bucket storing DNS query logs to your policy
We need to update the policy created in the [Create IAM policy](/cloud-onboarding/aws-cloud-onboarding/quickstart-aws/create-iam-policy) step to add your S3 bucket storing DNS query logs.
1. From the IAM policies page, search for your policy name, then click the + to expand it.

2. Click the **Edit** button

3. Add two new S3 entries for your DNS query logs S3 bucket, make sure you're following JSON format with proper comma syntax.

4. Click **Next**

5. Click **Save changes**

# Add DNS as a traffic source in Fusion
Navigate to Settings -\> Traffic Sources -\> Add Traffic Source Under DNS select AWS S3 VPC Fill out the AWS S3 VPC Traffic Source form: VPC ID: The VPC ID you enabled query logs for Account ID: Y
1. Navigate to **Settings** -> **Traffic Sources** -> **Add Traffic Source**

2. Under **DNS** select **AWS S3 VPC**

3. Fill out the AWS S3 VPC Traffic Source form:
**VPC ID:** The VPC ID you enabled query logs for
**Account ID:** Your AWS Account ID
**Region:** Your AWS account **Region**
**Bucket Name:** S3 Bucket where you're sending your DNS query logs
**Bucket Region:** The **Region** of your S3 bucket
**Prefix:** S3 bucket storage location typically used if you're sharing a bucket with multiple applications or purposes
Under **Authentication Type** leave the toggle set to the default of **ROLE**.\
Paste in the ARN you saved during the [Create custom role](/cloud-onboarding/aws-cloud-onboarding/quickstart-aws/create-custom-role) step
Click **SAVE**

# Azure Cloud Onboarding
{% hint style="info" %}
New to Fusion cloud onboarding? Start with [Fusion Onboarding for Cloud Engineers](/cloud-onboarding/fusion-onboarding-for-cloud-engineers) for deployment models, scope planning, and cloud-specific guidance.
{% endhint %}
Use one of these three paths to configure Azure VNet flow logs, cloud context, and onboarding to Fusion.
Choose the path that fits your environment:
* **Manual onboarding** — best for a small number of VNets or an initial PoC
* **Vectra onboarding automation** — best for large or dynamic Azure environments
* **Custom IaC automation** — best if you prefer integrating to your existing IaC
### 1. Manual onboarding
Follow step-by-step guides to configure Azure and Fusion, onboard each VNet, and add cloud context for each subscription.
**Best for**
Organizations with a small number of VNets and subscriptions that rarely change, or for an initial PoC.
**Next steps**
* [Azure Virtual network (VNet) Flow Log Setup](/ingest-network-traffic-logs/flow-logs/azure-vnet-flow-log-configuration)
* [Azure Context Integration](/enrich-traffic-with-context/configure-context-integrations/azure)
* [Quickstart: Azure](/cloud-onboarding/azure-cloud-onboarding/quickstart-azure)
### 2. Vectra Cloud Onboarding Automation for Azure Tenants
For detailed documentation, see [Vectra Terraform Cloud Onboarding for Azure Tenants](/cloud-onboarding/azure-cloud-onboarding/neto-onboarding-azure).
{% hint style="info" icon="robot" %}
**Using Terraform to automate onboarding**
Access Vectra's Terraform automation at .
For access to the repo, reach out to your Vectra contact with your GitHub ID or request the latest release package.
Vectra provides the `neto-onboarding` Terraform project for AWS Organizations, Azure Tenants, and GCP Organizations.
This automation can:
* Enable and configure AWS VPC flow logs, Azure VNet flow logs, and GCP VPC flow logs based on policy and tags
* Deploy the infrastructure required to integrate with Fusion across multiple accounts, subscriptions, or projects
* Add VPCs and VNets configured for flow logging to Vectra Fusion as traffic sources
* Deploy a single AWS Lambda, Azure Function, or Google Cloud Function for context enrichment across all in-scope environments
* Monitor for VPC and VNet changes, onboard new in-scope networks, and offboard networks that leave scope
{% endhint %}
**Best for**
Organizations that want a complete, supported, end-to-end solution for managing flow log configuration and onboarding to Fusion. This is usually the fastest path for large, dynamic, or multi-cloud environments.
**Next steps**
* Reach out to your Vectra contact and request access to the GitHub repo.
* Include your GitHub ID, or request the latest release package.
### 3. Custom IaC automation
Use your existing automation pipelines or scripts to:
* Create Azure Storage accounts or blobs for flow log delivery
* Configure the permissions Fusion needs to read flow logs from storage and read resource metadata from your Azure subscriptions
* Configure VNet flow logs on each VNet to write to Azure Storage
* Call the Fusion API to create a Fusion traffic source for each VNet and a Fusion context integration for each subscription that contains relevant resources
**Best for**
Organizations experienced with Azure IaC that already provision VNets or VNet flow log configurations through automation and want to extend that workflow to Fusion.
**Next steps**
Vectra's Cloud Onboarding Automation for Azure Tenants, described in option 2, provides example code using Terraform, Azure Functions, and Python for the full onboarding flow. Review that implementation and reach out to Vectra if you need help building custom IaC.
In addition, Fusion traffic source creation and context integration options are documented in [Vectra AWS Onboarding Guide for Cloud Automation Engineers](/cloud-onboarding/aws-cloud-onboarding/aws-configuration-automation-for-multiple-vpcs#automating-fusion-traffic-source-creation). These methods apply across clouds.
# Vectra Terraform Cloud Onboarding for Azure Tenants
{% hint style="info" %}
This page is a mirror from the private Github repo for Vectra Fusion's cloud onboarding automation. For direct access to this github repo or a release package of it, reach out to your Vectra contact.
{% endhint %}
## Overview
The automation can perform these functions for onboarding Azure (you may choose to use all or a subset of these automations):
1. Deploy all the infrastructure required to integrate with Fusion across multiple subscriptions and regions in an Azure tenant.
2. Add VNets configured for flow logging to Vectra Fusion as traffic sources.
3. Describe Azure resources across a Tenant and send to Vectra Fusion's context enrichment API.
4. Monitor for VNet changes and new subscriptions and trigger enabling, configuring, and onboarding to Fusion new VNets that are in scope.
The following table shows the setting that is used to enable or disable each major feature of the deployment.
### `tfvars` variables to disable features in the deployment
| Feature | `tfvars` variable | Value |
| ------------------------------------------------------- | -------------------- | ------- |
| Add/remove Fusion flow sources for VNets with flow logs | `ingest_flow` | `false` |
| Enable/disable VNet flow logging according to policy | `orchestrate_flow` | `false` |
| Context enrichment via Azure Function | `context_enrichment` | `false` |
| Execute Azure Function a schedule | `enable_schedule` | `false` |
| Trigger Azure Function via Event Grid upon changes | `eventgrid_enable` | `false` |
Note that if you disable both `enable_schedule` AND `eventgrid_enable`, the Azure Function will ONLY run when you manually trigger it. This may be ideal if you have other orchestration in place, and want to trigger the function only at specific points in your own CI/CD pipeline.
By setting each of these variables to false, you can strip down the operation of the orchestration to only use the features you need.
See the section [Least privilege custom role when disabling features](#least-privilege-custom-role-when-disabling-features) for information on how to adjust the custom role permissions when disabling features to provide the least privilege required for the Azure Function to operate.
## Architecture Diagram
## Components
### Terraform deployment
* azure/terraform/deployments/neto-onboard-azure-full - Terraform to deploy the modules below; all configuration is set here.
### Terraform modules
* azure/terraform/modules/orchestration\_subscription - Deployed to a designated orchestration subscription in the Azure tenant. Creates Azure Resource Group, Storage Account, Service Plan, Application Insights, Monitor Action Group, Metric Alert, Linux Function App, Storage Container, Storage Blob, and Role Assignment for the orchestration Azure Function.
* azure/terraform/modules/centralized\_logging\_subscription - Deployed to a designated centralized logging subscription in the Azure tenant. Creates a resource group and 1 Azure storage account per region in this subscription to store flow logs for retrieval by Vectra Fusion.
* azure/terraform/modules/entra\_id - This module provisions Entra ID resources including custom roles, application registrations, service principals, and role assignments necessary for Entra ID authentication and authorization, supporting the orchestration of Azure resources.
### Azure Resource Naming
Azure resources are named based on the following convention:
* You configure `customer` and `environment` values.
* Most Azure resources are named starting with `neto-$customer-$environment-` (customer and environment can be up to 8 characters but we recommend 5 to avoid seeing it truncated in places).
* The prefix `neto` is used for all Vectra resources. Although configurable in the tfvars, some of the ancillary scripts may rely on this prefix, so do not change it.
* Storage accounts and Azure key vault have a limited character length and are named using the first 5 letters of the customer and environment and abbreviations for regions.
`neto-acme-prod` is used throughout the README as the example for the resource naming. The actual resource names are based on your customer and environment settings.
### Azure Resource Groups
* `neto-acme-prod-rg` - Resource group in the orchestration subscription that contains all orchestration resources.
* `neto-acme-prod-logging-rg` - Resource group in the centralized logging subscription that contains the storage accounts for each region.
* `neto-acme-prod-eventgrid-rg` - Resource group in the in-scope subscriptions that contains the Event Grid topic and subscriptions for triggering the Azure function.
### Azure Subscriptions
* **Orchestration subscription** `orchestration_subscription_id` - The primary deployment subscription for the terraform. Azure Functions are deployed here.
* **Centralized logging subscription** `centralized_logging_subscription_id` - Storage accounts for each region are created and flow logs are written here. This can be the same subscription as the orchestration subscription if you do not want to separate them.
* **In-scope subscriptions** - All the subscriptions in the tenant meet the scope policy, as defined in tfvars by providing a list of management groups and/or subscriptions. The root management group ID can be used to include all subscriptions in the tenant. All in-scope subscriptions are onboarded by the `neto_flowlog_activator` Azure Function App.
### Azure Function App
* `azure/functions/neto_flowlog_activator` (Azure `neto-acme-prod-HASH-fnapp`)
* Triggers:
* Schedule (if `timer_enable=true`, based on schedule set in `timer_schedule`)
* Manual trigger via API endpoint `api/run`
* Event Grid subscription to `Microsoft.Network.virtualNetworks` (when a VNet is created, updated, or deleted) and `Microsoft.Network/networkWatchers` (when a flow log configuration is changed)
* *Note: New subscriptions will be onboarded at the next scheduled run of this function. There is no way in Azure to receive a trigger for this event. If you know of a way to do this that does not itself require creating a timer-based polling mechanism (such as a log query search), let us know how.*
* Functions:
### Azure Event Grid Topic and Subscriptions
* `neto-acme-prod-vnet-topic-{ID}`: `Microsoft.Resources.Subscriptions` system topic to trigger on changes to resources in the subscription. This is deployed in each in-scope subscription by the `neto_flowlog_activator` Azure Function.
* `neto-acme-prod-vnet-sub-{ID}`: `Microsoft.Network` changes for VNet creation, update, or deletion trigger the `neto_flowlog_activator` Azure Function. This is deployed in each in-scope subscription by the `neto_flowlog_activator` Azure Function.
* `neto-flowlog-subscription-{ID}`: `Microsoft.Network/networkWatchers` changes for flow log configuration changes trigger the `neto_flowlog_activator` Azure Function. This is deployed in each in-scope subscription in the tenant by the `neto_flowlog_activator` Azure Function.
### Azure Custom Role
This custom role is created in the orchestration subscription.
* `neto_flowlog_activator_role` - Custom role used to provide least privilege required for the `neto_flowlog_activator_sp` service principal
#### `neto_flowlog_activator_role` Permissions
| Permission | Description |
| ----------------------------------------------------------- | ----------------------------------------- |
| Microsoft.Authorization/roleAssignments/delete | Delete role assignments |
| Microsoft.Authorization/roleAssignments/read | Read role assignments |
| Microsoft.Authorization/roleAssignments/write | Write role assignments |
| Microsoft.Authorization/roleDefinitions/read | Read role definitions |
| Microsoft.Authorization/roleDefinitions/write | Write role definitions |
| Microsoft.Compute/virtualMachines/read | Read virtual machines |
| Microsoft.EventGrid/register/action | Register the Microsoft.EventGrid provider |
| Microsoft.EventGrid/eventSubscriptions/read | Read event grid event subscriptions |
| Microsoft.EventGrid/eventSubscriptions/write | Write event grid event subscriptions |
| Microsoft.EventGrid/extensionTopics/\* | Read/write event grid extension topics |
| Microsoft.EventGrid/systemTopics/eventSubscriptions/read | Read system topics event subscriptions |
| Microsoft.EventGrid/systemTopics/eventSubscriptions/write | Write system topics event subscriptions |
| Microsoft.EventGrid/systemTopics/read | Read event grid system topics |
| Microsoft.EventGrid/systemTopics/write | Write event grid system topics |
| Microsoft.EventGrid/topics/read | Read eventgrid topics |
| Microsoft.Insights/Register/Action | Register the Microsoft.Insights provider |
| Microsoft.Network/networkInterfaces/read | Read network interfaces |
| Microsoft.Network/networkWatchers/configureFlowLog/action | Configure flow log resources |
| Microsoft.Network/networkWatchers/flowLogs/delete | Delete flow log resources |
| Microsoft.Network/networkWatchers/flowLogs/read | Read flow log resources |
| Microsoft.Network/networkWatchers/flowLogs/write | Write flow log resources |
| Microsoft.Network/networkWatchers/queryFlowLogStatus/action | Query status of flow logs |
| Microsoft.Network/networkWatchers/read | Read network watchers |
| Microsoft.Network/networkWatchers/write | Write network watchers |
| Microsoft.Network/publicIPAddresses/read | Read public IP addresses |
| Microsoft.Network/virtualNetworks/read | Read virtual networks |
| Microsoft.Network/virtualNetworks/write | Write virtual networks |
| Microsoft.Resources/subscriptions/resourceGroups/read | Read resource groups |
| Microsoft.Resources/subscriptions/resourceGroups/write | Write resource groups |
| Microsoft.Resources/subscriptions/resources/read | Read subscriptions |
| Microsoft.Storage/storageAccounts/listkeys/action | List storage account keys |
| Microsoft.Storage/storageAccounts/read | Read storage accounts |
| Microsoft.Web/sites/Read | Read Azure Functions |
| Microsoft.Web/sites/functions/write | Write Azure Functions |
| Microsoft.Web/sites/functions/read | Read Azure Functions |
| Microsoft.managementGroups/descendants/read | Read management group descendants |
| Microsoft.managementGroups/read | Read management groups |
### Azure Application Registration
* `neto_flowlog_activator_application` (Azure `neto-acme-prod-HASH-fnapp-adapp`) - Registers an application for the `neto_flowlog_activator` Azure Function App
* `neto_flowlog_activator_authapp` (Azure `neto-acme-prod-HASH-fnapp-authapp`) - *(Only if `function_entra_auth=true`)* Provides Entra ID authentication for users to interact with the `neto_flowlog_activator` Azure Function App HTTP API endpoints
### Azure Service Principal
* `neto_flowlog_activator_sp` (Azure `neto-acme-prod-HASH-fnapp-adapp`) - Identity the `neto_flowlog_activator` Azure Function runs as
* `neto_flowlog_activator_authapp_sp` (Azure `neto-acme-prod-HASH-fnapp-authapp`) - *(Only if `function_entra_auth=true`)* Provides Entra ID authentication for users to interact with the `neto_flowlog_activator` Azure Function App HTTP API endpoints if
#### Azure Application Keys
The Azure Applications have a random key generated for it which is set in Key Vault, and read by the Azure Function to execute with its service principal identity and authenticate the application for Entra ID authentication.
* `neto_flowlog_activator_application_password` (Azure `neto-acme-prod-flowlog-activator-apppass`) - Application client secret for the `neto_flowlog_activator` Azure Function identity to access Azure resources
* `neto_flowlog_activator_application_password` (Azure `neto-acme-prod-flowlog-activator-authapp-pass`) - *(Only if `function_entra_auth=true`)* Application client secret for the `neto_flowlog_activator` to authenticate the application for Entra ID authentication of users interacting with the Azure Function App HTTP API endpoints
### Azure Key Vault
* `neto_keyvault` (Azure `netoacmeprodkv`) - Key vault created in the orchestration subscription.
#### Key Vault Secrets
* Azure application secrets for the Azure function to run as the service principal with the custom role privileges
* `neto-flowlog-activator-client-id` - Stores the client ID for the `neto_flowlog_activator` Azure Function
* `neto-flowlog-activator-client-secret` - Stores the client secret for the `neto_flowlog_activator` Azure Function
* `neto-flowlog-activator-authapp-client-secret` - *(Only if `function_entra_auth=true`)* Stores the client secret for Entra ID authentication app registration
* Vectra Fusion API key secrets
* `netosecret` - Stores the Vectra Fusion API netosecret, used to authenticate with the Vectra Fusion API.
## Prerequisites
### 1. Required Permissions
* **Global Administrator** access to the *Azure Tenant*.
* **Key Vault Administrator** access to the *Orchestration Subscription*. This is not included in **Global Administrator**.
* **Role Based Access Control Administrator** access to the *Root Tenant Management Group*. This is not included in **Global Administrator**.
*\*It may take up to 10 minutes for permissions to propagate to subscriptions in Azure. If you see permission errors when deploying, wait a few minutes and try again.*
### 2. No Azure Policy restrictions
No Azure Policy should exist that would restrict the automation from creating or using the resources described below, including role assignments and region usage. If you receive a `RequestDisallowedByPolicy` error when deploying the automation or when the Azure Function executes, you will need an Azure [Resource Policy Contributor](https://learn.microsoft.com/en-us/azure/role-based-access-control/built-in-roles/management-and-governance#resource-policy-contributor) to identify the policy rule and create an exemption. See: [Resolve errors for request disallowed by policy](https://learn.microsoft.com/en-us/azure/azure-resource-manager/troubleshooting/error-policy-requestdisallowedbypolicy?tabs=azure-cli).
### 3. Vectra Fusion API Key
Create a Vectra Fusion API key. See: [API Keys](/settings/user-management/index#user-management---api-keys)
Set the terraform variable `netosecret` to this key. It is more secure to pass this key from the environment rather than storing it in your tfvars file.
e.g. Store and export it into the environment variable `NETOSECRET` (`export NETOSECRET=$(pbpaste)` on MacOS will copy it from clipboard), then run terraform apply with argument `-var="netosecret=$NETOSECRET"`
### 4. Vectra Fusion CLI tool *(Optional)*
It is helpful to use the neto CLI tool as part of deploying to validate its operation. This package is in the repo `/neto/` directory.
See ../neto/README.md for more details
To install this into a Python virtual environment (recommended - this will ensure you don't have any conflicts, and allows you to run `neto` whenever you have activated this environment):\
From the root of repo directory `neto-onboarding/`, run:
```sh
python3 -m venv venv
source venv/bin/activate
cd neto
pip install .
neto --version
neto -h
```
### 5. Basic Terraform Knowledge
This automation has been built for engineers with basic familiarity using terraform.
## Azure Region Handling
The default settings apply the automation to all commercial regions.
To create Azure Storage Accounts in specific regions, edit the Terraform `logging_regions` variable. If you are using any regions that require special Azure support enablement or government regions, you need to update that variable.
* If a VNet flow log is in-scope for flow logging, but it is in a region that no storage account was created for, it will cause an error noting the VNet that could not be configured for flow logs and the region that is missing a storage account.
### New Region Handling
* The `logging_regions` variable default value contains all commercially available default regions as of the most recent release.
* Vectra will release updates to the automation with new Azure regions added to the `logging_regions` default value.
* Using the updated default value and run `terraform apply` to add support for new regions.
* You can also manually add a new region by adding it to the variable in your tfvars file.
## Understanding Scope in Azure
### Custom role assignable scope and service principal role assignment scope
The *Assignable Scope* for a custom role limits the ability to assign the custom role to only resources contained within the assignable scope. It is a maximum limit and does not convey any privileges to the assignable scope. The terraform creates the custom roles with an assignable scope of the *Tenant Root Group* management group, allowing them to be assigned to any management groups and subscriptions in the Azure Tenant.
If you are deploying to only a single management group below the Tenant Root Group in an Azure tenant AND want to restrict permissions so that the deployment has no permissions beyond that management group, you can set `custom_roles_assignable_scope` and `scope_root_management_group` to the management group ID. If you are configuring the deployment to only orchestrate within a single management group initially, but may expand that scope in the future, it is simpler to leave the default values for this and use the scope policy to limit the scope instead.
See: \
See:
## Understanding Scope for the Orchestration
### Scope Policy
The scope policy determines whether a subscription is in-scope for orchestration. The scope policy is defined in JSON, containing a list of rules. To make every subscription in your Azure tenant in scope, add the root tenant management group ID as a member of a single policy rule.
A rule has these values:
Each rule has a **type** (management\_group or subscription), **action** (include or exclude), **members** (list of IDs), an optional **subpolicy** section for VNet rules, and an optional **config** section for configuration parameters.
```json
{
"policy": [
{
"type": "management_group",
"action": "include",
"members": [
"MG_ID_1"
],
"config": {
"sample_rate": 5
}
},
{
"type": "subscription",
"action": "include",
"members": [
"MY_SUB_ID_1", "MY_SUB_ID_2"
],
"config": {
"sample_rate": 3
},
"subpolicy": [
{
"type": "vnet",
"members": ["my-vnet1", "my-vnet2"],
"config": {
"sample_rate": 10
},
{
"type": "vnet",
"members": ["my-vnet3", "my-vnet4"],
"config": {
"enable": false
}
}
]
}
]
}
```
Policy rules are always inherited, with the most closely scoped rule to the subscription having precedence (eg subscription rules take precedence over a parent management group rule which takes precedence over a root tenant management group level.
#### Valid `members` values
* The ID of the management group, subscription in a rule, and ID of vnet in a subpolicy rule.
#### Policy config
You can modify flow log settings for each policy rule by adding a **config** section to the rule. If a config section is present, any values set take precedence over values set in tfvars. A config section in an `"action":"exclude"` rule will apply those settings when offboarding a project due to it no longer being in scope (if the project was never onboarded, the settings will never be used).
Within a config section, the supported keys are:
* `ignore` - If set to true, no flow log configuration will be modified. Use where another system is orchestrating flow log configurations to avoid conflicts.
* `sample_rate` - Value passed to the Vectra Fusion flow source configuration
`scope-policy.json.template-simple` provides a template for a simple policy.\
`scope-policy.json.template-complex` provides a template for a more complex policy.
Copy one to `scopy-policy.json` and edit.
### Setting users and groups authorized to the HTTP endpoint
*(Only applies if `function_entra_auth=true`)*
Only users and groups set in tfvars `function_entra_auth_assigned_users` and/or `function_entra_auth_assigned_groups` can use the HTTP endpoints to trigger the function.
* `scripts/allowed-users` - This script will convert user principal names (UPNs) in format user\@domain to Azure Object IDs and output the terraform variable function\_entra\_auth\_assigned\_users with the values. Run with no arguments to see usage.
* `scripts/allowed-groups` - This script converts Azure group display names to their corresponding Object IDs and output the terraform variable function\_entra\_auth\_assigned\_groups with the values. Run with no arguments to see usage.
See the section below [Authentication and Authorization for the Azure Function HTTP endpoints](#authentication-and-authorization-for-the-azure-function-http-endpoints) for more information on authentication configuration options.
## Deployment Steps
*\*It may take up to 10 minutes for permissions to propagate to subscriptions in Azure. If you see permission errors when deploying, wait a few minutes and try again before troubleshooting further.*
> **bootstrap script**\
> The `bootstrap` script is a quick-start convenience tool designed to guide you through deploying the Vectra onboarding automation for Azure on a fresh Ubuntu 22.04 VM. It installs required dependencies, clones the GitHub repository, prompts for authentication details, deploys and runs the Terraform automation, and validates its operation. While not mandatory, it provides a streamlined way to get started and understand the setup process. For other operating systems, you may need to adapt or manually perform the initial setup steps.
>
> To use the script, download it from the following link and execute it on your VM. The script assumes you have not yet cloned the repository:\
> Netography Azure Bootstrap Script
{% stepper %}
{% step %}
## Deploying the `neto-onboard-azure-full` Terraform automation
* This terraform project is targeted towards a designated orchestration subscription in your Azure tenant. Ensure that you are in the right subscription by running `az account show` and verify the subscription ID. If the subscription is not the one you want to deploy to, run `az account set --subscription ` to set the correct subscription.
* From the root directory of this repository: `cd azure/terraform/deployments/neto-onboard-azure-full`
* Change the backend.tf file to the backend your organization uses
* Copy terraform.tfvars.template to terraform.tfvars and define the appropriate variables.
* Run `terraform init`
* Run `terraform apply` and accept the changes (`terraform apply -var="netosecret=$NETOSECRET"` if you are passing API key from environment variable)
*(If you prefer, you can use a dummy value (e.g. `REPLACEME`) in Terraform and then update the secret manually in Azure Key Vault after the deployment.)*
The input variables and resources created are described in `terraform/deployments/neto-onboard-azure-full/README.md`
After completing the terraform apply, verify all the resources were deployed successfully.
{% endstep %}
{% step %}
## Run the Azure Function
The Terraform deploys resources, but the Azure Function does most of the work. The Azure Function will not execute until you manually trigger it or it runs on a schedule.
You can trigger the Azure Function to run in one of these ways:
1. `scripts/run` - This script uses the `az` CLI and curl to trigger the Azure function.
2. Run a "Neto Azure: Run Function" task in VS Code - This will execute `scripts/run` with the appropriate arguments
3. Manually trigger the function in the Azure portal
### Onboarding in a large-scale Azure tenant
This orchestration has been deployed and tested in Azure tenants with dozens of subscriptions and thousands of VNets. If you have a relatively large Azure tenant or have mission-critical production operations running, it is good CloudOps practice to onboard in steps to validate the operation of any orchestration like this rather than in a single run. Some tips for a large deployment:
1. If you have an Azure tenant for development, staging, or testing, onboard to that tenant first to validate the operation in your environment and become familiar with its usage. If you don't have easy access to this yourself, reach out to Vectra as we can do a deployment with you in one of our isolated Azure tenants we use for training and testing.
2. Onboard in batches of subscriptions, starting with an initial small set in the scope policy, operating first on less business critical subscriptions, ensure that everything completes successfully, and then add additional subscriptions to the scope policy, redeploy, and trigger the function again. If you have logical groupings of subscriptions in management groups, adding management groups to the scope policy is a good approach for this.
3. Trigger the function when first onboarding a new set of subscriptions with `scripts/run -v onboard` to onboard the subscription without enabling flow logs, verify it completes successfully, then run `scripts/run -v all` to perform the flow logging orchestration and context enrichment in the second step.
4. Set `timer_schedule=false` in tfvars to disable the scheduled execution of the function until you complete the onboarding process.
### Running the Azure Function with the `scripts/run` script
If `function_entra_auth=false`, your logged in user with the `az` command must have permission to read the Function App function key to trigger the function with the run script.\
If `function_entra_auth=true`, your logged in use with the `az` command must have its identity specified in the list of authorized users in the Terraform configuration to trigger the function with the run script. See: [Setting users and groups allowed to authenticate to the HTTP endpoints](#setting-users-and-groups-authorized-to-the-http-endpoints).
```sh
Usage: ./run [options] -- [az options]
Triggers the Azure Function to run with the specified command.
Commands:
all Full function run (onboarding, orchestration, context enrichment, and offboarding)
onboard, 1 Onboard new subscriptions and offboard out-of-scope subscriptions only
orchestrate, 2 Onboarding, orchestration, and offboarding
context, 3 Context enrichment only
offboard Offboarding of out-of-scope subscriptions only
destroy Destroy all resources created by the function (complete offboarding first)
show Display the function details (does not trigger the function)
Options:
-s, --subscription ID Target the single subscription ID provided as argument.
--nowait Do not wait for function completion; trigger and exit
-l, --local Set if you are running the Azure Function locally for debugging (see azure/DEVELOPING.md)
-v, --verbose Enable verbose output
-h, --help Show this help message
-- [az options] Additional options to pass to the az CLI. eg: ./run all -- --debug
```
### Running the Azure Function in VS Code
Open the repository in VS Code, and then Open Command Palette (**F1** / **Cmd+Shift+P**) → **Tasks: Run Task** → **Neto Azure: Run Function (all)**
Note: The tasks marked with *(LOCALLY)* are for local development and debugging, and require additional setup to use. See `azure/DEVELOPING.md` for more information.
### Manually Triggering the Azure Function in the Azure Portal
1. In the Azure portal, navigate to the new function app deployed to the orchestration subscription at:
2. Select Functions, and choose `run` from the list of functions.
3. Wait for the Logs window at bottom of screen to say "Connected!" before proceeding in order to see the logs in real-time.
4. Click `Test/Run`. You can leave everything on this page blank.
5. Click `Run`. This will trigger the function to run.
6. Review the logs for any errors before navigating away from this page.
If you see permission errors in the logs, the permissions assigned may not have yet propagated within Azure, and simply re-running the function may resolve the issue. Wait a few minutes, and then repeat the steps to manually trigger the Azure function. If an Azure API call creating a resource fails with an error such as Internal Server Error, these are usually transient Azure issues and will succeed during the next function run. If you see a consistent error on a resource when re-running the function, escalate this to Vectra for assistance.
{% endstep %}
{% step %}
## Review the Azure Function logs
When using the `scripts/run` script, logs are output to the terminal along with a human readable status output. However, if the function takes over 230 seconds to complete (the maximum timeout for Azure HTTP endpoints), you will receive an 502 HTTP error from Azure and the logs and status will not be directly visible. In this case, you should use the `scripts/log` script to retrieve the logs from the Azure Function App, and run the function again if needed.
*It can take up to 5 minutes after the function runs to retrieve logs in Azure. If you attempt to retrieve logs and they are missing, wait a couple of minutes and try again.*
### Retrieving and viewing logs from CLI `scripts/log`
`scripts/log` retrieves the logs from the Azure Function App, parses them, and opens a viewer.
```sh
Usage: ./log [options] -- [az monitor log-analytics query options]
Collect logs from Azure using a local-clock relative window.
Options:
-n MINUTES Shortcut for --after MINUTESm --before 0m
--after DURATION Start offset from now (e.g. 2h15m means "from 2h15m ago")
--before DURATION End offset from now (e.g. 30m means "until 30m ago", default: 0m)
-o OUTPUT_FILE Specify output file name (default: neto-azure-TIMESTAMP.log)
-s Save logs but do not view output (default: saves + views)
-f Pretty text format for logs (default, uses logparser.py)
-t Unparsed text format (TSV)
-j JSON format
-c Enable color output (only applies with -f)
-k KEYWORDS Highlight specified keywords (implies -f and -c)
-e Show only ERROR logs
-w Show WARNING and ERROR logs
-v Enable verbose (debug) output
-h Show this help message
-- [az options] Additional arguments to pass to az monitor log-analytics query
Environment Variables:
NETO_FORMAT Default output format: pretty, json, or text.
NETO_COLOR Set to 'True' to enable color output by default.
NETO_THEME Color theme for parsed logs (default: basic).
NETO_KEYWORD Additional keywords to highlight (comma-separated).
Examples:
./log --after 2h15m --before 30m -c
./log -n 60 -c
./log -t -s # output logs in TSV format, save file but don't view
```
### Retrieving and viewing logs in VS Code
* Install VS Code Extension [ANSI Colors](https://marketplace.visualstudio.com/items?itemName=iliazeus.vscode-ansi) for viewing parsed logs in color: `code --install-extension iliazeus.vscode-ansi`
* VS Code: Open Command Palette (**F1** / **Cmd+Shift+P**) → **Tasks: Run Task** → **Neto Azure: Logs Last 15 Minutes (color)**
* There are additional **Neto Azure: Logs** tasks to choose from.
* If you see ANSI codes in a log: Open Command Palette (**F1** / **Cmd+Shift+P**) → **ANSI Text: Open Preview**
* The task will run the `scripts/log` script and then open the ANSI Colors Preview for the parsed log output in VS Code.
### Viewing logs in the Azure Portal
* Azure Portal - Function App:
1. In the Azure portal, navigate to the function app deployed to the orchestration subscription.
2. You can view real-time logs as the function executions by selecting `Log Stream` from the `Monitoring` section of the left-hand menu (or it may appear at top of the menu; click the star to add it to your Favorites)
3. You can view historical run logs by selecting Functions and then select `run`, and then go to the `Invocations` tab.
4. It may take up to 5 minutes for invocation logs to appear after a function executes.
* Azure Portal - Application Insights:
1. Go to Application Insights in the Azure portal, select the `neto-acme-prod-appi` resource
2. Click Logs (button at top or under Monitoring in the menu on left)
3. On right-side of query box, change drop-down from Simple mode to KQL mode.
4. In the query box enter: traces
5. Click Run button
{% endstep %}
{% endstepper %}
## Offboarding Management Group(s) or Subscription(s)
Edit your `scope-policy.json` and then `terraform apply` to modify your policy.
## Destroy (complete offboarding) the entire orchestration
You must disable the function from executing commands before running the destroy in order to prevent it from re-onboarding resources through a trigger or scheduled event during the destroy process. This is done by setting the `DESTROY` environment variable in the Function App configuration to `true`.
1. Run `scripts/update set-destroy` to set the `DESTROY` environment variable in the Azure Function App. (`scripts/update clear-destroy` will reverse this and delete it, re-enabling the function).
2. Run `scripts/run destroy` to offboard all subscriptions. Review the logs (`scripts/log`) to ensure it completed successfully, and ensure all subscriptions are offboarded (`scripts/tag -a list`).
3. Run `terraform destroy` to remove all resources created by the automation.
## Authentication and Authorization for the Azure Function HTTP endpoints
The main work of the orchestration is performed by an Azure Function App. An API endpoint is exposed by the Function App to allow manual triggering of the function. This API endpoint is secured by the Azure Function App function key (if `function_entra_auth=false`) and by an Entra ID authentication app registration (if `function_entra_auth=true`).
See the section above on [Setting users and groups allowed to authenticate to the HTTP endpoints](#setting-users-and-groups-authorized-to-the-http-endpoints) for more information on how to set users and groups authorized to use the HTTP endpoints.
### Authentication security configuration
1. HTTPS is required for all endpoints.
2. The function logs to Application Insights.
3. The `scripts/run` command uses Azure authentication through the `az` CLI to retrieve the details and authentication required to trigger the function.
If `function_entra_auth=false`:
* The function key created by Azure with the Function App can be used to trigger the function. This is retrieved by the `scripts/run` script using your user authentication credentials that have access to read this from the Function App, and is passed in the HTTP request header.
If `function_entra_auth=true`:
* You must explicitly set the users and groups authorized to use the HTTP endpoints (unless you explicitly disable this in tfvars).
* You are authenticated through Entra ID identities.
* You must have an identity in the tenant where the function app is deployed.
* You must log in to this identity using the az CLI (eg az login).
* You can not access the HTTP access with only a static function or master key to the function app.
* Azure App Service built-in authentication and authorization capabilities are used.
* The Entra ID app registration secret is stored in Azure Key Vault and accessed by the Function App through a system managed identity.
### Additional security hardening options
In addition to the default configuration, you can further harden the Azure Function by configuring the following options in your `terraform.tfvars` file.
1. Restrict the IP addresses that can access the function by setting the `function_ip_restriction` variable to `Deny` and providing a list of IP addresses in the `function_allowed_ips` variable. By default, any IP address can access the function (authentication is still required). Setting this to `Deny` conflicts with the `eventgrid_enable=true` setting, unless you add all Event Grid source IP addresses published by Azure to this IP list. Microsoft updates this list on a weekly basis, so this is not a practically supportable configuration. A refactored design of the Event Grid trigger will resolve this conflict in a future release without requiring this work.
2. Restrict the IP addresses that can deploy code to the Function App by setting the `function_scm_ip_restriction` variable to `Deny` and providing a list of IP addresses in the `function_scm_allowed_ips` variable. By default, any IP address (with authentication credentials) can deploy to an Azure Function App. The deployment itself is handled by Terraform, so setting this restriction will restrict what IPs can do an updated deployment to your existing Function App.
There are a myriad of available options in Azure for further restricting access to HTTP endpoints, including configuring different authentication providers, allowing users in other tenants to authenticate (which may be useful if you have multiple Azure tenants), Azure API management (APIM), Azure Private Endpoint, Azure Application Gateway, Azure Front Door, and more. Most of these options should be largely compatible with the Azure Function deployment if you choose to implement these yourself. You may need to manually adjust `scripts/run` or provide your own command instructions to trigger a function based on any additional hardening you implement.
### Using Entra ID authentication for the HTTP endpoint
* Enable Entra ID authentication by setting `function_entra_auth=true`. Currently, this authentication is not supported when using Event Grid triggers, so you have to choose between either enabling Event Grid or Entra ID authentication. This conflict will be resolved in an update to the orchestration in an upcoming release.
* You can allow ANY authenticated user in a tenant to use the HTTP endpoint by setting `function_entra_auth_assignment_required=false`. This is not recommended for production environments.
### Azure CLI Commands for Entra ID
These scripts are to guide you with az CLI commands if you must manually create these resources instead of using the Entra ID module included in the terraform.
Carefully read this documentation and the script before using. This should only be used if absolutely required, as it introduces multiple additional steps and opportunities for permissions to be mismatched between these settings and those managed by Terraform. To use,
* Before deploying the terraform, run the `entraid-az-commands-create.sh` script to create the necessary resources. The script will prompt you for the necessary values (press enter to use the default values). Once the script completes, copy the output values to the `terraform.tfvars` file.
* Deploy the terraform as described above.
* Once the terraform is deployed, manually add the outputted key vault secrets to the key vault in the orchestration subscription. These values are outputted after running the `entraid-az-commands-create` script, so it is advised to use two terminal windows, one for the script and one for the terraform output.
* On teardown, first run the `offboard` trigger in the Azure Function to disable flow logs and remove flow sources for all VNets. Then run the `entraid-az-commands-remove.sh` script to remove the resources created by the `entraid-az-commands-create.sh` script. Finally, run `terraform destroy` to remove all Terraform-created resources.
* `scripts/entraid-az-commands-create.sh`
* `scripts/entraid-az-commands-remove.sh`
### Least privilege custom role when disabling features
The custom role `neto_flowlog_activator_role` is deployed with privileges to execute all features of the deployment. If you disable features and will not use them in the future, you may want to edit the custom role to remove those permissions entirely in order to provide the least privilege required for the Azure Function to operate.
The custom role permissions are defined in `azure/terraform/modules/entra_id/custom_roles.tf`. The permissions that can be removed when disabling a feature are listed below:
* `ingest_flow=false` - No changes (this only affects API calls to the Vectra Fusion API)
* `orchestrate_flow=false` - `Microsoft.Network/networkWatchers/flowLogs/write`, `Microsoft.Network/networkWatchers/flowLogs/delete`, `Microsoft.Network/networkWatchers/configureFlowLog/action`, `Microsoft.Network/networkWatchers/queryFlowLogStatus/action`, `Microsoft.Network/networkWatchers/write`, `Microsoft.Network/virtualNetworks/write`
* `context_enrichment=false` - `Microsoft.Compute/virtualMachines/read`, `Microsoft.Network/networkInterfaces/read`, `Microsoft.Network/publicIPAddresses/read`, `Microsoft.Network/virtualNetworks/read`
* `eventgrid_enable=false` - `Microsoft.EventGrid/*`
## Additional Notes
If you re-apply the terraform, be sure to grant yourself `Key Vault Administrator` access to the orchestration subscription's key vault. This is not included in the `Global Administrator` role. This allows terraform to check if you updated the key vault secrets and update the Azure Functions with the new secrets.
# Quickstart: Azure
Getting started with Microsoft Azure
### How Fusion integrates to Azure
1. **Fusion ingests VNet flow logs from Azure.**
2. **Fusion ingests asset context from Azure for context enrichment.**
### Steps to integrate to Azure
Each page in these instructions will walk you through the steps to integrate Azure with Netography Fusion using the az CLI:
* Set your working subscription
* Register Microsoft Insights Provider
* Create a storage account
* Create a flow log
* Add Azure VNet as a new traffic source in Netography Fusion
* Context integration in Azure
#### Troubleshooting
**Network Watcher must be enabled (it is by default)**
If you previously chose to opt out of **Network Watcher automatic enablement**, you must manually enable Network Watcher in each region.
See: [Enable or Disable Azure Network Watcher](https://learn.microsoft.com/en-us/azure/network-watcher/network-watcher-create?tabs=portal)
**Azure Policy could restrict actions you take**
If **Azure Policy** is in use, you may be restricted from performing these steps.
A **RequestDisallowedByPolicy** error means the Global Administrator role is being overridden by Azure Policy.
See: [Resolve errors for request disallowed by policy](https://learn.microsoft.com/en-us/azure/azure-resource-manager/troubleshooting/error-policy-requestdisallowedbypolicy?tabs=azure-cli)
**You need Owner or Contributor role in your Azure subscription to complete these steps**
You'll need access to the Azure subscription(s) containing your Virtual Network(s) to be added to Netography Fusion with an `Owner` or `Contributor` role, or a custom role with the specific permissions required for each step:
* `/register/action` operation permissions to register Microsoft Insights provider is included in the `Owner` and `Contributor` roles.
* `Microsoft.Network/networkWatchers/configureFlowLog/action` permission is included in the `Owner`, `Contributor`, and `Network Contributor` roles .
* `Microsoft.Storage/storageAccounts/*` permission is included in the `Owner`, `Contributor`, and `Storage account contributor` roles.
* `/register/action` operation permissions is included in the `Owner` and `Contributor` roles.
### Additional Azure setup options
The Azure quick start guide is for manually configuring your first Azure subscription to integrate into Fusion using the Azure console and az CLI. For additional instructions, see:
* [Azure Virtual network (VNet) Flow Log Setup](/ingest-network-traffic-logs/flow-logs/azure-vnet-flow-log-configuration)
* [Azure NSG Flow Logs Setup](/ingest-network-traffic-logs/flow-logs/azure-network-security-group-flow-logs-azure-console-setup-method)
* [Azure Context Integration](/enrich-traffic-with-context/configure-context-integrations/azure)
{% hint style="info" %}
**🤖Using Terraform to automate onboarding**
Access Netography's Terraform automation at our GitHub repo: . For access to the repo, email [\[email protected\].](https://github.com/iKettles/vectra-gitbook/blob/main/cdn-cgi/l/email-protection/README.md#e3909693938c9197a38d86978c849182938b9acd808c8ecd) with your GitHub ID or with a request for access to the latest release package.
Netography provides a Terraform project, `neto-onboarding,` that provides Netography Fusion Cloud Onboarding Automation for AWS Organizations, Azure Tenants, and GCP Organizations.
This automation provides the following capabilties, which you can use in whole or part:
* Enables and configure AWS VPC flow logs, Azure VNet flow logs, and GCP VPC flow logs based on a simple policy and tags that defines which VPC/VNet are in scope.
* Deploy all the infrastructure required to integrate to Fusion across multiple accounts (AWS), subscriptions (Azure), and projects (GCP) in a single deployment
* Adds VPCs/VNets configured for flow logging to Netography Fusion as traffic sources.
* Deploys a single AWS Lambda function, Azure Function, or Google Function that provides context enrichment across all the accounts/subscriptions/projects as an outbound push from your cloud to the Fusion API, eliminating the need to add context integrations from the Fusion portal, to grant Netography permissions to directly enumerate resource properties, or to add individual context integrations in Fusion for each cloud account.
* Monitor for VPC/VNet changes and trigger enabling and configuring flow logs, and onboarding to Fusion new VPCs/VNets that are in scope, and offboarding VPCs/VNets that are removed or no longer in scope.
{% endhint %}
# Set working subscription
Access Azure Cloud Shell to run CLI commands from your web browser using az. List our Subscription IDs. az account list --output table Name CloudName SubscriptionId TenantId State IsDefault ----------
Access [Azure Cloud Shell](https://portal.azure.com/#cloudshell/) to run CLI commands from your web browser using az.
1. List our Subscription IDs.
{% tabs %}
{% tab title="Command" %}
```shell
az account list --output table
```
{% endtab %}
{% endtabs %}
{% tabs %}
{% tab title="Output" %}
```
Name CloudName SubscriptionId TenantId State IsDefault
---------------------------------- ----------- ------------------------------------ ------------------------------------ ------- -----------
neto-isolate-test-2-sub AzureCloud 15dc0802-8641-457b-a238-9442798ade29 8f72986c-9267-4bc2-8b23-20ad971c3ca3 Enabled True
neto-isolate-test-1-sub AzureCloud e987ce3f-0467-4d89-a0c3-6ca343ab8437 8f72986c-9267-4bc2-8b23-20ad971c3ca3 Enabled False
Aug3 Fusion Onboarding Walkthrough AzureCloud 53f8bc8d-3c58-44c4-a3a6-5a5b97983eee 8f72986c-9267-4bc2-8b23-20ad971c3ca3 Enabled False
neto-isolate-test-3-sub AzureCloud 9853e6d7-6b87-43a5-ba17-e9ad76a84c5b 8f72986c-9267-4bc2-8b23-20ad971c3ca3 Enabled False
Azure subscription 1 AzureCloud 0f200c75-00f0-4866-8a43-e584b393cb33 8f72986c-9267-4bc2-8b23-20ad971c3ca3 Enabled False
```
{% endtab %}
{% endtabs %}
2. Set our working Subscription.
{% tabs %}
{% tab title="Command" %}
```shell
az account set --subscription "53f8bc8d-3c58-44c4-a3a6-5a5b97983eee"
```
{% endtab %}
{% endtabs %}
# Register Microsoft Insights Provider
Access Azure Cloud Shell to run CLI commands from your web browser using az. Check if Microsoft.Insights is not yet registered. az provider show --namespace Microsoft.Insights --query "registrationSta
Access [Azure Cloud Shell](https://portal.azure.com/#cloudshell/) to run CLI commands from your web browser using az.
1. Check if Microsoft.Insights is not yet registered.
{% tabs %}
{% tab title="Command" %}
```shell
az provider show --namespace Microsoft.Insights --query "registrationState" --output table
```
{% endtab %}
{% endtabs %}
{% tabs %}
{% tab title="Output" %}
```
Result
------------
Unregistered
```
{% endtab %}
{% endtabs %}
2. Register Microsoft.Insights
{% tabs %}
{% tab title="Command" %}
```shell
az provider register --namespace Microsoft.Insights
```
{% endtab %}
{% endtabs %}
3. Verify Microsoft.Insights has been registered successfully.
{% tabs %}
{% tab title="Command" %}
```shell
az provider show --namespace Microsoft.Insights --query "registrationState" --output table
```
{% endtab %}
{% endtabs %}
{% tabs %}
{% tab title="Output" %}
```
Result
----------
Registered
```
{% endtab %}
{% endtabs %}
# Create a storage account
Access Azure Cloud Shell to run CLI commands from your web browser using az. Create a Storage account in the same region as your Virtual Network . List your Virtual Networks , their Resource groups ,
Access [Azure Cloud Shell](https://portal.azure.com/#cloudshell/) to run CLI commands from your web browser using az.
### Create a **Storage account** in the same region as your **Virtual Network**.
1. List your **Virtual Networks**, their **Resource groups**, and **Regions**.
{% tabs %}
{% tab title="Command" %}
```shell
az network vnet list --query "[].{Name:name, Region:location, ResourceGroup:resourceGroup, AddressSpace:addressSpace.addressPrefixes[0], ProvisioningState:provisioningState, SubscriptionId:id}" --output table
```
{% endtab %}
{% endtabs %}
2. Set some environment variables for the **Resource Group**, **Region** and **Virtual Network** you want to send flow from to make cutting and pasting the commands from the instructions in this document a little easier.
```
REGION= # Region of your Virtual Network, example: REGION=eastus
VNET= # The Virtual Network name, example: VNET=ProductionA1
RGRP= # The Resource Group of your Virtual Network, example: RGRP=PROD
```
3\. Create a **Storage account** in the same **Region** as your **Virtual Network** you want to add to Netography Fusion.
{% tabs %}
{% tab title="Command" %}
```shell
az storage account create \
--name \
--resource-group $RGRP \
--location $REGION> \
--sku Standard_LRS \
--kind StorageV2 \
--allow-shared-key-access true
```
{% endtab %}
{% endtabs %}
| | |
| ----------------------- | --------------------------------------------------------------------------------- |
| Name | Choose any name for your storage account |
| Resource group | Your Virtual Network Resource Group |
| Location | Your Virtual Network Region |
| Sku | Redundancy is set to locally redundant storage, Standard\_LRS |
| Kind | Standard general purpose, StorageV2 |
| Allow-shared-key-access | Create an access key that allows Netography Fusion to create your flow logs, True |
4. View your newly created Storage account.
```
az storage account list --query "[].{Name:name, ResourceGroup:resourceGroup}" --output table
```
# Create a flow log
Access Azure Cloud Shell to run CLI commands from your web browser using az. Create a Flow Log to be read by Vectra Fusion. az network watcher flow-log create \\\ --location \\$REGION\> \\\ --name \<
Access [Azure Cloud Shell](https://portal.azure.com/#cloudshell/) to run CLI commands from your web browser using az.
1. Create a **Flow Log** to be read by Vectra Fusion.
```
az network watcher flow-log create \
--location $REGION> \
--name \
--vnet $VNET \
--resource-group $RGRP \
--storage-account \
--enabled true \
--retention 1 \
--traffic-analytics false \
```

| | |
| ----------------- | ----------------------------------------------------------------- |
| Name | Choose any name for your flow log |
| Resource group | Your Virtual Network Resource Group |
| VNet | Virtual Network Name |
| Location | Your Virtual Network Region |
| Storage Account | Storage account name you created in the previous step |
| Enabled | True |
| Retention | Days of storage retention. Only 1 day is needed by Vectra Fusion. |
| Traffic Analytics | False. **Vectra Fusion does not use Traffic Analytics.** |
2. View your newly created **Flow Log**
You can scroll through your output using the left and right arrow keys, similar to using the horizontal scroll bar on a web browser.
```
az network watcher flow-log list --location $REGION --output table | less -S
```
# Add Azure VNet as a new flow source in Vectra Fusion
In Vectra Fusion navigate to Settings -\> Traffic Sources -\> Add Traffic Source Select Azure VNet Fill out the Azure traffic source flow form: Name: This will be the Name of your configuration in
1. In Vectra Fusion navigate to **Settings** -> **Traffic Sources** -> **Add Traffic Source**

2. Select **Azure VNet**

3. Fill out the Azure traffic source flow form:
**Name:** This will be the **Name** of your configuration in Vectra Fusion. You can use anything you like here.
**Polling:** Leave set as default which is enabled.
**Down Sample:** Leave as default unless you know how to use this feature.
**Virtual Network Region:** Enter the **Region** of your **Virtual Network** being added to Vectra Fusion.
**Container Name:** Leave as default of **`insights-logs-flowlogflowevent`**.
**Subscription ID**: Enter the **Subscription ID** you used for configuration.
**Network Watcher Resource Group:** Leave as default of **`NETWORKWATCHERRG`**.
\*\*Network Watcher Name:\*\*Will be **NetworkWatcher\_** followed by the name of your region.
Example: `NETWORKWATCHER_EASTUS`
**Flow Log Name**: Enter the flow log name you created in a previous step.
**Storage account name:** Enter the Storage account name you created in step #3.
**Access Key**:
Reveal your **Storage Account Access Key** with the following command:
```
az storage account keys list --account-name --resource-group $RGRP --query "[].{KeyName:keyName, Value:value}" --output table
```
# Add Context Integration to Fusion
Access Azure Cloud Shell to run CLI commands from your web browser using az. Create a new App Registration with 'accounts in this organizational directory only' preselected. You can use any Display Na
Access [Azure Cloud Shell](https://portal.azure.com/#cloudshell/) to run CLI commands from your web browser using az.
1. Create a new **App Registration** with 'accounts in this organizational directory only' preselected.
You can use any **Display Name** you want. For this example, we'll use netography-context.
{% tabs %}
{% tab title="Command" %}
```shell
az ad app create --display-name netography-context --sign-in-audience AzureADMyOrg
```
{% endtab %}
{% endtabs %}
2. Print the Application (Client) ID and save it, this is needed for the following steps.
{% tabs %}
{% tab title="Command" %}
```shell
az ad app list --display-name netography-context --query "[].{appId:appId}" --output tsv
```
{% endtab %}
{% endtabs %}
{% hint style="info" %}
**📘Save the password provided by the output from the following command**
You will only be shown this *one time* and can never retrive this again, including from the Azure Portal UI.\
This password is the **Client Secret Value** needed by Vectra Fusion.
{% endhint %}
3. Create a **Client Secret** and set the expiration date consistent with your company policies; for this example, we'll choose 24 months, which is the maximum.
{% tabs %}
{% tab title="Command" %}
```shell
az ad app credential reset --id --append --end-date "2026-10-23"
```
{% endtab %}
{% endtabs %}
Your output should look similar to the following, make sure you **save the password**:
> The output includes credentials that you must protect. Be sure that you do not include these credentials in your code or check the credentials into your source control. For more information, see
>
> {\
> "appId": "XXXXX-XXXX-XXXX-XXXX-XXXXXXXXX",\
> "password": "XXXX~~XXXXXXXXXXXX.dIc~~XXXXXXXXX",\
> "tenant": "XXXXXX-XXXX-XXXX-XXXX-XXXXXXXXXX"\
> }
4. Retrieve the **Object ID** of your **App Registration**, which is needed to create a **Service Principal** in the next step.
{% tabs %}
{% tab title="Command" %}
```shell
az ad app show --id --query "id"
```
{% endtab %}
{% endtabs %}
5. Create a **Service Principal** for your **App Registration**, this is required for the the next step.
{% tabs %}
{% tab title="Command" %}
```shell
az ad sp create --id
```
{% endtab %}
{% endtabs %}
6. Retrieve the **Object ID** of your **Service Principal**, this is required for the **Role Assignment** step.
{% tabs %}
{% tab title="Command" %}
```shell
az ad sp show --id --query "id"
```
{% endtab %}
{% endtabs %}
7. Retrieve the **Subscription ID** we're working in, this is required for the **Role Assignment** step.
{% tabs %}
{% tab title="Command" %}
```shell
az account show --query id --output tsv
```
{% endtab %}
{% endtabs %}
8. Select the **Role Assignment** for your **App Registration**.
```
az role assignment create --assignee-object-id --role "Reader" --scope /subscriptions/
```
## Add context integration to Vectra Fusion
1. Navigate to **Settings** -> **Context Integrations** -> **Add Integration**

2. Select **Microsoft Azure**

3. Fill out the Azure Context Integration form:
**Name**: Use any name here.
**Update Interval**: Leave as default.
**Auto Update**: Leave enabled.
**Subscription ID**: The Subscription ID you used to complete the instructions in this document.
Run the following command to retrieve this information:
{% tabs %}
{% tab title="Command" %}
```shell
az account show --query id --output tsv
```
{% endtab %}
{% endtabs %}
**Tenant ID**: Your Azure Tenant ID.
Run the following command to retrieve this information:
{% tabs %}
{% tab title="Command" %}
```shell
az account show --query tenantId --output tsv
```
{% endtab %}
{% endtabs %}
**Tag/Label Matches**: Leave as default unless you know how to use this feature.
**Application Client ID**: Enter the "Applicant (Client) ID"
Run the following command to retrieve this information:
{% tabs %}
{% tab title="Command" %}
```shell
az ad app list --display-name netography-context --query "[].{appId:appId}" --output tsv
```
{% endtab %}
{% endtabs %}
**Client Secret Value**: This is the password you saved from **Step 3** in this document.
4. Click **Create and Run**
# GCP Cloud Onboarding
{% hint style="info" %}
New to Fusion cloud onboarding? Start with [Fusion Onboarding for Cloud Engineers](/cloud-onboarding/fusion-onboarding-for-cloud-engineers) for deployment models, scope planning, and cloud-specific guidance.
{% endhint %}
Use one of these three paths to configure GCP VPC flow logs, Cloud DNS logs, cloud context, and onboarding to Fusion.
Choose the path that fits your environment:
* **Manual onboarding** — best for a small number of projects or an initial PoC
* **Vectra onboarding automation** — best for large or dynamic GCP environments
* **Custom IaC automation** — best if you prefer integrating to your existing IaC
### 1. Manual onboarding
Follow step-by-step guides to configure GCP and Fusion, onboard each project, and add cloud context.
**Best for**
Organizations with a small number of projects that rarely change, or for an initial PoC.
**Next steps**
* [GCP VPC Flow Logs via Pub/Sub Setup](/ingest-network-traffic-logs/flow-logs/gcp-flow-logs-via-pubsub)
* [GCP Cloud DNS Logs via Pub/Sub Setup](/ingest-network-traffic-logs/dns-logs/dns-source-gcp)
* [GCP Context Integration](/enrich-traffic-with-context/configure-context-integrations/gcp)
* [Quickstart: GCP](/cloud-onboarding/gcp-cloud-onboarding/quickstart-gcp)
### 2. Vectra Cloud Onboarding Automation for GCP Organizations
For detailed documentation, see [Vectra Terraform Cloud Onboarding for GCP Organizations](/cloud-onboarding/gcp-cloud-onboarding/neto-onboarding-gcp).
{% hint style="info" icon="robot" %}
**Using Terraform to automate onboarding**
Access Vectra's Terraform automation at .
For access to the repo, reach out to your Vectra contact with your GitHub ID or request the latest release package.
Vectra provides the `neto-onboarding` Terraform project for AWS Organizations, Azure Tenants, and GCP Organizations.
This automation can:
* Enable and configure AWS VPC flow logs, Azure VNet flow logs, and GCP VPC flow logs based on policy and tags
* Deploy the infrastructure required to integrate with Fusion across multiple accounts, subscriptions, or projects
* Add VPCs configured for flow logging to Vectra Fusion as traffic sources
* Deploy a single AWS Lambda, Azure Function, or Google Cloud Function for context enrichment across all in-scope environments
* Monitor for VPC changes, onboard new in-scope networks, and offboard networks that leave scope
{% endhint %}
**Best for**
Organizations that want a complete, supported, end-to-end solution for managing flow log configuration and onboarding to Fusion. This is usually the fastest path for large, dynamic, or multi-cloud environments.
**Next steps**
* Reach out to your Vectra contact and request access to the GitHub repo.
* Include your GitHub ID, or request the latest release package.
### 3. Custom IaC automation
Use your existing automation pipelines or scripts to:
* Create Pub/Sub topics, subscriptions, logging sinks, and the required permissions
* Configure VPC flow logs and Cloud DNS logging policies in GCP
* Call the Fusion API to create flow and DNS traffic sources and create context integrations
**Best for**
Organizations experienced with GCP IaC that already provision VPCs, DNS logging, or related resources through automation and want to extend that workflow to Fusion.
**Next steps**
Vectra's Cloud Onboarding Automation for GCP Organizations, described in option 2, provides example code using Terraform, Google Cloud Functions, and Python for the full onboarding flow. Review that implementation and reach out to Vectra if you need help building custom IaC.
In addition, Fusion traffic source creation and context integration options are documented in [AWS Custom IAC Onboarding for Cloud Automation Engineers](/cloud-onboarding/aws-cloud-onboarding/aws-configuration-automation-for-multiple-vpcs#automating-fusion-traffic-source-creation). These methods apply across clouds.
# Vectra Terraform Cloud Onboarding for GCP Organizations
## Overview
The automation performs these functions for onboarding GCP to Vectra Fusion:
1. Deploy all the infrastructure required to integrate to Fusion to ingest VPC flow logs and/or Cloud DNS logs across multiple projects and folders in a GCP organization.
2. Enumerate GCP resources with IP addresses and meta-data associated with those resources and send to Vectra Fusion for context enrichmnet.
3. Monitor for VPC subnet changes and new projects, and trigger onboarding to Fusion new VPC flow logs and/or Cloud DNS logs that are in-scope.
It can also orchestrate VPC flow log and Cloud DNS log configurations, including:
4. Enable and configure VPC flow logging and Cloud DNS logging based on a policy you define at the organization, folder, or project level, with VPC and subnet subpolicy overrides.
You can choose to use this automation for only the Fusion onboarding of existing enabled logs, or for both the onboarding to Fusion and orchestration of flow and/or Cloud DNS logging across your whole organization, or in specific folders or projects, with VPC and subnet subpolicy overrides where needed.
## Architecture Diagrams
*Onboarding Automation Architecture Diagram Notes*
* The Cloud Functions have been consolidated into a single function (context function and its associated resources no longer exists separately)
* Cloud DNS, if enabled, has its own logging sink, pub/sub topic, subscription, and Fusion traffic source
## Deployment Components
This involves these main components:
### Terraform deployment
* `terraform/deployments/neto-onboard-gcp-full/` - Terraform to deploy resources for full deployment
Terraform will deploy the following resources to the project configured in the google provider:
* **Vectra Log Activator Cloud Function** - Orchestration function (see details in next section).
This is deployed with the following resources:
* Cloud Function
* Storage Bucket for function source code
* Service Account for the Cloud Function
* IAM roles and permissions for the Cloud Function Service Account
* Time sleep resource to handle dependencies and delays
* **Organization Cloud Assset Feed** - Triggers Cloud Function on change events in Projects or Folders through a message to the *Cloud Asset Pub/Sub topic*.
* Organization Asset Feed
* Service Account for asset feed
* IAM roles and permissions for the Asset Feed Service Account
* Pub/Sub topic for asset feed to trigger cloud function
* Pub/Sub topic IAM binding for the service account
* **Flow Logs Pub/Sub** - For publishing and receiving VPC flow logs
* Pub/Sub Topic for flow logs
* Pub/Sub Subscription for flow logs
* Pub/Sub IAM Members for publisher and subscriber roles
* Project IAM Binding for Pub/Sub admin role
* **Cloud DNS Logs Pub/Sub** - For publishing and receiving Cloud DNS logs
* Pub/Sub Topic for Cloud DNS logs
* Pub/Sub Subscription for Cloud DNS logs
* Pub/Sub IAM Members for publisher and subscriber roles
* Project IAM Binding for Pub/Sub admin role
* **Metrics, Monitoring, and Notification Channel** - For monitoring the Cloud Function and alerting on errors
* Logging Metric to count Cloud Function errors
* Monitoring Alert Policy to define alert conditions and strategies
* Monitoring Notification Channel to send email notifications
* **Secret Manager resources** - For storing and retrieving Vectra Fusion API key secret
* Secret Manager Secrets for Vectra API secret (`netosecret`)
* Secret Manager Secret Versions to store the actual secret value
* Secret Manager IAM Members to grant access to the secret for the Cloud Function service account
### Cloud Function
#### `neto-logactivator` (GCP Cloud Run function `neto-acme-prod-logactivator`)
Triggers:
* Schedule (if `timer_enable=true`, based on schedule set in `timer_schedule`)
* Event triggers when changes occur to a project or folder
* Manually triggered by sending a message to the Pub/Sub topic (`scripts/run` will do this from command line)
1. Evaluate policy scope
* Identifies all the in-scope projects in the organization based on the scope policy you define. More details on defining scope is in the Scope Policy section below.
2. Create Vectra Fusion traffic source(s) if they do not exist
* If Flow log ingest is enabled (`ingest_flow=true`), creates a traffic source for the Pub/Sub topic subscription for all VPC flow logs.
* If Cloud DNS ingest is enabled (`ingest_dns=true`), creates a second traffic source for the Pub/Sub topic subscription for all Cloud DNS logs.
* Writes the label `neto_traffic_source` with value of your Fusion shortname to the orchestration project to indicate traffic sources have been created.
3. Onboard in-scope projects:
* Creates a Cloud Logging Sink that routes flow logs to the Pub/Sub topic Vectra subscribes to, and a Cloud Logging Sink for Cloud DNS if enabled
* Grants writer identity for the sink the `roles/pubsub.publisher` role to the Pub/Sub topic(s)
* Writes the label `neto_account` with value of your Fusion shortname to the project to indicate it has been onboarded
4. Orchestrate logging in in-scope projects:
* Enables flow logging for all the subnetworks in the project (if flow log orchestration is enabled)
* Creates a Cloud DNS policy with DNS logging enabled for all the VPC in the project (if Cloud DNS orchestration is enabled, and no Cloud DNS policy already exists for the VPC)
5. Offboards out of scope projects previously onboarded
* Identifies all projects out of scope with the `neto_account` label to offboard.
* Removes the role bindings for the service account to the logging sink(s).
* Deletes the logging sink(s).
* Disables flow logs for subnets in the project (if `orchestrate_flow_logs=true`).
* Disables Cloud DNS logging for VPC in the project (if `orchestrate_dns_logs=true`).
* Removes the `neto_account` label to indicate its no longer onboarded.
6. Context enrichment
* Enumerates all the compute Instances in in-scope projects, iterate through the interfaces, and add Vectra Fusion labels for these fields linked to the `networkIP` of each IP, skipping loopback, reserved, and multicast addresses:
If run with the `trigger_type` attribute set to `destroy`, the function will perform the offboarding of all projects, and then remove the Fusion traffic sources.
## Prerequisites
To simplify checking and configuring prerequisites, a set of scripts are provided in the `scripts/` directory that wrap the `gcloud` CLI.
See `scripts/README.md` for more details on the scripts and how to configure `gcloud` with the proper authentication (if you are not a `gcloud` expert and have these already setup).
{% stepper %}
{% step %}
### 1. Designate a project to deploy resources into
It is recommended you create a new GCP project for Terraform to deploy resources to, but you can reuse an existing project if you prefer. This project is referred to as the `orchestration project`.
The project needs the following APIs enabled:
| API Name | Endpoint |
| ---------------------------------------- | ------------------------------------- |
| Cloud Asset API | `cloudasset.googleapis.com` |
| Cloud Build API | `cloudbuild.googleapis.com` |
| Cloud DNS API | `dns.googleapis.com` |
| Cloud Functions API | `cloudfunctions.googleapis.com` |
| Cloud Monitoring API | `monitoring.googleapis.com` |
| Cloud Pub/Sub API | `pubsub.googleapis.com` |
| Cloud Resource Manager | `cloudresourcemanager.googleapis.com` |
| Cloud Run Admin API | `run.googleapis.com` |
| Cloud Scheduler API | `cloudscheduler.googleapis.com` |
| Eventarc API | `eventarc.googleapis.com` |
| Identity and Access Management (IAM) API | `iam.googleapis.com` |
| Network Management API | `networkmanagement.googleapis.com` |
| Organization Policy API | `orgpolicy.googleapis.com` |
| Secret Manager API | `secretmanager.googleapis.com` |
| Service Usage API | `serviceusage.googleapis.com` |
`scripts/prereq-apis plan ` will check if the required APIs are enabled, and if not provide you the command to run to enable them in the project.
This is the command to enable all required APIs (ensure you have set your current project to the orchestration project or specify `--project=orchestration-project-id`):
```sh
gcloud services enable \
cloudasset.googleapis.com cloudbuild.googleapis.com cloudfunctions.googleapis.com \
cloudresourcemanager.googleapis.com cloudscheduler.googleapis.com dns.googleapis.com \
eventarc.googleapis.com iam.googleapis.com logging.googleapis.com \
monitoring.googleapis.com networkmanagement.googleapis.com orgpolicy.googleapis.com \
pubsub.googleapis.com run.googleapis.com secretmanager.googleapis.com
```
**Note:** After enabling the Cloud Asset API, you must make at least one API call to trigger the automatic creation of the Cloud Asset service account. This service account is required for the organization asset feed to function properly. Run this command to initialize it:
```sh
gcloud asset search-all-resources --scope=projects/ --asset-types=compute.googleapis.com/Instance --limit=1
```
Wait 30-60 seconds after this command completes for the service account to propagate before running Terraform.
{% endstep %}
{% step %}
### 2. If you have GCP Organizational Policy Constraints
*Updating an organization policy requires the Organization Policy Administrator role (`roles/orgpolicy.policyAdmin`).*
If you have GCP organization policy constraints in place, you may be unable to deploy resources or execute actions, even if you have the appropriate permissions. If you receieve errors during the deployment or in the Cloud Function log indicating an organization policy is enforced, you will need to add or edit a rule for that policy to allow the action to take place.
See:
{% endstep %}
{% step %}
### 3. If you have a Domain Restricted Sharing Organizational Policy Constraint
*Even if you have not set up any organization policy constraints, there may still be this default constraint in place.*
The *Domain Restricted Sharing* policy (`constraints/iam.allowedPolicyMemberDomains`) prevents you from granting a permission to a member on an external domain. Vectra's service account `sa-cloud@netography.iam.gserviceaccount.com` resides outside your domain, requiring a policy update to allow Vectra to subscribe to the Pub/Sub subscription where flow logs are published.
**This constraint is the default setting for all GCP organizations created on or after May 3, 2024.**
**Vectra account details**
| Field | Value |
| ------------------- | ----------------------------------------------- |
| Service Account | `` |
| Customer ID | `C04ddcbu8` |
| Permission Required | Pub/Sub Subscriber (`roles/pubsub.publisher`) |
If this policy restriction exists and you do not add a rule for this account, you will receive the following error when the automation attempts to grant this permission:
**IAM policy update failed - The ‘Domain Restricted Sharing’ organization policy (constraints/iam.allowedPolicyMemberDomains) is enforced.**
`scripts/prereq-domainrestricted plan` will check if the domain restricted sharing policy is in place and if it allows the Vectra customer ID.\
`scripts/prereq-domainrestricted apply` will add a rule to allow the Vectra customer ID to this policy.
*`scripts/prereq-domainrestricted` requires the `orgpolicy.googleapis.com` API in your orchestration project is enabled (you should have done this in the first pre-req step).*
{% endstep %}
{% step %}
### 4. Create a service account for the Terraform provider
It is recommended to create a service account in the project configured for the Terraform provider.
#### Terraform provider service account least privilege Organizational Level Roles
| Role Name | Role | Description |
| -------------------------- | ----------------------------------------- | --------------------------------------- |
| Cloud Asset Owner | `roles/cloudasset.owner` | Full control over Cloud Asset resources |
| DNS Admin | `roles/dns.admin` | Full control over DNS resources |
| Logging Admin | `roles/logging.admin` | Full control over logging resources |
| Organization Administrator | `roles/resourcemanager.organizationAdmin` | Full control over Org-level resources |
| Org Role Administrator | `roles/iam.organizationRoleAdmin` | Create the custom roles in org |
#### Terraform provider service account least privilege Project Level Roles
| Role Name | Role | Description |
| ---------------------- | ----------------------------------------- | ------------------------------------------- |
| Owner | `roles/owner` | Privileged access to project |
| Cloud Functions Admin | `roles/cloudfunctions.admin` | Full control over Cloud Functions resources |
| Cloud Scheduler Admin | `roles/cloudscheduler.admin` | Full control over Cloud Scheduler resources |
| Logging Admin | `roles/logging.admin` | Full control over logging resources |
| Monitoring Admin | `roles/monitoring.admin` | Full control over monitoring resources |
| Project IAM Admin | `roles/resourcemanager.projectIamAdmin` | Full control over project IAM resources |
| Pub/Sub Admin | `roles/pubsub.admin` | Full control over Pub/Sub resources |
| Secret Manager Admin | `roles/secretmanager.admin` | Full control over Secret Manager resources |
| Service Account Admin | `roles/iam.serviceAccountAdmin` | Full control over service accounts |
| Service Usage Consumer | `roles/serviceusage.serviceUsageConsumer` | Ability to use services in the project |
| Storage Admin | `roles/storage.admin` | Full control over storage resources |
`scripts/prereq-terraform-sa plan` - review planned actions to create the service account and assign roles\
`scripts/prereq-terraform-sa apply` - create the service account and assign roles\
`scripts/prereq-terraform-sa verify` - check if the service account exists and has the required roles\
`scripts/prereq-terraform-sa keygen` - create a service account key and save it to a local file
You can also use `scripts/prereq-terraform-sa apply-token ` to grant a user permission to impersonate the service account if you will be using service account impersonation.
{% endstep %}
{% step %}
### 5. Create a default Cloud Asset Inventory Service Account in the Orchestration project
The default Cloud Asset Inventory Service Account must exist in the orchestration project or you will receive an error that looks like this when applying the Terraform:
```
Error applying IAM policy for pubsub topic "projects/neto-mycorp-dev-orch/topics/neto-mycorp-dev-asset-feed-topic": Error setting IAM policy for pubsub topic "projects/neto-mycorp-dev-orch/topics/neto-mycorp-dev-asset-feed-topic": googleapi: Error 400: Service account service-555555555@gcp-sa-cloudasset.iam.gserviceaccount.com does not exist.
```
`scripts/prereq-cloudasset create ` - create the service account in the project
You can also create the service account manually with the following command:
```sh
PROJECT=yourprojectid
gcloud beta services identity create --service=cloudasset.googleapis.com --project=$PROJECT
```
{% endstep %}
{% step %}
### 6. Vectra Fusion API key (`netosecret`)
You will need to create a Vectra Fusion API key. See: [API Keys](/settings/user-management/index)
This secret is stored in Google Secret Manager in the orchestration project as the `netosecret` secret. You will add it as part of the deployment steps below.
You should not store this value in your `tfvars` file directly.
Store and export it in your environment for using later in the deployment:
```sh
export NETOSECRET=your-api-key
```
On a Mac, you can copy it from your clipboard directly by running:
```sh
export NETOSECRET=$(pbpaste)
```
{% endstep %}
{% step %}
### 7. Vectra Fusion CLI tool (Optional)
It is helpful to use the neto CLI tool as part of deploying to validate its operation. This package is in the repo `/neto/` directory.
See \`../neto/README.md for more details
To install this into a Python virtual environment (recommended - this will ensure you don't have any conflicts, and allows you to run `neto` wheneveer you have activated this environment):\
From the root of repo directory `neto-onboarding/`, run:
```sh
python3 -m venv venv
source venv/bin/activate
cd neto
pip install .
neto --version
neto -h
```
To exit the virtual environment, run `deactivate`.\
To enter the virtual environment again, from repo root `neto-onboarding` run `source venv/bin/activate`.
{% endstep %}
{% step %}
### 8. Terraform 1.11 or newer and Basic terraform knowledge
Terraform 1.11 or newer is required to deploy the automation.
This automation has been built for engineers with basic familiarity using terraform.
{% endstep %}
{% endstepper %}
## GCP Regions
The orchestration functions in all regions available in your GCP organization. Unlike AWS and Azure, there is no per region handling for purposes of flow log orchestration.
## Scope Policy
The scope policy determines whether a project is in-scope for orchestration. See the [Log Activator Function](#terraformfunctionsneto-logactivator) for details of the actions taken for in-scope projects.
The scope policy is defined in JSON, containing a list of rules.
A rule has these values:
Each rule has a **type** (organization, folder, project), **action** (include or exclude), **members** (list of IDs or numbers), and an optional **subpolicy** section for VPC and subnet rules, and a **config** section for configuration parameters.
*The policy will ignore keys that are not applicable to it in rules outside of config, so adding comments to help you document your policy in unused keys such as `comment` can be helpful.*
```json
{
"comment": "Sample GCP scope policy.",
"tip": "Run 'neto policy validate --file scope-policy.json' to validate the policy after changing it.",
"policy": [
{
"comment": "Rule to include everything in the organization. This is the only rule needed for a simple deployment.",
"format-help": "Use the number of the organization (eg 514213275881)",
"type": "organization",
"action": "include",
"members": [
"514213275881"
],
"config": {
"flowSampling": 1.0
}
},
{
"comment": "Rule to include all projects that are descendants of the folder(s) in members list",
"format-help": "Use the number of the folder (eg 739546312018)",
"type": "folder",
"action": "include",
"members": [
"739546312018"
],
"config": {
"flowSampling": 0.9
}
},
{
"comment": "Rule to include specific projects. Any config set here will override a folder or organization rule.",
"format-help": "Use the ID of the project (eg my-project-id), not number or name.",
"type": "project",
"action": "include",
"members": [
"project-to-include-id",
"project-to-include-id-2"
],
"config": {
"flowSampling": 1.0
},
"subpolicy": [
{
"comment": "Subpolicy rules apply to vpc or subnets within any project matching its parent rule.",
"type": "subnet",
"members": [
"subnet-name-to-config-for-specific-regions"
],
"comment-region": "If region is specified, the config will only apply to subnets in those regions.",
"region": [
"africa-south1",
"asia-east1",
"asia-east2"
],
"config": {
"flowSampling": 0.5
}
},
{
"comment": "This will apply to all subnets in regions not matching previous subpolicy rule. Disables Cloud DNS logs for matching subnets",
"type": "subnet",
"members": [
"subnet-name-to-config-for-all-regions"
],
"config": {
"flowSampling": 0.4,
"dns": "disable"
}
},
{
"comment": "Excludes any vpc that match this subpolicy rule by having enable: false in config.",
"format-help": "Use the vpc name.",
"type": "vpc",
"members": [
"vpc-name-to-exclude"
],
"config": {
"enable": false
}
}
]
}
]
}
```
Policy rules are always inherited, with the most closely scoped rule to the project having precedence (eg project rules take precedence over folder rules which take precedence over organization rules). Within the same type (eg multiple project rules or folder rules), the first rule that matches in the order they are listed in the JSON will be used.
### Valid `members` values
* `project`: `projectId` (`my-project`). The human-readable `name` can not be used, as it is not a unique identifier.
* `folder`: The numeric folder identifier (`name` omitting the leading `folders/` string). The human-readable folder `displayName` can not be used, as it is not a unique identifier.
* `organization`: The numeric organization identifier (`name` omitting the leading `organizations/` string). The human-readable organization `displayName` can not be used, as it is not a unique identifier.
**Note: In GCP, the `name` field is the human-readable string for a `project`, but the unique identifier for a `folder` or `organization`.**
### Policy config
You can modify flow log settings for each policy rule by adding a **config** section to the rule. If a config section is present, any values set take precedence over values set in tfvars. A config section in an `"action":"exclude"` rule will apply those settings when offboarding a project due to it no longer being in scope (if the project was never onboarded, the settings will never be used).
Within a config section, the supported keys are:
* `ignore` - If set to true, no flow log configuration will be modified. Use where another system is orchestrating flow log configurations to avoid conflicts.
* `enable` - If set to false, flow logs will be disabled for the matching entities.
* `disable` - If set to false, flow logs will NOT be disabled when offboarding the entity.
* `aggregationInterval`, `flowSampling`, `metadata`, `filterExpr` - Keys passed in the `logConfig` to GCP
* `sink_filter_flow`, `sink_filter_dns` - Cloud Logging Sink filter expression to use
* `dns` - Valid values are `enable`, `disable`, or `ignore`. This config setting is used if `orchestrate_dns` is set to `true` in tfvars to enable Cloud DNS logging orchestration. If set to `enable`, Cloud DNS logging will be enabled when onboarding the member. If set to `disable`, Cloud DNS logging will be disabled for the member. If set to `ignore`, Cloud DNS logging will not be modified by the orchestration. The `dns` config setting can be applied to an organization, folder, or project rule, and to a `vpc` or `subnet` subpolicy rule.
* `scope-policy.json.example` provides an example of the full policy template filled out.
* `scope-policy.json.template-full` provides a template for a more complex policy.
* `scope-policy.json.template-simple` provides a template for a simple policy.
Copy one to `scopy-policy.json` and edit.
## Deploying the automation
{% stepper %}
{% step %}
### 1. Apply the Terraform Project
* Clone the git repo
* Check all the pre-requisite steps above
* This terraform project is targeted towards a designated orchestration project in your GCP organiation
* From the root directory of this repository: `cd gcp/terraform/deployments/`
* Change the `backend.tf` file to the backend your organization uses
* Update the `providers.tf` with the project you are targeting and your preferred google provider authentication method.
* Copy `terraform.tfvars.template` to `terraform.tfvars` and define the appropriate variables.
* Copy `scope-policy.json.template-simple` to `scope-policy.json` and add a project to the scope (see Scope Policy config section above)
* Run `terraform init`
* Run `terraform apply` and accept the changes
The input variables and resources created are described in `terraform/deployments/README.md`
After completing the `terraform apply`, verify all the resources were deployed successfully.
{% endstep %}
{% step %}
### 2. Add Vectra API secret to Google Secret Manager
The Vectra API key `netosecret` is read from Google Secrets Manager in the project set in the Terraform provider, using the following secret id:
* `netosecret`
The values are set to `REPLACE_ME` by the Terraform deployment if the secret does not exist.
If this secret is stored in the `$NETOSECRET` environment variable (eg displayed when you `echo $NETOSECRET`), you can add it to Google Secret Manager by running:
```sh
printf $NETOSECRET |gcloud secrets versions add netosecret --data-file=-
```
If you prefer using the GCP Console, select the orchestration project, go to Secret Manager, and create a new version of the secret `netosecret` (check disable previous secrets):\
**If you prefer to keep the API key in Terraform**
If you prefer to keep the API key in Terraform (although this is not as secure an approach as writing it directly to Secret Manager, you may have your own workflow for managing secrets):
1. Set and export it to the `TF_VAR_netosecret` environment variable before running `terraform apply`, or run `terraform apply -var netosecret=$NETOSECRET`
2. Edit `main-secrets.tf` and remove this block from `resource "google_secret_manager_secret_version" "netosecret"`
```
lifecycle {
ignore_changes = all
}
```
Even if you use this approach, do not directly write the secret to the `tfvars` file or pass the secret directly on the command line as a string as these are not secure methods of storing and passing secrets.
*(This change will have Terraform apply the secret to Google Secret Manager any time you change it. Without removing the `ignore_changes` block, which is there to prevent Terraform from overwriting the value you manually set in Secret Manager in the recommended approach, Terraform will not keep the `netosecret` in tfvars in sync with the version in Secret Manager.)*
{% endstep %}
{% step %}
### 3. Trigger the Cloud Function to Run to Perform the Initial Onboarding
The Terraform deploys resources, but the Cloud Functions do most of the work. Cloud Functions will not execute until you manually trigger it or it runs on a schedule.
If you have a GCP organization that has less than 50 in-scope projects, simply run `scripts/run all` to run the complete function and it will handle all the steps of onboarding at once.
If you have a larger organization, or one with thousands of VPC subnets, you should onboard in steps. This is because the Google Function has a time limit of 9 minutes for each execution, and enabling all the components of the automation can extend beyond that time for the initial onboarding. The function is designed to pick up where it left off and resume onboarding if it times out, so it is expected and normal practice to have to trigger it multiple times during the first time onboarding of a large organization.
To onboard in steps, you have three options:
1. Expand the number of folders and projects in-scope through the scope policy, onboarding them in groups, and once they have completed onboarding and enabling, add the next set. This is a good general cloudops practice for ensuring that deployments that are across an organization can be validated in phases.
2. Trigger the function when first onboarding a new set of projects with `scripts/run -1`, `scripts/run -2`, `scripts-run -3`. This divides onboarding into enabling APIs (step 1), creating log sinks (step 2), and enabling flow logs (step 3).
3. If the function runs for 9 minutes before completing, it will stop at that point. To continue onboarding, simply trigger it again. It will verify the state of what it has already completed first, but these are fast operations, and then it will reach the point where it needs to continue to create/enable resources and it will pick up there.
```sh
Usage: ../../scripts/run [options] [topic-name]
Triggers the Google Function to run
Commands:
all Full function run (onboarding, orchestration, context enrichment, and offboarding)
onboard (or 1) Onboarding: Enable APIs, logging sinks, add neto_account label to project
orchestrate (or 2) Flow log orchestration in previously onboarded projects only (will not onboard new projects in-scope)
context (or 3) Context enrichment in previously onboarded projects only (will not onboard new projects in-scope)
offboard (or 4) Offboarding of out of scope projects (disable flow logs, remove log sinks, remove neto_account label; APIs remain enabled)
destroy Destroy all resources created by function (complete offboarding before a terraform destroy)
Options:
-i, --index N Index to start orchestration from (default: 1, first project in list); only applies to orchestration
-c, --concurrency Custom concurrency settings for execution in format "N,N,N" (gcp_concurrent_limit,gcp_connection_limit,gcp_thread_limit
--skip-dns Set ORCHESTRATE_DNS_LOGS=false to skip dns orchestration
-u, --update-sinks Update log sink filters for all onboarded projects (default: only set logging sink filters when onboarding)
-h, --help Show this help message
```
**Trigger the Cloud Function with a Pub/Sub message**
You can also trigger the Log Activator Cloud Function to run by sending a message to the asset feed Pub/Sub topic created by the Terraform with an attribute `trigger_type` and value `manual`. The Pub/Sub topic name is constructed as `---asset-feed-topic`. Review `scripts/run` to see how to construct the proper message.
#### Triggering the function in the GCP Console
You can also trigger the Log Activator Cloud Function to run in the GCP Console. Go to Pub/Sub > Topics, Select the asset feed topic in the orchestration project, then select the Messages tab, click Publish Message, click Add an Attribute, and enter key `trigger_type` and value `manual`. Review `scripts/run` to see how to construct additional attributes for the message.
{% endstep %}
{% step %}
### 4. Onboarding of New Projects and Subnetworks
Once the initial onboarding is complete:
1. Vectra Fusion will have 1 traffic source for the GCP Pub/Sub subscription in the project for flow logging, using one traffic source for all VPCs across all projects.
2. Vectra Fusion will have 1 traffic source for the GCP Pub/Sub subscription in the project for DNS logging, using one traffic source for all DNS logs across all projects.
3. Each in-scope project will have 2 new Cloud Logging Sinks, one for flow logs and one for DNS logs, that route logs to the Pub/Sub topic Vectra is subscribed to.
4. VPC flow logs will be enabled in all VPC subnetworks in the project (or however you configured the scope policy).
5. Cloud DNS logging policy will exist with all the VPCs enabled for logging in each project (if you enabled Cloud DNS logging in tfvars).
6. Context enrichment will have run in all in-scope projects, adding context labels to Fusion for addressable resources used by instances in the project.
Changes to in-scope projects, VPC, and subnetworks will be picked up, and any projects that have changed scope will be onboarded or offboarded, and any VPC and subnetworks that have changed or are new will be orchestartead during the next scheduled run of the cloud function.
If you want to change the scope, edit the scope policy (and/or edit the `terraform.tfvars` file to adjust any config settings), run `terraform apply` to deploy the changes, and trigger the cloud function again.
{% endstep %}
{% step %}
### 5. Scheduling the Cloud Function
Scheduling the `neto-logactivator` Cloud Function will ensure any changes in project scope, or new projects or subnets that may not have triggered or been successfully onboarded, will be identified and onboarded at the next scheduled execution.\
Enable Google Cloud Scheduler to trigger the function by setting the variables in the `terraform.tfvars` file:
```
timer_enable = true
timer_schedule = "0 0 * * *" # every hour
```
{% endstep %}
{% step %}
### 6. Disable debug logging
Once the orchestration has fully run and is operating properly, you can disable debug logging (which is enabled by default to help assist in any troubleshooting during initial onboarding) by setting `debug_mode = false` in the `terraform.tfvars` file.
{% endstep %}
{% endstepper %}
### Offboarding a project
A project can be removed from scope in one of two ways:
1. Remove the project(s) from being in scope in the scope policy, by editing the policy and `terraform apply`
2. Move a project from an in-scope folder to an out of scope folder.
Trigger the *Log Activator* function to have the scope change take effect.
This will restore the project to its pre-orchestration state, **EXCEPT**:
1. If flow logs were enabled before the project was added to the scope, they will now be disabled after removing the project from the orchestration scope.
2. APIs enabled during onboarding are not disabled when offboarding.
If you do not want to disable flow logging when offboarding all projects, set `disable_flow_logs=false` in tfvars. If you not want to disable flow logging when offboarding a specific project, you can exclude that project from scope in the scope policy with a rule that has `"action": "exclude"` and a config section with the `"ignore": true` setting.
## Additional Configuration Options
### `context_list_scope`
Context enrichment gathers asset metadata using GCP's Cloud Asset Inventory. The `context_list_scope` variable determines how the Cloud Asset Inventory is called.
* `context_list_scope = "project"` - For organizations with a small proportion of the total GCP organizaion in-scope. This is the default setting. This will make 1 ListAssets call for each onboarded in-scope project.
* `context_list_scope = "organization"` - If you have hundreds of projects, or most of your GCP organization is in-scope, this is a faster/more efficient setting. This will make 1 ListAssets call for the whole organization, then filter the results by onboarded in-scope projects.
## Service Accounts, Roles, and Role Bindings
### Flow Logging Pub/Sub subscription role binding
| Roles | Binding | Purposes |
| ------------------------- | ---------------------- | ------------------------------ |
| `roles/pubsub.subscriber` | Vectra service account | Allow Vectra to read flow logs |
### Org Asset Feed service account
| Roles | Binding | Purposes |
| ------------------------- | --------------------------- | --------------------------------- |
| `roles/pubsub.subscriber` | asset feed pub/sub topic | Subscribe to Org Asset Feed topic |
| `roles/run.invoker` | flow log activator function | Trigger function |
### Log Activator function service account
| Roles | Binding | Purpose |
| ------------------------------------ | ------------------------ | ---------------------------------- |
| `roles/pubsub.subscriber` | orchestration project | Read from asset feed Pub/Sub topic |
| `roles/storage.objectAdmin` | function storage bucket | Function configuration |
| `roles/artifactregistry.writer` | orchestration project | Function configuration |
| `roles/logging.logWriter` | orchestration project | Write function logs |
| `roles/secretmanager.secretAccessor` | netography-app-key | Read Fusion API key secret |
| `roles/secretmanager.secretAccessor` | netography-shared-secret | Read Fusion API key secret |
| LogActivator custom role | GCP Organization | Manage VPC flow logs |
### Context Enrichment function service account
| Roles | Binding | Purpose |
| ------------------------------------ | ------------------------ | -------------------------- |
| `roles/pubsub.subscriber` | orchestration project | Trigger on a Pub/Sub topic |
| `roles/storage.objectAdmin` | function storage bucket | Function configuration |
| `roles/artifactregistry.writer` | orchestration project | Function configuration |
| `roles/logging.logWriter` | orchestration project | Write function logs |
| `roles/secretmanager.secretAccessor` | netography-app-key | Read Fusion API key secret |
| `roles/secretmanager.secretAccessor` | netography-shared-secret | Read Fusion API key secret |
| Context Enrich custom role | GCP Organization | Read asset information |
### Cloud Asset Inventory default service account
| Roles | Binding | Purposes |
| ------------------------ | ------------------------ | ---------------------------------- |
| `roles/pubsub.publisher` | asset feed Pub/Sub topic | Publish messages to Pub/Sub topics |
### Custom Roles
The *Log Activator custom role* is bound to the *Log Activator function service account* for managing VPC flow logs across the in-scope projects in the organization
| Log Activator Custom Role Permission | Description | Purpose |
| -------------------------------------- | ------------------------- | ------------------------------------------------ |
| `resourcemanager.projects.list` | List projects | Identify in-scope projects |
| `resourcemanager.projects.get` | Get project details | Identify in-scope projects |
| `resourcemanager.projects.updatet` | Get project details | Add neto\_onboard label to onboarded projects |
| `resourcemanager.folders.get` | Get folder details | Identify in-scope projects |
| `resourcemanager.folders.list` | List folders | Identify in-scope projects |
| `cloudasset.assets.searchAllResources` | Search resources | Identify out of scope logging sinks |
| `compute.networks.list` | List networks | Identify VPC to configure Cloud DNS for |
| `compute.subnetworks.list` | List subnetworks | Identify subnets to configure flow logs for |
| `compute.subnetworks.get` | Get subnetwork | Retrieve existing flow log configurations |
| `compute.subnetworks.update` | Update subnetwork details | Enable flow logs |
| `compute.regions.list` | List regions | Enumerate subnets in a region |
| `dns.networks.bindPrivateaDNSPolicy` | Bind DNS policy to VPC | Enable Cloud DNS logging for VPC logging |
| `dns.policies.create` | Create DNS policy | Create Cloud DNS policy to enable logging |
| `dns.policies.delete` | Delete DNS policy | Delete Cloud DNS policy to disable logging |
| `dns.policies.get` | Get DNS policy details | Get current state of Cloud DNS policy |
| `dns.policies.list` | List DNS policies | Determine if Cloud DNS policy exists |
| `dns.policies.update` | Update DNS policy | Update Cloud DNS policy for logging |
| `logging.logEntries.create` | Create log entries | Write function logs |
| `logging.sinks.create` | Create logging sinks | Route flow logs to Pub/Sub topic |
| `logging.sinks.list` | List logging sinks | Determine if sink needs to be created |
| `logging.sinks.get` | Get logging sink details | Get current state of logging sink config |
| `logging.sinks.update` | Update logging sink | Update logging sink config if needed |
| `logging.sinks.delete` | Delete logging sink | Remove logging sink during offboarding a project |
| `serviceusage.quotas.get` | Get quotas | Rate limit requests to within quota |
| `serviceusage.services.enable` | Enable services | Enable logging API |
| `serviceusage.services.get` | Get service details | Determine if logging API enabled in project |
| `serviceusage.services.list` | List services | Determine if logging API enabled in project |
| `serviceusage.services.use` | Use services | Determine if logging API enabled in project |
### Context Enrichment Labels
| Context Name | GCP Field | Example |
| -------------- | ------------------ | --------------------- |
| `name` | name | myhost-vm |
| `provider` | "GCP" | GCP |
| `entity` | resource\_type | instances |
| `instancetype` | machineType | e2-micro |
| `az` | zone | us-west1-b |
| `licenses` | disks/licenses | debian-12-bookworm |
| `project` | project | neto-global-prod-orch |
| `network` | interfaces/network | neto-vpc3 |
| `subnet` | interfaces/subnet | neto-vpc3-subnet1 |
| `externalip` | interfaces/nat\_ip | 8.8.8.8 |
*Additional context labels for other GCP services are still being added to this function. Let us know if there are specific attributes and services that you'd like to see added.*
### Additional Procedures and Troubleshooting
#### Manually managing flow logs in all projects
In tfvars, set:
```bash
enable_flow_logs = false
disable_flow_logs = false
```
In this case, the orchestration will do all of the onboarding to ingest flow logs from in scope projects that you enable outside of this automation or are already enabled, but the actual configuration of flow logging in the subnets is up to you.
#### Updating logging sink filters
You can filter the logs that are sent to Vectra by modifying the `sink_filter_flow` and `sink_filter_dns` variables in `terraform.tfvars` or in the `config` section of a scope policy rule. These filter expressions are directly passed to the GCP Cloud Logging Sink inclusion filter. See for more information on how to write these expressions.
Changes to sink filters in tfvars and scope policy will only be applied when new projects are being onboarded by default. To update the filter for projects that are already onboarded, run `scripts/run --update-sinks all`. This will modify existing logging sinks to use the filter expression for each project, if it has been modified in tfvars or the scope policy.
For VPC flow logs, it is always preferable to modify the `vpc_logs_filter_expression` tfvars (`filterExpr` in the scope policy `config` section), as this will filter VPC logs before they are generated, reducing cost (filtering at the logging sink will still incur the cost to generate the log). Using `sink_filter_flow` is only needed if you are using the logs in multiple logging sinks, and want to filter the logs that are used by the logging sink that sends logs to Netography. Cloud DNS logging policies do not include a filter, so `sink_filter_dns` is the only way to filter DNS logs for a VPC.
*You can not directly set an exclusion filter for the logging sink, but inclusion filters can include `NOT` statements so anything you want to exclude you can accomplish with the inclusion filter.*
For example, if you wanted to exclude DNS queries for `.google.internal` domains for a set of projects, update the scope policy rule for those projects:
```json
{
"policy": [
{
"type": "project",
"action": "include",
"members": [
"my-project-id"
],
"config": {
"sink_filter_dns": "resource.type=\"dns_query\" AND NOT jsonPayload.queryName:\"google.internal\""
}
}
]
}
```
#### Warning: Unable to verify or enable services for project: ServiceUsage permission denied
This warning appears in the logs when the **Log Activator Function** checks if required APIs (`logging.googleapis.com`, `cloudasset.googleapis.com`, `dns.googleapis.com`) are enabled for an in-scope project. To perform these checks and enable the APIs requires the Service Usage API (`serviceusage.googleapis.com`) is already enabled in the orchestration project and monitored projects. This is enabled by default when creating a project in GCP through the GCP Console but other methods of creating projects may differ. If you receive this warning you have 2 options:
1. Enable the Service Usage API on the orchestration and in-scope project by going to the GCP Console, selecting the project, entering 'Service Usage API' in the search box, and then clicking **Enable**. You can't use gcloud services enable to do this as that also uses this API.
2. The Service Usage API is only used to check and enable the other APIs. If you have already enabled, or manually enable those 2 APIs in the in-scope project (`gcloud services enable logging cloudasset --project YOUR-PROJECT-ID`), the function will not be able to verify they are enabled but all other functionality will work as expected.
#### Cloud DNS policy and Cloud DNS logging (Error: Network cannot be bound to this policy because it is already bound to another policy.)
GCP enables Cloud DNS logging through the use of a Cloud DNS policy. The orchestration will create a new Cloud DNS policy and add the VPCs in in-scope projects to that policy if you have set `orchestrate_dns_logs = true` in tfvars.
This will NOT modify or delete an existing Cloud DNS policy you have in a project. If you already are using Cloud DNS and have existing policies in place (You can check this by running `gcloud dns policies list --project=PROJECT_ID`), it is up to you to manually enable logging in those policies (e.g. `gcloud dns policies update --enable-logging YOUR_DNS_POLICY --project=PROJECT_ID`) if it is not enabled.
The orchestration will create a Cloud DNS policy named `neto-dns-policy` (you can modify this value by setting `dns_policy_name` in tfvars) in each in-scope project, with logging enabled, and the VPC in that project bound to that policy. If you already have another Cloud DNS policy in the project that a VPC is bound to, you will receive an error:
`Network 'https://compute.googleapis.com/compute/v1/projects/your-project-id/global/networks/your-vpc-name' cannot be bound to this policy because it is already bound to another policy.`
To fix this error, you can either:
1. Disable the automation enabling Cloud DNS logging in total and only have it configured to ingest Cloud DNS logs you enable yourself by setting tfvars to `orchestrate_dns_logs = false` and `ingest_dns = true`.
2. Create a scope policy rule to ignore Cloud DNS logging for any project you have your own Cloud DNS policies in. Add a rule to match those projects, and in the config section of that rule add `"dns" : "ignore"`. See the scope policy config section above for more details.
NOte: The orchestration does not handle the case currently where you have some networks that are bound to an existing policy in a project and other networks that are not bound that you want to be orchestrated by the automation for logging. If this is a use case for your GCP environment, contact us to discuss handling this usage scenario.
# Quickstart: GCP
Getting started with GCP
### How Fusion integrates to GCP
Netography Fusion has the following integration points to GCP:
1. **Fusion ingests VPC flow logs from GCP.**
2. **Fusion ingests asset context from GCP for context enrichment.**
3. **Fusion ingests Cloud DNS resolver logs from GCP.**
### Diagram of GCP integration to Fusion
See [Diagram: GCP Integration to Fusion](/cloud-onboarding/gcp-cloud-onboarding/quickstart-gcp/diagram-gcp)
### Video Guides
See the GCP [🎥 Video Guides](/cloud-onboarding/gcp-cloud-onboarding/quickstart-gcp/video-guides)to watch videos of the setup steps.
### Steps to integrate to GCP
Each page in these instructions will walk you through the steps to integrate GCP with Netography Fusion:
* Enable VPC flow logs
* Create a Pub/Sub topic
* Create a Cloud Logging Sink Pub/Sub for the topic
* Logging sink design patterns
* Create a Pub/Sub Pull Subscription to the topic
* Give Netography's GCP service account permission to be added as a principal to the Pub/Sub subscription
* Add Netography's GCP service account as a principal for the Pub/Sub subscription
* Add GCP as a new traffic source in Netography Fusion
* Adding Context Integration for GCP to Netography Fusion
* Enabling Cloud DNS logging and adding Cloud DNS as a Traffic Source in Netography Fusion
#### Onboarding multiple projects and folders in a GCP organization
You can onboard an entire GCP organization or folder by following the steps outlined in these documents one time.
You only need to create 1 GCP Pub/Sub topic, 1 GCP Cloud aggregated Logging Sink, 1 GCP Pub/Sub Subscription, and 1 Fusion GCP flow source to onboard GCP VPC flow logs to Fusion for as many VPC, subnets, projects, and sub-folders you have in your GCP organization, or that are in a single folder in your GCP organization.
If you need more granular control over what enabled VPC flow logs should be routed to Netography, you can create 1 GCP Pub/Sub topic, 1 GCP Pub/Sub Subscription, 1 Fusion GCP flow source, and as many Cloud Logging Sinks as you need (eg 1 per project) all routed to the same topic.
Additional information on using an aggregated logging sink and its benefits and limitations are described in our document [Logging sink design patterns](https://docs.netography.com/quick-start/quickstart-gcp/logging-sink-design-patterns).
{% hint style="info" %}
**🤖Using Terraform to automate onboarding**
Access Netography's Terraform automation at our GitHub repo: . For access to the repo, email with your GitHub ID or with a request for access to the latest release package.
Netography provides a Terraform project, `neto-onboarding,` that provides Netography Fusion Cloud Onboarding Automation for AWS Organizations, Azure Tenants, and GCP Organizations.
This automation provides the following capabilties, which you can use in whole or part:
* Enables and configure AWS VPC flow logs, Azure VNet flow logs, and GCP VPC flow logs based on a simple policy and tags that defines which VPC/VNet are in scope.
* Deploy all the infrastructure required to integrate to Fusion across multiple accounts (AWS), subscriptions (Azure), and projects (GCP) in a single deployment
* Adds VPCs/VNets configured for flow logging to Netography Fusion as traffic sources.
* Deploys a single AWS Lambda function, Azure Function, or Google Function that provides context enrichment across all the accounts/subscriptions/projects as an outbound push from your cloud to the Fusion API, eliminating the need to add context integrations from the Fusion portal, to grant Netography permissions to directly enumerate resource properties, or to add individual context integrations in Fusion for each cloud account.
* Monitor for VPC/VNet changes and trigger enabling and configuring flow logs, and onboarding to Fusion new VPCs/VNets that are in scope, and offboarding VPCs/VNets that are removed or no longer in scope.
{% endhint %}
If you have GCP organization policy constraints in place, you may be unable to perform these steps until you update the organizational policies.
If you receive an error referring to an organization policy, update the policy and retry. Updating an organization policy requires the *Organization Policy Administrator* role (`roles/orgpolicy.policyAdmin`).
# Diagram: GCP Integration to Fusion

# Video Guides
Below is a video series based on steps in the Quickstart: GCP for Flow Log Ingestion , Context Enrichment , and DNS Ingestion . These videos are meant to augment the written guides but can't replace t
Below is a video series based on steps in the [Quickstart: GCP](/cloud-onboarding/gcp-cloud-onboarding/quickstart-gcp) for **Flow Log Ingestion**, **Context Enrichment**, and **DNS Ingestion**.
These videos are meant to augment the written guides but can't replace them, you'll still need to reference the written guides throughout the setup process.
### Integrating GCP VPC Flow Logs with Fusion
{% embed url="" %}
### Adding GCP Context Integration for Context Enrichment in Fusion
{% embed url="" %}
### Integrating GCP Cloud DNS resolver logs to Fusion
{% embed url="" %}
# Enable VPC Flow Logs (Network Management API)
The Network Management API lets you configure VPC Flow Logs for organizations, Virtual Private Cloud (VPC) networks, subnets, VLAN attachments for Cloud Interconnect, and Cloud VPN tunnels. 📘 Before
The Network Management API lets you configure VPC Flow Logs for organizations, Virtual Private Cloud (VPC) networks, subnets, VLAN attachments for Cloud Interconnect, and Cloud VPN tunnels.
{% hint style="info" %}
**📘Before you begin:**
This guide assumes you have permissions with the `Network Management Admin` role (`roles/networkmanagement.admin`), granted as follows:
* Organization level (required if you want to configure VPC Flow Logs for an organization)
* Project level (required if you want to configure VPC Flow Logs for a VPC network, subnet, VLAN attachment, or Cloud VPN tunnel)
{% endhint %}
*The following instructions are based on Google documentation here, which may be useful to refer to if needed:* [*https://docs.cloud.google.com/vpc/docs/using-flow-logs*](https://docs.cloud.google.com/vpc/docs/using-flow-logs)
## Prerequisites
1. Navigate to [\](https://console.cloud.google.com/apis/api/networkmanagement.googleapis.com), and click "Enable".

2. In the Google Cloud console, go to the [VPC networks page](https://console.cloud.google.com/networking/networks/list).

{% hint style="info" %}
**📘Options for Flow Log Enablement**
VPC Flow logs can be enabled at the following levels:
1. Subnet
2. VPC
3. Organization (requires the `resourcemanager.organizations.get` permission.)
The lowest level policy configured will supercede the higher policy.
{% endhint %}
## Option 1. Enabling VPC Flow Logs at the Subnet Level
1. On the **Subnets in current project** tab, select one or more subnets and then click **Manage flow logs**.

2. In **Manage flow logs**, click **Add new configuration.** This will configure a new VPC flow log configuration.
3. Do one of the following:
1. If you selected one subnet, in the **Configurations — Subnets** section, click **Add a configuration**.

2. If you selected multiple subnets, in the **Configure VPC Flow Logs** section, select **Network Management API**.

4. For **Name**, enter a name for the new VPC Flow Logs configuration.
5. Change the **Aggregation Interval** to `1 minute`.
6. Optional: Adjust the **Description** and any of the settings in the **Advanced settings** section:
1. **Log filtering**: By default, **Keep only logs that match a filter** is deselected.
2. **Include metadata in the final log entries**: By default, **Metadata annotations** includes all fields.
3. **Secondary sampling rate**: `100%` means that all entries generated by the primary flow log sampling process are kept.
7. Click **Save**.
## Option 2. Enabling VPC Flow Logs for VPC Networks
1. On the **Networks in current project** tab, select one or more networks and then click **Manage flow logs**.

2. In **Manage flow logs**, click **Add new configuration.** This will configure a new VPC flow log configuration.

3. In the popup window, under **Configurations - VPC networks** click on **Add a configuration**.

4. For **Name**, enter a name for the new VPC Flow Logs configuration.
5. Change the **Aggregation Interval** to `1 minute`.
6. Optional: Adjust the **Description** and any of the settings in the **Advanced settings** section:
1. **Log filtering**: By default, **Keep only logs that match a filter** is deselected.
2. **Include metadata in the final log entries**: By default, **Metadata annotations** includes all fields.
3. **Secondary sampling rate**: `100%` means that all entries generated by the primary flow log sampling process are kept.
7. Click **Save**.
## Option 3. Configuring VPC Flow Logs at the Organization Level
Configurations created at an organizational level will apply to all VPCs within that organization.
1. Navigate to the [VPC Flow Logs](https://console.cloud.google.com/networking/vpc-flow-logs) configuration page.

2. Click **Add VPC Flow Logs configuration** and then click **Add a configuration for the organization**.

3. For **Name**, enter a name for the new VPC Flow Logs configuration.
4. Change the **Aggregation Interval** to `1 minute`.
5. Optional: Adjust the **Description** and any of the settings in the **Advanced settings** section:
6. Optional: Adjust the **Description** and any of the settings in the **Advanced settings** section:
1. **Log filtering**: By default, **Keep only logs that match a filter** is deselected.
2. **Include metadata in the final log entries**: By default, **Metadata annotations** includes all fields.
3. **Secondary sampling rate**: `100%` means that all entries generated by the primary flow log sampling process are kept.
7. Click **Save**.
# Create a Pub/Sub topic
Create a Cloud Pub/Sub topic 📘 Onboarding multiple projects at an organization or folder level: You can create a single topic in a designated project that you will use for centralized logging resourc
{% hint style="info" %}
**📘Onboarding multiple projects at an organization or folder level**
You can create a single topic in a designated project that you will use for centralized logging resources. This topic can be used as the destination for an aggregated sink, multiple individual project Cloud Logging Sinks, or a combination of the two.
{% endhint %}
1. Go to the **Pub/Sub Topics** page in the Google Cloud console.

2. Click **Create Topic**.

3. Fill out the form using the configuration values below, then click **Save**.

| Field | Value |
| ---------------------------- | ---------------------------------------------- |
| `Topic ID` | Any value ( e.g. `neto-flowlogs-pubsub-topic`) |
| `Add a default subscription` | `No` |
| `Use a schema` | `No` |
| `Enable ingestion` | `No` |
| `Enable message retention` | `Yes`- `1 Day` |
{% hint style="success" %}
**✅You're done!**
{% endhint %}
# Logging sink design patterns
📘 Choosing the right design pattern for GCP logging sinks: There is no single design for GCP logging sinks that is right for all organizations. Reach out to Vectra Support if you would like further
{% hint style="info" %}
**📘Choosing the right design pattern for GCP logging sinks**
There is no single design for GCP logging sinks that is right for all organizations. Reach out to Vectra Support if you would like further guidance in this area.
We would be happy to setup a design session to discuss your specific organization's use case and requirements and determine the best approach together, or review a proposed design before you implement it.
{% endhint %}
## Using an aggregated sink for onboarding all projects in a GCP organization or folder
If you are onboarding all the projects in a GCP organization, or all the projects that are children of a folder, you can use an aggregated sink to simplify the deployment. Using an aggregated sink lets you create 1 sink for a GCP organization or folder rather than 1 sink per project.
When you create an aggregated sink following these steps, all flow logs that are enabled in all child projects (including nested folders) will be routed to the aggregated sink. This will include any new projects, VPCs, or subnetworks that get added as children, and any new flow logs that are enabled will be automatically included.
An aggregated sink at the organization or folder level is ideal if you want to onboard all enabled flow logs within an organization or folder. If you have multiple folders to onboard (that are not nested within each other), you can create 1 aggregated sink for each folder, and route each of those sinks to the same Pub/Sub topic.
### Using exclusion filters to exclude project(s) or subnetwork(s)
If you want to include all the enabled flow logs by default, but exclude specific projects or subnetworks (or any other criteria you can write a filter for in GCP), you can add up to 50 exclusion filters to a sink (and each filter can be 20k characters with logical operators).
To exclude a project: `logName:projects/PROJECT_ID`
To exclude a subnetwork: `resource.labels.subnetwork_name"=SUBNET_NAME"`
For more filter examples, see [GCP Logging > Sample queries](https://cloud.google.com/logging/docs/view/query-library).
### Excluding newly enabled flow logs
If you are in an organization that uses VPC flow logs for multiple use cases, such as application troubleshooting directly in GCP, you may face the circumstance where an application team needs to enable VPC flow logs for a set of subnetworks that will generate a very high volume of logs, but you do not want to onboard these flow logs to Fusion.
The default behavior of a sink is to include all these logs by default.
In this case, you will want to ensure any GCP administrator that can enable flow logs is aware of what folders have sinks that will capture these logs by default, and that an exclusion filter needs to be added to the sink **BEFORE** these flow logs are enabled to avoid creating an undesired spike in flow log volume.
### Manually including newly enabled flow logs
If you are onboarding a limited scope of projects or subnetworks to Fusion and want to maintain tighter control over what flow logs are onboarded, so that another GCP administrator can not inadvertently start sending flow logs to Fusion by enabling flow logs in a subnetwork they control, you may want to instead use a sink design that only includes the enabled flow logs that you specify and not any onboard any newly enabled flow logs by default.
In this case, instead of using an exclusion filter for the sink, you can use the **Inclusion Filter** to specify only the specific projects, subnetworks, or other criteria you want to use. The same filters shown for exclusions above can be used in the inclusion filter to include only those matching the filter.
You can end up with a very long inclusion filter if you individually include each project or subnetwork by name, and if you attempt to do this for hundreds of criteria, you will reach the 20K character limit for a filter and no longer be able to add more. Use this pattern in cases where the filter you will write and its length will not approach that limit or become too complex to manage.
### Additional steps when creating an aggregated sink
To use an aggregated sink, you will need `Owner` access to the sink's destination, and to perform the following steps when creating the sink:
1. Select the organization or folder to onboard in the GCP project picker.
2. When creating the sink, select `Include logs ingested by this folder and all child resources`in the section **Choose logs to include in sink** (this option will not appear if you selected a project).
3. Add the sink's **writer identity** as a principal by using IAM, and then grant it the Pub/Sub Publisher role ( `roles/pubsub.publisher`). See [GCP: Route logs to supported destinations > Set destination permissions](https://cloud.google.com/logging/docs/export/configure_export_v2#dest-auth). *This step may not be required in your organization.*
For more information on aggregated sink configuration, see [GCP: Collate and route organization- and folder-level logs to supported destinations](https://cloud.google.com/logging/docs/export/aggregated_sinks#create_an_aggregated_sink)
Follow these steps using the configuration settings below: [GCP: Create a sink](https://cloud.google.com/logging/docs/export/configure_export_v2#creating_sink).
# Create a Logging Sink Pub/Sub for the topic
Create a Cloud Logging Sink Pub/Sub Go to the Log Router page in the Google Cloud console. Select the project to create the sink in. If you are using an aggregated sink, you will want to select a fold
1. Go to the Log Router page in the Google Cloud console.

2. Select the project to create the sink in. If you are using an aggregated sink, you will want to select a folder or an organization instead.

3. Click **Create sink**.

4. While walking through the wizard steps, Select **Cloud Pub/Sub topic** for your **Sink Destination Service** and choose the topic you created in a previous step.

Use the inclusion filter of `(resource.type="gce_subnetwork" AND log_id("compute.googleapis.com/ vpc_flows")) OR (resource.type="vpc_flow_logs_config" AND log_id("networkmanagement.googleapis.com/vpc_flows"))`

| Field | Value |
| -------------------------------------- | ------------------------------------------------------------------------------- |
| `Sink name` | Any value ( e.g. `neto-flowlogs-sink`) |
| `Sink description` | Any value (e.g. Netography Fusion flow log ingest) |
| `Sink destination service type` | `Cloud Pub/Sub topic` |
| `Sink destination Cloud Pub/Sub topic` | Create a topic or use topic created in previous step |
| `Inclusion filter` | `resource.type="gce_subnetwork" AND log_id("compute.googleapis.com/vpc_flows")` |
{% hint style="info" %}
If you are using org level configuration, you will need to make an agregated logging sink as well at the org level. Use the inclusion filter of `resource.type="vpc_flow_logs_config" AND log_id("networkmanagement.googleapis.com/vpc_flows")`
{% endhint %}
{% hint style="success" %}
**✅You're done!**
{% endhint %}
# Create a Pub/Sub pull subscription
Create a Pub/Sub Pull Subscription to a topic Go to the Topics page in the Google Cloud console. Click ⋮ next to the topic you created in a previous step and select Create Subscription . Fill out the
1. Go to the **Topics** page in the Google Cloud console.

2. Click **⋮** next to the topic you created in a previous step and select **Create Subscription** .

3. Fill out the form using the configuration values below, default values for all other fields can be used. Click **Save**.
  
| Field | Value |
| ---------------------------- | -------------------------------------------------------------------- |
| `Subscription ID` | Any value ( e.g. `neto-flowlogs-sub`) |
| `Cloud Pub/Sub Topic` | `Topic ID` from previous steps (if creating from Subscriptions page) |
| `Delivery Type` | `Pull` |
| `Message retention duration` | `1 Day` *(or based on your requirements)* |
| `Retry policy` | `Retry after exponential backoff delay` (Default min/max values) |
{% hint style="success" %}
**✅You're done!**
{% endhint %}
# GCP service account permissions
Prepare GCP so Vectra can be added as a Pub/Sub principal.
{% hint style="info" %}
**📘The following steps are a prerequisite for adding Vectra as a principal to the Pub/Sub subscription.**
Before you can add Vectra as a principal, you must first grant Vectra's GCP identifier the initial permission GCP requires to certify Vectra is an entity that can be granted access to any of your resources.
**These steps do NOT grant Vectra any permissions or access to any resources in your organization**.
The following steps only enable you to grant Vectra select and specific access to individual resources in the future after these steps have been completed.
{% endhint %}
{% hint style="warning" %}
**🚧Organization Policy Administrator is needed to complete these steps.**
Updating an organization policy requires the Organization Policy Administrator role `roles/orgpolicy.policyAdmin`
{% endhint %}
{% hint style="info" %}
**📘Organizational policy requirement needed to complete these steps**
`iam.disableServiceAccountKeyCreation`needs to be set to **Not enforced** at the organization or project level
{% endhint %}
1. Go to the project picker, click the **All** tab, and select your **Organization**, instead of your project.
 
2. Go to the **Organization Policies** page

3. Click Filter above the policies table, type Domain restricted sharing.

4. You should see 1 policy with ID `constraints/iam.allowedPolicyMemberDomains`. Click on **⋮** for the actions menu then **Edit Policy**.

5. Choose **Override parent's policy** and select **Replace** for **Policy enforcement**.

6. Add a new rule (or add a value to an existing rule) for the policy with **Policy values** set to **Custom** and **Policy type** set to **Allow**.
7. Add value `C04ddcbu8` for Vectra.

{% hint style="success" %}
**✅You're done!**
{% endhint %}
# Add Vectra as a principal
Add Vectra's GCP service account as a principal to the Pub/Sub subscription Go to the Subscriptions page in the Google Cloud console. Select the subscription you created in the previous step to brin
1. Go to the Subscriptions page in the Google Cloud console.

2. Select the subscription you created in the previous step to bring up the subscription info panel on right.

3. Select **Add Principal** in the info panel on the far right.

1. Add `sa-cloud@netography.iam.gserviceaccount.com` as the **Principal**, and assign **Pub/Sub -> Pub/Sub Subscriber** for the role, then click **Save**.

{% hint style="success" %}
**✅You're done!**
{% endhint %}
# Add GCP as a new flow source in Vectra Fusion
Add a new GCP flow source to Fusion In the Fusion portal, click the ⚙️ -\> Settings -\> Traffic Sources -\> Add Traffic Source -\> Flow GCP Add the GCP Project ID containing the Pub/Sub subscr
1. In the Fusion portal, click the ⚙️ -> **Settings** -> **Traffic Sources** -> **Add Traffic Source** -> **Flow GCP**
 
2. Add the GCP Project ID containing the Pub/Sub subscription and Pub/Sub Subscription ID you created in the previous steps.

{% hint style="success" %}
**✅You're done!**
{% endhint %}
# Add context integration to Fusion
📘 You need a GCP service account to setup a context integration.: Follow the initial steps below to create one. 1. Create a GCP service account Go to the Service Accounts page Click Create Service Ac
{% hint style="info" %}
**You need a GCP service account to setup a context integration.**
Follow the initial steps below to create one.
{% endhint %}
## 1. Create a GCP service account
1. Go to the Service Accounts page

2. Click **Create Service Account** and follow the steps in the wizard.

3. Create a service account name; your service account ID email address will be auto-created for you.

4. Click **Select a role**, use the **Filter**, type **viewer** into the filter, click **Viewer** to give this service account a **Viewer role**.

Leave the rest set as default.
## 2. Create your service account access keys and export a JSON file
#### The following steps will enable you to automate context configuration in Vectra Fusion.
1. Click **:** to access Actions for your newly created service account, then select **Manage keys**.

2. Click the **Add Key** menu and select **Create new key**

3. Choose **JSON** format. This will enable you to export a file that will automate context configuration in Vectra Fusion and reduce setup to one step.

4. The **JSON** file containing your private key will be auto-downloaded to your computer, delete this file once you're done with it.

## 3. Create a new Context Integration in Vectra Fusion and upload your JSON file.
1. In the Fusion portal, click the ⚙️ -> **Settings** -> **Traffic Sources** -> **Context Integrations** -> **Add Integrations**

2. Select **Google Cloud Provider**

3. Use the "**IMPORT FROM JSON**" button to import your JSON file you exported from GCP.

4. Leave **Zone** blank to automatically include all zones.

5. All fields will be auto-completed and your private key will be imported.
6. Click **Create and Run** to save.

{% hint style="success" %}
**You're done!**
{% endhint %}
Check **Context Labels** to verify your context integration is working as expected

# Adding DNS as a Traffic Source
Enable DNS logging Before you can start, you need to use DNS policies to enable logging for your networks. When you enable query logging, every DNS query to a Cloud DNS private managed zone is logged,
## 1. Enable DNS logging
Before you can start, you need to use DNS policies to enable logging for your networks.
When you enable query logging, every DNS query to a Cloud DNS private managed zone is logged, [see more on this topic from GCP's own documentation](https://cloud.google.com/dns/docs/monitoring).
To enable logging for a network that does not have a DNS policy, you'll need to run the dns policies create command using the GCP Cloud Shell terminal.
1. Click the icon in the upper right to open GCP Cloud Shell in your web browser.

2. Copy the following command and edit it, changing `netodocsdns` to your own preferred policy name, and `netodocsnet` to the name of your network you want to enable DNS logging on.
```
gcloud dns policies create netodocsdns \
--networks=netodocsnet \
--enable-logging \
--description=netodocsdnspolicy
```
3\. Paste the command into Cloud Shell and hit enter

4. you may see this question: **API \[dns.googleapis.com] not enabled on project \[netodocs]. Would you like to enable and retry (this will take a few minutes)? (y/N)?**, just hit **Y** here.
5. When the command has completed successfully and DNS logging is enabled, you should see something like the following:

{% hint style="warning" %}
**Troubleshooting steps**
{% endhint %}
## 2. Create a sink
1. Go to **Log router**

2. Click **Create sink**

3. Give your sink any name in step 1, for **Sink destination** in step 2, Select sink service **Cloud Pub/Sub topic** and select **Create a topic**

#### Taking a brief detour to create a new topic for DNS inside of the Sink destination wizard
4. Give your new topic any name, enable message retention and set it to 1 day, leave everything else set as default, and click **Create**.

#### Add a filter to include DNS logs in the sink
Now that our new topic has been created, we're back in the **Sink creation wizard**.
5. You need to add Cloud DNS logs to the sink by using an inclusion filter of `resource.type="dns_query"`

6. This is how your finalized wizard should look when you're ready to click **Create Sink**, including your newly created topic, and a successfully saved inclusion filter.

## 3. Create a Pub/Sub Pull Subscription to the new DNS topic
1. Go to topics

2. Find your DNS topic you created in a previous step, click the **:** to access Actions, and click **Create subscription**

3. Give your subscription any name, and set the **Delivery type** to **Pull**

4. Set the **Message retention duration** to 1 day

5. Finally, for the **Retry policy** enable **Retry after exponential backoff delay** and leave the reset set as defaults.

## 4. Add Netography's GCP service account as a principal to the Pub/Sub subscription
1. Go to the Subscriptions page in the Google Cloud console.

2. Select the subscription you created in the previous step to bring up the subscription info panel on the right.

3. Select **Add Principal** in the info panel on the far right.

1. Add `sa-cloud@netography.iam.gserviceaccount.com` as the **New principal**, and assign **Pub/Sub -> Pub/Sub Subscriber** for the role, then click **Save**.

## 5. Add a new GCP DNS traffic source to Fusion
1. In the Fusion portal, click the ⚙️ -> **Settings** -> **Traffic Sources** -> **Add Traffic Source** -> **DNS GCP**
 
2. Give your DNS integration any name, enter your GCP **Project ID** and the new **Subscription ID** you created in the previous steps. Click **Save**.

{% hint style="success" %}
**You're done!**
{% endhint %}
# IBM Cloud Onboarding
{% hint style="info" %}
New to Fusion cloud onboarding? Start with [Fusion Onboarding for Cloud Engineers](/cloud-onboarding/fusion-onboarding-for-cloud-engineers) for deployment models, scope planning, and cloud-specific guidance.
{% endhint %}
# OCI Cloud Onboarding
{% hint style="info" %}
New to Fusion cloud onboarding? Start with [Fusion Onboarding for Cloud Engineers](/cloud-onboarding/fusion-onboarding-for-cloud-engineers) for deployment models, scope planning, and cloud-specific guidance.
{% endhint %}
# Ingest Flow Logs
Configure network flow logs to be ingested by Fusion by following the instructions below. If this is your first time configuring Fusion, the Quick Start Guides for AWS, Azure, \& GCP are the best p
Configure network flow logs to be ingested by Fusion by following the instructions below.
If you are onboarding cloud flow logs, start with [CLOUD ONBOARDING](/cloud-onboarding/fusion-onboarding-for-cloud-engineers).
If you want to ingest NetFlow, sFlow, or IPFIX from network devices, see [Ingesting NetFlow, sFlow, & IPFIX to Fusion](https://docs.netography.com/ingest-network-traffic-logs/netflow-sflow).
# Azure Virtual network (VNet) Flow Log Setup
Vectra Fusion ingests Virtual network (VNet) flow logs from Azure via an Azure Storage account. The steps to integrate with Azure are: Register Microsoft Insights provider (in each Azure subscription
Vectra Fusion ingests Virtual network (VNet) flow logs from Azure via an Azure Storage account. The steps to integrate with Azure are:
1. Register Microsoft Insights provider (in each Azure subscription containing virtual networks you are onboarding).
2. Create a storage account in Azure (for each region you are onboarding virtual networks).
3. Create a flow log for the virtual network in Azure (for each virtual network you are onboarding).
4. In Fusion, Add Azure VNet as a new flow source (for each virtual network you are onboarding).
In addition to ingesting VNet flow logs, you may want to enrich them with context from Azure resources by adding the [Microsoft Azure context integration](/enrich-traffic-with-context/configure-context-integrations/azure).
{% hint style="info" %}
**🤖Using Terraform to automate onboarding**
Access Vectra's Terraform automation at our GitHub repo: . For access to the repo, email with your GitHub ID or with a request for access to the latest release package.
Vectra provides a Terraform project, `neto-onboarding,` that provides Vectra Fusion Cloud Onboarding Automation for AWS Organizations, Azure Tenants, and GCP Organizations.
This automation provides the following capabilties, which you can use in whole or part:
* Enables and configure AWS VPC flow logs, Azure VNet flow logs, and GCP VPC flow logs based on a simple policy and tags that defines which VPC/VNet are in scope.
* Deploy all the infrastructure required to integrate to Fusion across multiple accounts (AWS), subscriptions (Azure), and projects (GCP) in a single deployment
* Adds VPCs/VNets configured for flow logging to Vectra Fusion as traffic sources.
* Deploys a single AWS Lambda function, Azure Function, or Google Function that provides context enrichment across all the accounts/subscriptions/projects as an outbound push from your cloud to the Fusion API, eliminating the need to add context integrations from the Fusion portal, to grant Vectra permissions to directly enumerate resource properties, or to add individual context integrations in Fusion for each cloud account.
* Monitor for VPC/VNet changes and trigger enabling and configuring flow logs, and onboarding to Fusion new VPCs/VNets that are in scope, and offboarding VPCs/VNets that are removed or no longer in scope.
{% endhint %}
## Prerequisites
* Access to the Azure subscription(s) to onboard with an `Owner` or `Contributor` role, or a custom role with the specific permissions required for each step.
* To register Microsoft Insights provider requires `/register/action` operation permissions for the Insights provider. The permission is included in the `Owner` and `Contributor`roles.
* To create flow logs for a virtual network requires `Microsoft.Network/networkWatchers/configureFlowLog/action`permission. The permission is included in the `Owner`, `Contributor`, and `Network contributor` roles.
* To create a storage account requires `Microsoft.Storage/storageAccounts/*` permission. The permission is included in the `Owner`, `Contributor`, and `Storage account contributor` role.
* Azure Network Watcher must be enabled in the subscription and region for which the virtual network flow logs are enabled. This is enabled by default in Azure, but if you previously chose to opt out of Network Watcher automatic enablement, you must manuallly enable Network Watcher in each subscription and region containing virtual networks you are onboarding to Fusion. See [Enable or Disable Azure Network Watcher](https://learn.microsoft.com/en-us/azure/network-watcher/network-watcher-create?tabs=portal).
* If Azure Policy is in use, you may be restricted from performing these steps, even if you have the `Azure Global Administrator` role. If this is the case, you will receive an Azure `RequestDisallowedByPolicy` error. See [Resolve errors for request disallowed by policy](https://learn.microsoft.com/en-us/azure/azure-resource-manager/troubleshooting/error-policy-requestdisallowedbypolicy?tabs=azure-cli).
## Microsoft Azure Instructions
### 1. Register Microsoft Insights Provider
**You can skip this step if VNet flow logs are already enabled or if the `Microsoft.Insights` provider is already registered in the Azure subscription.**
`Microsoft.Insights` provider must be registered in the virtual network's Azure subscription. You only need to perform this action once for each subscription containing virtual networks being monitored.
Follow these steps to register the `Microsoft.Insights` provider: [Microsoft Register Insights provider page](https://learn.microsoft.com/en-us/azure/network-watcher/vnet-flow-logs-portal#register-insights-provider).
#### Azure Console Steps
1. Enter *subscriptions* in the search box at the top of Azure Console and select **Subscriptions** from the results.
2. In the **Subscriptions** list, select the Azure subscription that you wish to enable the provider for.
3. Under **Settings**, select **Resource providers**.
4. Enter *insight* in the filter box.
5. Confirm the status of the **Microsoft.Insights** provider displayed is **Registered**. If the status is **NotRegistered**, select the **Microsoft.Insights** provider then select **Register**.
### 2. Create a Storage Account for each region
**If you are using the Azure Console to perform these steps, you can create a new storage account while creating the flow logs in the next step and skip this step.**
Azure writes flow logs to an Azure storage account, and Fusion reads flow logs from the Azure storage account. Create a storage account for each region that contains virtual networks you are onboarding.
If you are onboarding multiple subscriptions in a single Azure tenant, you can have 1 set of storage accounts per region in a single centralized logging subscription and direct the flow logs from any subscription in the tenant to the corresponding storage account for that region.
#### Storage Account Configuration
| Field | Value |
| -------------------- | ---------------------------------------------------------------------------------------- |
| Subscription | The same subscription as the virtual network, or a subscription in the same Azure tenant |
| Resource Group | Any existing resource group, or create a new one (e.g. `rg_neto_logging`) |
| Storage Account Name | Any unique name (e.g. `st_neto_vnetlogs_westus`) |
| Region | The same region as the virtual network(s) |
| Performance Tier | Standard |
| Redundancy | Locally-redundant Storage (LRS) |
All other settings can use Azure's default configuration. The `Advanced > Security > Enable storage account key access` setting must remain in its default setting,`True`, for Azure Network Watcher to write flow logs to the storage account and Fusion to read flow logs from the storage account.
{% hint style="info" %}
**📘Restricting Azure Storage Account access to Vectra's allowed IPs**
The `Advanced > Networking > Network Access` setting for a storage account in Azure has a default value of `Enable public access from all networks`. This setting allows any IP to attempt to authenticate with an access key to the storage account. It does not allow unauthenticated access to the storage account.
To further secure the storage account, restrict access to only the Vectra Fusion Poller IPs required to read the flow logs. The IPs to allow are listed in the Vectra Fusion Portal in **Settings** > **Account Overview** > **System Allow Lists** > **Pollers**.
Create virtual network rules to restrict IP access to these IPs and grant access to the trusted Azure service `Microsoft.Network`to allow Azure Network Watcher to write the flow logs to the account. See: [Configure Azure Storage firewalls and virtual networks > Grant access from a virtual network](https://learn.microsoft.com/en-us/azure/storage/common/storage-network-security?tabs=azure-portal#grant-access-from-a-virtual-network) and [Configure Azure Storage firewalls and virtual networks > Grant access to trusted Azure services](https://learn.microsoft.com/en-us/azure/storage/common/storage-network-security?tabs=azure-portal#grant-access-to-trusted-azure-services).
{% endhint %}
### 3. Create a Flow Log for each Virtual network
**You can skip this step if VNet flow logs are already enabled.**
Follow these steps using the configuration settings below: [Create a flow log section of the Manage VNET flow page](https://learn.microsoft.com/en-us/azure/network-watcher/vnet-flow-logs-portal#create-a-flow-log).
#### Flow Log Configuration
| Field | Value |
| -------------------- | -------------------------------------------------------------------------------------------------------------------------------------- |
| **Project details** | |
| Subscription | Select the Azure subscription of your virtual network that you want to log |
| Flow Log Type | Select **Virtual Network** then select the virtual networks |
| Flow Log Name | You can use the default name of`{ResourceName}-{ResourceGroupName}-flowlog` or enter your own |
| **Instance details** | |
| Subscription | Select the Azure subscription of the storage account to write flow logs to |
| Storage Accounts | Select the storage account that you want to write flow logs to.. If you skipped step 2 above, select **Create a new storage account**. |
| Retention (days) | 1 |
You can adjust the retention period to retain logs within the Azure storage account based on your organization's requirements.
#### Azure Console Steps
1. In the search box at the top of the portal, enter *network watcher*. Select **Network Watcher** from the search results.
2. Under **Logs**, select **Flow logs**.
3. In **Network Watcher | Flow logs**, select **+ Create** or **Create flow log** blue button.
4. On the **Basics** tab of **Create a flow log**.
5. Select **Review + create.**
6. Review the settings, and then select **Create**.
For more information related to managing VNet Flow Logs in Azure, refer to Microsoft's [Create, change, enable, disable, or delete virtual network flow logs using the Azure portal](https://learn.microsoft.com/en-us/azure/network-watcher/vnet-flow-logs-portal) article.
## Vectra Fusion Instructions
### 4. Add a new Azure VNet flow source to Fusion
In the Fusion portal, click the gear icon to go to Settings, navigate to Traffic Sources, click Add Traffic Source, select **Azure VNet**, and fill out the form using the configuration below.
#### Azure VNet Flow Source Configuration
The following fields are specific to the Azure VNet configuration.
All of these field values can be located in the Azure Portal by going to **Network Watcher**, expanding the **Logs** section, selecting **Flow Logs**, and finding the row in the table for the flow log you are adding. The value to use is either directly visible in the table, or can be found by following the links noted in the table below.
| Field | Description | Azure Network Watcher Flow Logs Table Field To Use |
| --------------- | -------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------- |
| Region | Azure region the Vnet and storage account are located in (they are always the same) | Location |
| Container Name | Storage account container name. Use the value `insights-logs-flowlogflowevent`for all standard configurations. | *Storage account* > Data Storage > Containers |
| Subscription ID | Virtual network subscription ID | *Subscription name* > Overview |
| Resource Group | Network Watcher Resource Group name (e.g. `NETWORKWATCHERRG`) | Resource group |
| Network Watcher | Network Watcher Name (e.g. `NetworkWatcher_eastus/FlogLog_vnet2`) | Name - The network watcher name is in parentheses |
| Flow Log | Flow Log Name (eg `FlowLog_vnet2`) | Name - The flow log name is the value excluding what is in parentheses |
| Account Name | Storage Account's Access Name | Storage account |
| Account Key | Storage Account's Access Key to authenticate | *Storage Account* > Security + Networking > Access keys > Key |
# Azure NSG Flow Logs Setup
Microsoft Azure Console method
This document provides instructions for configuring the collection of Azure Network Security Group (NSG) Flow Logs.
The 3 methods covered are:
* Micrsoft Azure Portal
* Microsoft Azure Command Line Interface (CLI)
* Microsoft Azure Resource Manager template
### Requirements
Before you begin configuring NSG Flow Log collection, make sure the following environment prerequisites are met:
* Your Storage Account must be of type General-purpose v2 or Blob storage.
* Your Network Security Group and Storage Account should be in the same region.
* NSG Flow Logs do not work with storage accounts that have hierarchical namespace enabled.
### Azure Steps
1. Register Insights provider
2. Configure Network Security Group
3. Configure Storage account
4. Configure Network Watcher
5. Enable NSG flow logs
#### Register Insights provider
NSG flow logging requires the Microsoft.Insights provider. To register the provider, complete the following steps:
1. In the top, left corner of the portal, select All services. In the Filter box, type Subscriptions. When Subscriptions appear in the search results, select it.
2. From the list of subscriptions, select the subscription you want to enable the provider for.
3. Select *Resource providers*, under *Settings*.
4. Confirm that the *Status* for the microsoft.insights provider is *Registered*, as shown in the picture that follows. If the status is Unregistered, then select *Register*, at the top of the table.

#### Create Network Security Group
1. In the top, left corner of the portal, select *All services*. In the Filter box, type *Network security groups*. When Network security groups appear in the search results, select it.
2. On the Network security groups window that appears, choose *Create.*
3. Select the subscription in which to create the storage account.
4. Under the *Resource group* field, select the resource group that you want to create the NSG on.
5. Next, enter a name for your network security group. The name you choose must be unique across Azure.
6. Select a region for your network security group to match the resource group

7. Select Review + Create to review your network security group settings and create the nsg.
8. Select Create.
#### Configure Azure storage account
To create a general-purpose v2 storage account in the Azure portal, follow these steps:
1. On the Azure portal menu, select *All services*. In the list of resources, type *Storage Accounts*. As you begin typing, the list filters based on your input. Select *Storage Accounts*.
2. On the Storage Accounts window that appears, choose *Add.*
3. Select the subscription in which to create the storage account.
4. Under the Resource group field, select the resource group that you want to create storage on.
5. Next, enter a name for your storage account. The name you choose must be unique across Azure. The name also must be between 3 and 24 characters in length, and can include numbers and lowercase letters only.
6. Select a location for your storage account.
7. Leave these fields set to their default values:
| Field | Value |
| --------------- | ------------------------------------------ |
| Deployment mode | Resource Manager |
| Performance | Standard |
| Account kind | StorageV2 (general-purpose v2) |
| Redundancy | Read-access geo-redundant storage (RA-GRS) |
| Access tier | Hot |
1. Select Review + Create to review your storage account settings and create the account.
2. Select Create.
#### Configure Network Watcher
1. In the portal, select *All services*. In the Filter box, enter *Network Watcher*. When Network Watcher appears in the results, select it.
2. Select *Regions*, to expand it, and then select ... to the right of your desired region.
3. Select Enable Network Watcher.
#### Enable NSG flow logs
1. In the top, left corner of the portal, select *All services*. In the Filter box, type *Network Watcher*. When Network Watcher appears in the search results, select it.
2. Under Logs, select *Flow logs*
3. From the list of NSGs, select the NSG you created in step 2.
4. Under Flow logs settings, select On.
5. Select the Flow Logs Version. Version 2 contains flow-session statistics (Bytes and Packets)
6. Select the storage account that you created in step 3.
7. Set Retention (days) to 1, and then select Save.
### Netography Portal Steps
1. Navigate to "Traffic Sources"
2. Click "Add Traffic Source".
3. Click the "Show Advanced" button at the top of the page.
4. Click "Azure NSG".

#### Configuration
The following fields are specific to the Azure configuration.
| Field | Required | Description |
| ------------------------ | -------- | ---------------------------------------- |
| `Region` | yes | Location of the flow source |
| `Container Name` | yes | Storage Account's Container Name |
| `Subscription ID` | yes | Network Security Group's subscription ID |
| `Resource Group` | yes | Network Security Group's Resource Group |
| `Network Security Group` | yes | Network Security Group's Name |
#### Authentication
The following fields are necessary for the integration to authenticate with Azure NSG.
| `Account Name` | yes | The account name to use for this stream |
| -------------- | --- | -------------------------------------------------------------- |
| `Account Name` | yes | The Storage Account's Access Name to use for this stream |
| `Account Key` | yes | Storage Account's Access Key for authenticating to this stream |
# Azure NSG Setup (Resource Manager method)
This document provides instructions for configuring the collection of Azure NSG Flow Logs. There are three methods shown. The first being in the Azure Portal, second Azure CLI, and third Azure Resourc
This document provides instructions for configuring the collection of Azure NSG Flow Logs. There are three methods shown. The first being in the Azure Portal, second Azure CLI, and third Azure Resource Manager (ARM) template.
### Requirements
Before you begin configuring NSG Flow Log collection, make sure the following environment prerequisites are met:
* Your Storage Account must be of type General-purpose v2 or Blob storage.
* Your Network Security Group and Storage Account should be in the same region.
* NSG Flow Logs do not work with storage accounts that have hierarchical namespace enabled.
### ARM Template Steps
1. Register Insights provider
2. Configure Network Security Group
3. Run ARM Template
#### Register Insights provider
NSG flow logging requires the Microsoft.Insights provider. To register the provider, complete the following steps:
1. In the top, left corner of the portal, select All services. In the Filter box, type Subscriptions. When Subscriptions appear in the search results, select it.
2. From the list of subscriptions, select the subscription you want to enable the provider for.
3. Select *Resource providers*, under *Settings*.
4. Confirm that the *Status* for the microsoft.insights provider is *Registered*, as shown in the picture that follows. If the status is Unregistered, then select *Register*, at the top of the table.
#### Configure Azure storage account
To create a general-purpose v2 storage account in the Azure portal, follow these steps:
1. On the Azure portal menu, select *All services*. In the list of resources, type *Storage Accounts*. As you begin typing, the list filters based on your input. Select *Storage Accounts*.
2. On the Storage Accounts window that appears, choose *Add.*
3. Select the subscription in which to create the storage account.
4. Under the Resource group field, select the resource group that you want to create storage on.
5. Next, enter a name for your storage account. The name you choose must be unique across Azure. The name also must be between 3 and 24 characters in length, and can include numbers and lowercase letters only.
6. Select a location for your storage account.
7. Leave these fields set to their default values:
| | |
| --------------- | ------------------------------------------ |
| Deployment mode | Resource Manager |
| Performance | Standard |
| Account kind | StorageV2 (general-purpose v2) |
| Replication | Read-access geo-redundant storage (RA-GRS) |
| Access tier | Hot |
1. Select Review + Create to review your storage account settings and create the account.
2. Select Create.
**Run ARM Template**
Follow this URL to open the template in the Azure portal (Sign-in required)
1. Select the *Subscription* the resource is in.
2. Select the *Resource Group* the resource is in.
3. Select the *Location* the resource is in.
4. Enter the *Network Watcher Name Prefix* or leave the default value.
5. Enter the *Flow Log Name* or leave the default value.
6. Select if NSG is to be created by the template or already exists. The NSG must be in the same resource group and location.
7. Enter the *NSG Name* of the existing or new NSG.
8. Review and agree to Azure's terms
9. Click Purchase\

### Netography Portal Steps
Navigate to Traffic Sources, and click "Add Traffic Source", then select `Azure NSG`

#### Configuration
The following fields are specific to the Azure configuration.
| Field | Required | Description |
| ------------------------ | -------- | ---------------------------------------- |
| `Region` | yes | Location of the flow source |
| `Container Name` | yes | Storage Account's Container Name |
| `Subscription ID` | yes | Network Security Group's subscription ID |
| `Resource Group` | yes | Network Security Group's Resource Group |
| `Network Security Group` | yes | Network Security Group's Name |
#### Authentication
AThe following fields are necessary for the integration to authenticate with Azure NSG.
| `Account Name` | yes | The account name to use for this stream |
| -------------- | --- | -------------------------------------------------------------- |
| `Account Name` | yes | The Storage Account's Access Name to use for this stream |
| `Account Key` | yes | Storage Account's Access Key for authenticating to this stream |
# AWS VPC via S3 Setup (CloudFormation method)
This document provides instructions for configuring the collection of AWS VPC Flow Logs with an S3 bucket and configure log notification with SNS and SQS using AWS CloudFormation. 🚧 It is recommended
This document provides instructions for configuring the collection of AWS VPC Flow Logs with an S3 bucket and configure log notification with SNS and SQS using AWS CloudFormation.
{% hint style="warning" %}
**🚧It is recommended that the s3 bucket is in the same region as the VPC. If you pointed multiple flow logs to the same bucket they will need to be differentiated by the folder prefix.**
{% endhint %}
### AWS CloudFormation Steps
1. Setup supporting configuration with Cloudformation template
2. Create VPC Flow Logs that Publish to S3
#### Setup Cloudformation template
Setup supporting configuration with Cloudformation template
1. In the AWS Console select Services and type cloudformation into the search bar
2. Click Create stack then With new resources(standard)
3. You will see the import overview, click next
4. Make sure Amazon S3 URL is checked and input the following URL then click next
5. Choose a stack name and a unique S3 bucket name
6. TrafficType is ALL by default
7. Add tags for the stack (optional) and click next
8. Review and check the "I acknowledge that AWS CloudFormation might create IAM resources with custom names."
9. Now click Create stack
10. Take note of the information on the Outputs tab\

#### Create VPC Flow Logs
Create VPC Flow Logs that publishes to S3
1. In the AWS Console select Services and type vpc into the search bar
2. Click VPC then select your VPC and click the Flow Logs tab

3. Then click create flow Log
| | |
| ---------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Filter | All |
| Maximum aggregation interval | 1 minute |
| Destination | Send to S3 bucket |
| S3 bucket ARN | Enter your S3 bucket ARN (from stack outputs tab in CF) |
| Format | Custom format |
| Access tier | Select the IAM role |
| Format | Custom format |
| Log format | `${version} ${account-id} ${interface-id} ${srcaddr} ${dstaddr} ${srcport} ${dstport} ${protocol} ${packets} ${bytes} ${start} ${end} ${action} ${log-status} ${tcp-flags} ${type} ${pkt-dstaddr} ${pkt-srcaddr}${instance-id} ${vpc-id} ${az-id} ${sublocation-id} ${sublocation-type} ${subnet-id}` |
4. Click create
### Netography Portal Steps
Navigate to Traffic Sources, and click "Add Traffic Source", then select `AWS S3`

#### Configuration
The path to the S3 bucket ARN is constructed using the `Account ID` and `Region` fields, along with the current date, using the following structure: `AWSLogs/{Account ID}/vpcflowlogs/{Region}/YYYY/MM/DD/`
Example: `AWSLogs/123456789012/vpcflowlogs/us-east-1/2023/06/28/`
The `Prefix` field can be used if the flow logs are being organized in folders. e.g. setting the `Prefix` to `folder_name` would modify the above to become `folder_name/AWSLogs/123456789012/vpcflowlogs/us-east-1/2023/06/28/`
The following fields are specific to the AWS S3 configuration.
| Field | Required | Description | Examples |
| --------------- | -------- | -------------------------------------------------- | -------------- |
| `Account ID` | yes | Account ID of the flow source | 1234-5678-9012 |
| `Region` | yes | Location of the flow source | us-east-1 |
| `Bucket` | yes | The S3 bucket name | bucket\_name |
| `Bucket Region` | yes | The region of the S3 bucket | us-east-1 |
| `Remove Log` | | Remove the log from the S3 bucket after processing | |
| `Prefix` | | Folder prefix | folder\_name |
#### Authentication
Netography Fusion can access your AWS account using one of two different methods:
1. IAM user via an Access Key ID & Secret Access Key
2. IAM Roles using a Custom Trust Policy created by Netography.
**AWS Access Key**
To configure access via Access Key/Secret, select the "Key/Secret" Authentication Type. The values for the ID and Secret are accessible in the AWS IAM console.

**AWS IAM Roles**
You can use an IAM role in Netography Fusion to access your Cloud Flow Logs for flow ingest or account data for the AWS Context Integration. To enable this, go to the portal and retrieve the **AWS Account ID** and **External ID** from your Account Settings. Navigate to the gear button on the top right to view your Account Settings to see the Overview tab as shown below:

In AWS, you will configure permissions using the Account ID grabbed from above to create the IAM Role. When configured, AWS creates the Amazon Resource Number (ARN) for the role. For more information in configuring the permissions to the Account ID, refer to the [external ID guide](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_roles_create_for-user_externalid.html).
{% hint style="warning" %}
**🚧The newly created ARN is required in order to configure IAM role access in the Netography Fusion portal.**
{% endhint %}
Once the ARN has been created, the remaining steps are to toggle the Authentication Type to **Role** in your AWS
S3 configuration settings, input the **AWS Account ID** grabbed earlier from your Netography account settings, and the supply the **ARN configured from AWS** as shown below:

# AWS VPC via S3 Setup (AWS Console method)
This document provides instructions for configuring the collection of AWS VPC Flow Logs with an S3 bucket and configure log notification with SNS and SQS using the AWS Console. 🚧 It is recommended th
This document provides instructions for configuring the collection of AWS VPC Flow Logs with an S3 bucket and configure log notification with SNS and SQS using the AWS Console.
{% hint style="warning" %}
**🚧It is recommended that the s3 bucket is in the same region as the VPC. If you pointed multiple flow logs to the same bucket they will need to be differentiated by the folder prefix.**
{% endhint %}
### AWS Console Steps
* Create S3 bucket
* Create an IAM user
* Optional: Create the SNS Topic
* Optional: Create the SQS queue
* Update S3 bucket
* Publish to S3
#### Create S3 bucket
1. In the AWS Console select Services and type s3 into the search bar
2. Enter your bucket name, select your region, optionally add tags and click "create bucket"

3. From the S3 bucket listing check the box for the bucket you created and click Copy Bucket ARN to make note of it.

#### OPTIONAL: Create the SNS topic
1. In the AWS Console select Services and type sns into the search bar
2. Select "Standard" type.
3. Enter a name for the SNS topic.
4. Add optional tags and click "Create Topic"
#### OPTIONAL: Create the SQS queue
1. In the AWS Console select Services and type sqs into the search bar
2. Enter a queue name and click configure queue
3. Set Message Retention Period to 1 day.

4. Under Access Policy select advanced and use the following JSON. Update the SourceArn with your S3 ARN.
{% tabs %}
````
```
{
"Version": "2012-10-17",
"Id": "PushMessageToSQSPolicy",
"Statement": [
{
"Sid": "allow-sns-to-send-message-to-sqs",
"Effect": "Allow",
"Principal": {
"AWS": "*"
},
"Action": "sqs:SendMessage",
"Resource": "*",
"Condition": {
"StringLike": {
"aws:SourceArn": "arn:aws:s3:::"
}
}
}
]
}
```
````
5. Select your SQS queue under the SNS Subscriptions tab click "Subscribe to Amazon SNS Topic".

6. Choose your SNS topic and Subscribe then click "Save".
7. Make note of your SQS URL and SQS ARN
#### Create Netography Policy
1. In the AWS Console select Services and type "iam" into the search bar
2. Under Access management click Policies
3. Click create policy and then the JSON tab.
4. Use the following after updating arn:aws:s3.
5. Then click review and then create
{% tabs %}
````
```
{
"Version":"2012-10-17",
"Statement":[
{
"Sid":"VisualEditor0",
"Effect":"Allow",
"Action":[
"sqs:DeleteMessage",
"sqs:GetQueueUrl",
"sqs:ReceiveMessage",
"sqs:GetQueueAttributes",
"s3:ListBucket*",
"s3:GetObject*",
"s3:DeleteObject*"
],
"Resource":[
"",
"arn:aws:s3:::/*",
"arn:aws:s3:::"
]
}
]
}
```
````
#### Create an IAM user
1. In the AWS Console select Services and type iam into the search bar
2. Click Add user and enter a user name
3. Check Programmatic access for the Access type and click next
4. Click Attach existing policies directly

5. Enter the policy name you created
6. Select it and click next
7. Fill in your tags (optional) and click next
8. Review and create user
9. Make note of Access Key ID and Secret access Key
10. From the Users table in IAM click the user you create and make note of the user ARN
#### Update S3 bucket
1. Select your bucket and click the properties tab

2. Scroll down to Event notifications and click "Create event notification"

3. Enter a name.
4. Check All object create events.
5. Use SQS Queue for Destination.
6. Select your SQS Queue for SQS Queue.
7. Click "Save".

#### Create VPC Flow Logs that Publish to S3
1. In the AWS Console select Services and type vpc into the search bar
2. Click VPC then select your VPC and click the Flow Logs tab
3. Then click create flow Log

4. Select for Filter
5. Use 1 minute for Maximum aggregation interval
6. Select "Send to an S3 bucket" for Destination
7. Under S3 bucket ARN fill in your s3 bucket arn.
8. Select custom format and select all available attributes.
9. Click "Create flow log"

### Netography Portal Steps
Navigate to Flow Sources, and click "Add Flow Source", then select `AWS S3`

#### Configuration
The path to the S3 bucket ARN is constructed using the `Account ID` and `Region` fields, along with the current date, using the following structure: `AWSLogs/{Account ID}/vpcflowlogs/{Region}/YYYY/MM/DD/`
Example: `AWSLogs/123456789012/vpcflowlogs/us-east-1/2023/06/28/`
The `Prefix` field can be used if the flow logs are being organized in folders. e.g. setting the `Prefix` to `folder_name` would modify the above to become `folder_name/AWSLogs/123456789012/vpcflowlogs/us-east-1/2023/06/28/`
The following fields are specific to the AWS S3 configuration.
| Field | Required | Description | Examples |
| --------------- | -------- | ------------------------------------------------------------------------------------------- | ----------------------------------------------------------- |
| `Account ID` | yes | Account ID of the flow source | 1234-5678-9012 |
| `Region` | yes | Location of the flow source | us-east-1 |
| `Bucket` | yes | The S3 bucket name | bucket\_name |
| `Bucket Region` | yes | The region of the S3 bucket | us-east-1 |
| `Remove Log` | | Remove the log from the S3 bucket after processing | |
| `Prefix` | | Folder prefix | folder\_name |
| `sqs URL` | | If provided, sqs will notify Netography that a new object was written for immediate ingest. | |
#### AWS authentication
Netography Fusion can access your AWS account using one of two different methods:
1. IAM user via an Access Key ID & Secret Access Key
2. IAM Roles using a Custom Trust Policy created by Netography.
**AWS Access Key**
To configure access via Access Key/Secret, select the "Key/Secret" Authentication Type. The values for the ID and Secret are accessible in the AWS IAM console.

**AWS IAM Roles**
You can use an IAM role in Netography Fusion to access your Cloud Flow Logs for flow ingest or account data for the AWS Context Integration. To enable this, go to the portal and retrieve the **AWS Account ID** and **External ID** from your Account Settings. Navigate to the gear button on the top right to view your Account Settings to see the Overview tab as shown below:

In AWS, you will configure permissions using the Account ID grabbed from above to create the IAM Role. When configured, AWS creates the Amazon Resource Number (ARN) for the role. For more information in configuring the permissions to the Account ID, refer to the following AWS guide:
[How to use an external ID when granting access to your AWS resources to a third party](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_roles_create_for-user_externalid.html)
The newly created ARN is required in order to configure IAM role access in the Netography Fusion portal.
Once the ARN has been created, the remaining steps are to toggle the Authentication Type to **Role** in your AWS
S3 configuration settings, input the **AWS Account ID** grabbed earlier from your Netography account settings, and the supply the **ARN configured from AWS** as shown below:

# AWS Transit Gateway Flow Logs via S3
This document provides instructions for configuring the collection of AWS Transit Gateway Flow Logs with an S3 bucket and configure log notification with SNS and SQS using the AWS Console. 🚧 It is re
This document provides instructions for configuring the collection of AWS Transit Gateway Flow Logs with an S3 bucket and configure log notification with SNS and SQS using the AWS Console.
{% hint style="warning" %}
**It is recommended that the s3 bucket is in the same region as the VPC. If you pointed multiple flow logs to the same bucket they will need to be differentiated by the folder prefix.**
{% endhint %}
### AWS Console Steps
* Create S3 bucket
* Create an IAM user
* Optional: Create the SNS Topic
* Optional: Create the SQS queue
* Update S3 bucket
* Publish to S3
#### Create S3 bucket
1. In the AWS Console select Services and type s3 into the search bar
2. Enter your bucket name, select your region, optionally add tags and click "create bucket"

3. From the S3 bucket listing check the box for the bucket you created and click Copy Bucket ARN to make note of it.

#### OPTIONAL: Create the SNS topic
1. In the AWS Console select Services and type sns into the search bar
2. Select "Standard" type.
3. Enter a name for the SNS topic.
4. Add optional tags and click "Create Topic"
#### OPTIONAL: Create the SQS queue
1. In the AWS Console select Services and type sqs into the search bar
2. Enter a queue name and click configure queue
3. Set Message Retention Period to 1 day.

4. Under Access Policy select advanced and use the following JSON. Update the SourceArn with your S3 ARN.
{% tabs %}
````
```
{
"Version": "2012-10-17",
"Id": "PushMessageToSQSPolicy",
"Statement": [
{
"Sid": "allow-sns-to-send-message-to-sqs",
"Effect": "Allow",
"Principal": {
"AWS": "*"
},
"Action": "sqs:SendMessage",
"Resource": "*",
"Condition": {
"StringLike": {
"aws:SourceArn": "arn:aws:s3:::"
}
}
}
]
}
```
````
5. Select your SQS queue under the SNS Subscriptions tab click "Subscribe to Amazon SNS Topic".

6. Choose your SNS topic and Subscribe then click "Save".
7. Make note of your SQS URL and SQS ARN
#### Create Netography Policy
1. In the AWS Console select Services and type "iam" into the search bar
2. Under Access management click Policies
3. Click create policy and then the JSON tab.
4. Use the following after updating arn:aws:s3.
5. Then click review and then create
{% tabs %}
````
```
{
"Version":"2012-10-17",
"Statement":[
{
"Sid":"VisualEditor0",
"Effect":"Allow",
"Action":[
"sqs:DeleteMessage",
"sqs:GetQueueUrl",
"sqs:ReceiveMessage",
"sqs:GetQueueAttributes",
"s3:ListBucket*",
"s3:GetObject*",
"s3:DeleteObject*"
],
"Resource":[
"",
"arn:aws:s3:::/*",
"arn:aws:s3:::"
]
}
]
}
```
````
#### Create an IAM user
1. In the AWS Console select Services and type iam into the search bar
2. Click Add user and enter a user name
3. Check Programmatic access for the Access type and click next
4. Click Attach existing policies directly

5. Enter the policy name you created
6. Select it and click next
7. Fill in your tags (optional) and click next
8. Review and create user
9. Make note of Access Key ID and Secret access Key
10. From the Users table in IAM click the user you create and make note of the user ARN
#### Update S3 bucket
1. Select your bucket and click the properties tab

2. Scroll down to Event notifications and click "Create event notification"

3. Enter a name.
4. Check All object create events.
5. Use SQS Queue for Destination.
6. Select your SQS Queue for SQS Queue.
7. Click "Save".

#### Create Transit Gateway Flow Logs that Publish to S3
1. In the AWS Console select Services and type **transit** into the search bar
2. Click **Transit gateways** then select your Transit gateway ID link.
3. Then click the **create flow log** button.
**Create flow log screen.**
1. Select "**Send to an S3 bucket**" for Destination
2. Under **S3 bucket ARN** fill in your s3 bucket ARN.
3. Select **Custom format** and select all available attributes.
4. Click the **Create flow log** button.

### Netography Portal Steps
1. Navigate to **Settings > Traffic Sources**,
2. Click **Add Traffic Source**.
3. Click the **AWS S3 Transit Gateway** tile.

#### Configuration
The path to the S3 bucket ARN is constructed using the `Account ID` and `Region` fields, along with the current date, using the following structure: `AWSLogs/{Account ID}/vpcflowlogs/{Region}/YYYY/MM/DD/`
Example: `AWSLogs/123456789012/vpcflowlogs/us-east-1/2023/06/28/`
The `Prefix` field can be used if the flow logs are being organized in folders. e.g. setting the `Prefix` to `folder_name` would modify the above to become `folder_name/AWSLogs/123456789012/vpcflowlogs/us-east-1/2023/06/28/`
The following fields are specific to the AWS S3 configuration.
| Field | Required | Description | Examples |
| --------------- | -------- | ------------------------------------------------------------------------------------------- | ----------------------------------------------------------- |
| `Account ID` | yes | Account ID of the flow source | 1234-5678-9012 |
| `Region` | yes | Location of the flow source | us-east-1 |
| `Bucket` | yes | The S3 bucket name | bucket\_name |
| `Bucket Region` | yes | The region of the S3 bucket | us-east-1 |
| `Remove Log` | | Remove the log from the S3 bucket after processing | |
| `Prefix` | | Folder prefix | folder\_name |
| `sqs URL` | | If provided, sqs will notify Netography that a new object was written for immediate ingest. | |
#### AWS authentication
Netography Fusion can access your AWS account using one of two different methods:
1. IAM user via an Access Key ID & Secret Access Key
2. IAM Roles using a Custom Trust Policy created by Netography.
**AWS Access Key**
To configure access via Access Key/Secret, select the "Key/Secret" Authentication Type. The values for the ID and Secret are accessible in the AWS IAM console.

**AWS IAM Roles**
You can use an IAM role in Netography Fusion to access your Cloud Flow Logs for flow ingest or account data for the AWS Context Integration. To enable this, go to the portal and retrieve the **AWS Account ID** and **External ID** from your Account Settings. Navigate to the gear button on the top right to view your Account Settings to see the Overview tab as shown below:

In AWS, you will configure permissions using the Account ID grabbed from above to create the IAM Role. When configured, AWS creates the Amazon Resource Number (ARN) for the role. For more information in configuring the permissions to the Account ID, refer to the following AWS guide:
[How to use an external ID when granting access to your AWS resources to a third party](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_roles_create_for-user_externalid.html)
The newly created ARN is required in order to configure IAM role access in the Netography Fusion portal.
Once the ARN has been created, the remaining steps are to toggle the Authentication Type to **Role** in your AWS
S3 configuration settings, input the **AWS Account ID** grabbed earlier from your Netography account settings, and the supply the **ARN configured from AWS** as shown below:

# AWS VPC via Kinesis Setup
This document provides instructions for configuring the collection of AWS VPC Flow Logs with AWS Kinesis. Limitations/Notes This is for provisioning(create/delete) only. Edits must be done manually bu
This document provides instructions for configuring the collection of AWS VPC Flow Logs with AWS Kinesis.
## Limitations/Notes
* This is for provisioning(create/delete) only. Edits must be done manually but that’s largely limited by AWS
* This provisions everything required within a region.
* This must be run in every region that contains target VPCs
* Once the initial provisioning is done, adding additional VPCs, *within a region,* is trivial through the AWS GUI
## CloudFormation Steps
1. Setup supporting configuration with Cloudformation template
2. Create VPC Flow Logs that publishes to Kinesis
### Setup Cloudformation template
Setup supporting configuration with Cloudformation template.
1. In the AWS Console select Services and type cloudformation into the search bar
2. Click Create stack then With new resources(standard)
3. You will see the import overview, click next
4. Make sure Amazon S3 URL is checked and input the following URL then click next
5. Choose a stack name
6. Select the number of Kinesis shards 1 is defaultEach shard ingests upto 1 MiB/second and 1000 records/second and emits up to 2 MiB/second.
7. Select TargetVPC and click next
8. Add tags for the stack (optional) and click next
9. Review and check the "I acknowledge that AWS CloudFormation might create IAM resources with custom names."
10. Now click Create stack
11. Take note of the information on the Outputs tab\

### Create VPC Flow Logs
Create VPC Flow Logs that publishes to Kinesis
1. In the AWS Console select Services and type vpc into the search bar
2. Click VPC then select your VPC and click the Flow Logs tab

3. Then click create flow Log
| | |
| ---------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| Filter | All |
| Maximum aggregation interval | 1 minute |
| Destination | Send to CloudWatch Logs |
| Destination log group | Select the destination log group |
| IAM role | Hot |
| Access tier | Select the IAM role |
| Format | Custom format |
| Access tier | Hot |
| Log format | `${version} ${account-id} ${interface-id} ${srcaddr} ${dstaddr} ${srcport} ${dstport} ${protocol} ${packets} ${bytes} ${start} ${end} ${action} ${log-status} ${tcp-flags} ${type} ${pkt-dstaddr} ${pkt-srcaddr} ${instance-id} ${vpc-id} ${az-id} ${sublocation-id} ${sublocation-type} ${subnet-id}` |
1. Click create
## Netography Portal Steps
1. Navigate to "Traffic Sources"
2. Click "Add Traffic Source".
3. Click the "Show Advanced" button at the top of the page.
4. Click "AWS Kinesis".

### Configuration
The following fields are specific to the AWS Kinesis configuration.
| Field | Required | Description | Examples |
| -------- | -------- | --------------------------- | --------- |
| `Region` | yes | Location of the flow source | us-east-1 |
| `Stream` | yes | Kinesis data stream name | |
### Authentication
Netography Fusion can access your AWS account using one of two different methods:
1. IAM user via an Access Key ID & Secret Access Key
2. IAM Roles using a Custom Trust Policy created by Netography.
#### AWS Access Key
To configure access via Access Key/Secret, select the "Key/Secret" Authentication Type. The values for the ID and Secret are accessible in the AWS IAM console.

#### AWS IAM Roles
You can use an IAM role in Netography Fusion to access your Cloud Flow Logs for flow ingest or account data for the AWS Context Integration. To enable this, go to the portal and retrieve the **AWS Account ID** and **External ID** from your Account Settings. Navigate to the gear button on the top right to view your Account Settings to see the Overview tab as shown below:

In AWS, you will configure permissions using the Account ID grabbed from above to create the IAM Role. When configured, AWS creates the Amazon Resource Number (ARN) for the role. For more information in configuring the permissions to the Account ID, refer to the [external ID guide](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_roles_create_for-user_externalid.html).
{% hint style="warning" %}
**🚧The newly created ARN is required in order to configure IAM role access in the Netography Fusion portal.**
{% endhint %}
Once the ARN has been created, the remaining steps are to toggle the Authentication Type to **Role** in your AWS
S3 configuration settings, input the **AWS Account ID** grabbed earlier from your Netography account settings, and the supply the **ARN configured from AWS** as shown below:

# GCP VPC Flow Logs via Pub/Sub Setup
Vectra Fusion ingests VPC flow logs from Google Cloud Platform (GCP) via a GCP Pub/Sub subscription. The steps to integrate with GCP are: Enable VPC flow logs Create a Pub/Sub topic Create a Cloud
Vectra Fusion ingests VPC flow logs from Google Cloud Platform (GCP) via a GCP Pub/Sub subscription. The steps to integrate with GCP are:
1. Enable VPC flow logs
2. Create a Pub/Sub topic
3. Create a Cloud Logging Sink Pub/Sub for the topic
4. Create a Pub/Sub Pull Subscription to the topic
5. Add Vectra's GCP service account as a principal for the Pub/Sub subscription
6. In Fusion, Add GCP as a new flow source.
{% hint style="success" %}
**👍You can onboard an entire GCP organization or folder by following these steps one time**
You only need to create 1 GCP Pub/Sub topic, 1 GCP Cloud aggregated Logging Sink, 1 GCP Pub/Sub Subscription, and 1 Fusion GCP flow source to onboard GCP VPC flow logs to Fusion for as many VPC, subnets, projects, and sub-folders you have in your GCP organization or in a single folder in your GCP organization. If you need more granular control over what enabled VPC flow logs should be routed to Vectra, you can create 1 GCP Pub/Sub topic, 1 GCP Pub/Sub Subscription, 1 Fusion GCP flow source, and as many Cloud Logging Sinks as you need all routed to the one topic.
Additional information on using a aggregated logging sink and its benefits and limitations are described in step 3 below.
{% endhint %}
In addition to ingesting VPC flow logs, you may want to enrich them with context from GCP resources by adding the [GCP Context Integration](/enrich-traffic-with-context/configure-context-integrations/gcp)
{% hint style="info" %}
**🤖Using Terraform to automate onboarding**
Access Vectra's Terraform automation at our GitHub repo: . For access to the repo, email with your GitHub ID or with a request for access to the latest release package.
Vectra provides a Terraform project, `neto-onboarding,` that provides Vectra Fusion Cloud Onboarding Automation for AWS Organizations, Azure Tenants, and GCP Organizations.
This automation provides the following capabilties, which you can use in whole or part:
* Enables and configure AWS VPC flow logs, Azure VNet flow logs, and GCP VPC flow logs based on a simple policy and tags that defines which VPC/VNet are in scope.
* Deploy all the infrastructure required to integrate to Fusion across multiple accounts (AWS), subscriptions (Azure), and projects (GCP) in a single deployment
* Adds VPCs/VNets configured for flow logging to Vectra Fusion as traffic sources.
* Deploys a single AWS Lambda function, Azure Function, or Google Function that provides context enrichment across all the accounts/subscriptions/projects as an outbound push from your cloud to the Fusion API, eliminating the need to add context integrations from the Fusion portal, to grant Vectra permissions to directly enumerate resource properties, or to add individual context integrations in Fusion for each cloud account.
* Monitor for VPC/VNet changes and trigger enabling and configuring flow logs, and onboarding to Fusion new VPCs/VNets that are in scope, and offboarding VPCs/VNets that are removed or no longer in scope.
{% endhint %}
## Prerequisites
* If you have GCP organization policy constraints in place, you may be unable to perform these steps until you update the organizational policies. If you receive an error referring to an organization policy, update the policy and retry. Updating an organization policy requires the *Organization Policy Administrator* role ( `roles/orgpolicy.policyAdmin`).
* You need sufficient permissions in GCP to perform each step. The GCP documentation referenced in each step details the roles and permissions associated with that action.
## GCP Setup
### 1. Enable VPC flow logs
You can skip this step if you already have VPC flow logs enabled for the networks to monitor.
Follow these steps using the configuration settings below: [GCP: Enable VPC Flow Logs when you create a subnet](https://cloud.google.com/vpc/docs/using-flow-logs#network-management)
Additional instructions for enabling GCP VPC flow logs are available at [GCP: Use VPC Flow Logs](https://cloud.google.com/vpc/docs/using-flow-logs).
You can create filters in GCP to limit what traffic flow logs are generated for if you do not want to generate flow logs for all traffic. To only include traffic that is external to a VPC, use the filter expression `'!(has(src_vpc.vpc_name) && has(dest_vpc.vpc_name))'`.
#### Flow Log Configuration
| Field | Value |
| ---------------------- | ---------- |
| `Aggregation Interval` | `1 minute` |
| `Sample Rate` | `100` |
| `Include Metadata` | `Yes` |
#### Option 1. Enabling VPC Flow Logs at the Subnet Level
1. On the **Subnets in current project** tab, select one or more subnets and then click **Manage flow logs**.
2. In **Manage flow logs**, click **Add new configuration.** This will configure a new VPC flow log configuration.
3. Do one of the following:
1. If you selected one subnet, in the **Configurations — Subnets** section, click **Add a configuration**.
2. If you selected multiple subnets, in the **Configure VPC Flow Logs** section, select **Network Management API**.
4. For **Name**, enter a name for the new VPC Flow Logs configuration.
5. Change the **Aggregation Interval** to `1 minute`.
6. Optional: Adjust the **Description** and any of the settings in the **Advanced settings** section:
1. **Log filtering**: By default, **Keep only logs that match a filter** is deselected.
2. **Include metadata in the final log entries**: By default, **Metadata annotations** includes all fields.
3. **Secondary sampling rate**: `100%` means that all entries generated by the primary flow log sampling process are kept.
7. Click **Save**.
#### Option 2. Enabling VPC Flow Logs for VPC Networks
1. On the **Networks in current project** tab, select one or more networks and then click **Manage flow logs**.
2. In **Manage flow logs**, click **Add new configuration.** This will configure a new VPC flow log configuration.
3. In the popup window, under **Configurations - VPC networks** click on **Add a configuration**.
4. For **Name**, enter a name for the new VPC Flow Logs configuration.
5. Change the **Aggregation Interval** to `1 minute`.
6. Optional: Adjust the **Description** and any of the settings in the **Advanced settings** section:
1. **Log filtering**: By default, **Keep only logs that match a filter** is deselected.
2. **Include metadata in the final log entries**: By default, **Metadata annotations** includes all fields.
3. **Secondary sampling rate**: `100%` means that all entries generated by the primary flow log sampling process are kept.
7. Click **Save**.
#### Option 3. Configuring VPC Flow Logs at the Organization Level
Configurations created at an organizational level will apply to all VPCs within that organization.
1. Navigate to the [VPC Flow Logs](https://console.cloud.google.com/networking/vpc-flow-logs) configuration page.
2. Click **Add VPC Flow Logs configuration** and then click **Add a configuration for the organization**.
3. For **Name**, enter a name for the new VPC Flow Logs configuration.
4. Change the **Aggregation Interval** to `1 minute`.
5. Optional: Adjust the **Description** and any of the settings in the **Advanced settings** section:
6. Optional: Adjust the **Description** and any of the settings in the **Advanced settings** section:
1. **Log filtering**: By default, **Keep only logs that match a filter** is deselected.
2. **Include metadata in the final log entries**: By default, **Metadata annotations** includes all fields.
3. **Secondary sampling rate**: `100%` means that all entries generated by the primary flow log sampling process are kept.
7. Click **Save**.
### 2. Create a Cloud Pub/Sub topic
Create a Cloud Pub/Sub topic to publish flow logs to. If you are onboarding an individual GCP project, you can create the topic as part of creating the sink in step 3. If you are onboarding multiple projects at an organization or folder level, you can create a single topic in a designated project that you will use for centralized logging resources, and then use this one topic as the destination for a single aggregated sink, multiple individual project Cloud Logging Sinks, or a combination of the two.
To separately create the topic, follow these steps using the configuration settings below: [GCP: Create a Topic](https://cloud.google.com/pubsub/docs/create-topic#create_a_topic_2)
#### Pub/Sub Topic Configuration
| Field | Value |
| ---------------------------- | ---------------------------------------------- |
| `Topic ID` | Any value ( e.g. `neto-flowlogs-pubsub-topic`) |
| `Add a default subscription` | `No` |
| `Use a schema` | `No` |
| `Enable ingestion` | `No` |
| `Enable message retention` | `Yes`- `1 Day` |
Note: GCP charges for unacknowledged message retention over 1 day. In most circumstances, the messages will be acknowledged and removed from the topic in real-time, but retention will ensure there is no data lost unless the logs are not read in that time period. You can adjust the retention period based on your organization's requirements.
#### GCP Console Steps
1. Go to the **Pub/Sub Topics** page in the Google Cloud console.
2. Click **Create Topic**.
3. Fill out the form using the above configuration values, then click **Save**.
### 3. Create a Cloud Logging Sink Pub/Sub
Create a Cloud Logging Sink with a destination of Cloud Pub/Sub topic, using the topic you created in step 2 or creating the topic in the process.
{% hint style="info" %}
**ℹ️Using an aggregated sink for onboarding all projects in a GCP organization or folder**
If you are onboarding all the projects in a GCP organization, or all the projects that are children of a folder, you can use an aggregated sink to simplify the deployment. Using an aggregated sink lets you create 1 sink for a GCP organization or folder rather than 1 sink per project.
When you create an aggregated sink following these steps, all flow logs that are enabled in all child projects (including nested folders) will be routed to the aggregated sink. This will include any new projects, VPCs, or subnetworks that get added as children, and any new flow logs that are enabled will be automatically included.
An aggregated sink at the organization or folder level is ideal if you want to onboard all enabled flow logs within an organization or folder. If you have multiple folders to onboard (that are not nested within each other), you can create 1 aggregated sink for each folder, and route each of those sinks to the same Pub/Sub topic.
**Choosing the right design pattern for GCP logging sinks**
There is not one design for GCP logging sinks that is right for all organizations. Reach out to Vectra Support if you would like further guidance in this area. We would be happy to setup a design session to discuss your specific organization's use case and requirements and determine the best approach together, or review a proposed design before you implement it.
**Using exclusion filters to exclude project(s) or subnetwork(s)**
If you want to include all the enabled flow logs by default, but exclude specific projects or subnetworks (or any other criteria you can write a filter for in GCP), you can add up to 50 exclusion filters to a sink (and each filter can be 20k characters with logical operators).
To exclude a project: `logName:projects/PROJECT_ID`
To exclude a subnetwork: `resource.labels.subnetwork_name"=SUBNET_NAME"`
For more filter examples, see [GCP Logging > Sample queries](https://cloud.google.com/logging/docs/view/query-library).
**Excluding newly enabled flow logs**
If you are in an organization that uses VPC flow logs for multiple use cases, such as application troubleshooting directly in GCP, you may face the circumstance where an application team needs to enable VPC flow logs for a set of subnetworks that will generate a very high volume of logs, but you do not want to onboard these flow logs to Fusion. The default behavior of a sink is to include all these logs by default.
In this case, you will want to ensure any GCP administrator
that can enable flow logs is aware of what folders have sinks that will capture these logs by default, and that an exclusion filter needs to be added to the sink **BEFORE** these flow logs are enabled to avoid creating an undesired spike in flow log volume.
**Manually including newly enabled flow logs**
If you are onboarding a limited scope of projects or subnetworks to Fusion and want to maintain tighter control over what flow logs are onboarded, so that another GCP administrator can not inadvertantly start sending flow logs to Fusion by enabling flow logs in a subnetwork they control, you may want to instead use a sink design that only includes the enabled flow logs that you specify and not any onboard any newly enabled flow logs by default.
In this case, instead of using an exclusion filter for the sink, you can use the **Inclusion Filter** to specify only the specific projects, subnetworks, or other criteria you want to use. The same filters shown for exclusions above can be used in the inclusion filter to include only those matching the filter.
You can end up with a very long inclusion filter if you are individually including each project or subnetwork by name, and if you attempt to for hundreds of criteria you will reach the 20K character limit for a filter and no longer be able to add more. Use this pattern in cases where the filter you will write and its length will not approach that limit or too complex to manage.
**Additional steps when creating an aggregated sink**
To use an aggregated sink, you will need `Owner` access to the sink's destination, and to perform the following steps when creating the sink:
1. Select the organization or folder to onboard in the GCP project picker.
2. When creating the sink, select `Include logs ingested by this folder and all child resources`in the section **Choose logs to include in sink** (this option will not appear if you selected a project).
3. Add the sink's **writer identity** as a principal by using IAM, and then grant it the Pub/Sub Publisher role ( `roles/pubsub.publisher`). See [GCP: Route logs to supported destinations > Set destination permissions](https://cloud.google.com/logging/docs/export/configure_export_v2#dest-auth). *This step may not be required in your organization.*
For more information on aggregated sink configuration, see [GCP: Collate and route organization- and folder-level logs to supported destinations](https://cloud.google.com/logging/docs/export/aggregated_sinks#create_an_aggregated_sink)
{% endhint %}
Follow these steps using the configuration settings below: [GCP: Create a sink](https://cloud.google.com/logging/docs/export/configure_export_v2#creating_sink).
#### Cloud Logging Sink Configuration
| Field | Value |
| -------------------------------------- | ------------------------------------------------------------------------------- |
| `Sink name` | Any value ( e.g. `neto-flowlogs-sink`) |
| `Sink description` | Any value (e.g. Vectra Fusion flow log ingest) |
| `Sink destination service type` | `Cloud Pub/Sub topic` |
| `Sink destination Cloud Pub/Sub topic` | Create a topic or use topic created in previous step |
| `Inclusion filter` | `resource.type="gce_subnetwork" AND log_id("compute.googleapis.com/vpc_flows")` |
| Enable message retention | `Yes`- `1 Day` |
**Inclusion Filter**
The inclusion filter`resource.type="gce_subnetwork"` will include all VPC flow logs in the sink. You can add filters using inclusion or exclusion based on your desired configuration. For example, to only publish to the sink VPC flow logs that are ingress/exgress a VPC (excluding internal intra-VPC traffic), the inclusion filter would be:
`resource.type="gce_subnetwork"and NOT ( jsonPayload.src_vpc.vpc_name:_ AND jsonPayload.dest_vpc.vpc_name:_ )`
Adding this filter at the sink will still generate the VPC flow logs for intra-VPC traffic but will not deliver those logs to Fusion (this may be useful if you are using intra-VPC flow logs for other purposes). To filter which VPC flow logs are generated, set the filter in the VPC flow log configuration instead of at the sink (see [GCP: Filtering VPC flow logs](https://cloud.google.com/vpc/docs/flow-logs#filtering)).
#### GCP Console Steps
1. Go to the **Log Router** page in the Google Cloud console.
2. Select the project (or folder or organization if using an aggregated sink) to create the sink in.
3. Click **Create sink**.
4. Fill out the form using the above configuration values, then click **Save**
### 4. Create a Pub/Sub Pull Subscription to the topic
Follow these steps using the configuration settings below: [GCP: Create a pull subscription](https://cloud.google.com/pubsub/docs/create-subscription#create_a_pull_subscription).
#### Pub/Sub Subscription Configuration
| Field | Value |
| ---------------------------- | -------------------------------------------------------------------- |
| `Subscription ID` | Any value ( e.g. `neto-flowlogs-sub`) |
| `Cloud Pub/Sub Topic` | `Topic ID` from previous steps (if creating from Subscriptions page) |
| `Delivery Type` | `Pull` |
| `Message retention duration` | `1 Day` *(or based on your requirements)* |
| `Retry policy` | `Retry after exponential backoff delay` (Default min/max values) |
Default values for all other fields can be used.
#### GCP Console Steps
1. Go to the **Topics** page in the Google Cloud console.
2. Click **⋮** next to the topic you created in previous step.
3. From the context menu, select **Create Subscription**.
4. Fill out the form using the above configuration values, then click **Save**.
Note: Alternatively, you can create a subscription from the **Subscriptions** page by entering the `Topic ID` from the previous step.
### 5. Add Vectra's GCP service account as a principal to the Pub/Sub subscription
To grant Vectra access to read logs from the Pub/Sub subscription, add the Vectra GCP service account as a new principal in the subscription.
{% hint style="info" %}
**📘If you have a Domain Restricted Sharing Organizational Policy**
If your GCP organization has an Organizational Policy constraint for Domain Restricted Sharing `constraints/iam.allowedPolicyMemberDomains`, you must add a rule to that pollicy to allow Vectra's GCP customer ID `C04ddcbu8`before adding the principal to the Pub/Sub subscription.
**This constraint is the default setting for all GCP organizations created on or after May 3, 2024.**
If this policy restriction exists and you do not add the rule, you will receive the following error when you save the Pub/Sub Subscription:\
**IAM policy update failed** - The ‘Domain Restricted Sharing’ organization policy (`constraints/iam.allowedPolicyMemberDomains`) is enforced.
For detailed instructions and options for configuration, see [GCP: Restricting Domains](https://cloud.google.com/resource-manager/docs/organization-policy/restrictng-domains)
**Domain Restricted Sharing Configuration**
{% endhint %}
| Field | Value |
| -------------- | --------------------------------------------- |
| `Policy Value` | `sa-cloud@netography.iam.gserviceaccount.com` |
| `Policy Type` | `Pub/Sub Subscriber` |
| `Custom Value` | `C04ddcbu8` |
{% hint style="info" %}
**GCP Console Steps**
To update your Organizational Policy to allow you to grant Vectra's GCP service account access to the Pub/Sub subscription:
1. Go to the **Organization Policies** page in the Google Cloud console **IAM & Admin** section.
2. Next to where it says **Filter** above the list of policies, type **Domain restricted sharing**.
3. You should see 1 policy with that name in the list, with ID `constraints/iam.allowedPolicyMemberDomains`. Click **⋮** and Edit Policy.
4. Add a new rule (or add a value to an existing rule) for the policy under Rules using the above configuration values, then click **Set Policy**.
{% endhint %}
Follow these steps to add a principal to the subscription: [GCP: Access Control for Pub/Sub > Controlling access through the Google Cloud Console](https://cloud.google.com/pubsub/docs/access-control#console)
#### Pub/Sub Subscription Principal Configuration
| Field | Value |
| ----------- | --------------------------------------------- |
| `Principal` | `sa-cloud@netography.iam.gserviceaccount.com` |
| `Role` | `Pub/Sub Subscribe` |
#### GCP Console Steps
1. Go to the **Subscriptions** page in the Google Cloud console in the **Pub/Sub** section.
2. Select the subscription you created in the previous step to bring up the subscription info panel on right.
3. Select **Add Principal** in the info panel for the subscription.
4. Fill out the form using the above configuration values, then click **Save**.
## Vectra Fusion Setup
### 6. Add a new GCP flow source to Fusion
In the Fusion portal, click the gear icon to go to Settings, navigate to **Traffic Sources**, click **Add Traffic Source**, select **GCP**, and fill out the form using the configuration below.
#### GCP Flow Source Configuration
The following fields are specific to the GCP configuration.
| Field | Required | Description |
| ------------------- | -------- | -------------------------------------------------- |
| `Project ID` | yes | GCP Project ID containing the Pub/Sub subscription |
| `Subscription ID` | yes | GCP Pub/Sub Subscription ID |
| `Sample Percentage` | yes | GCP Flow Log Sampling Percentage |
The `Sample Percentage` field is only used for display purposes and does not need to be set to the same value as the value configured in GCP for the flow logs. If you are using multiple sampling percentages, you can use `100` as the value for this field.
# IBM Cloud VPC Flow Logs via Cloud Object Storage Setup
This document provides instructions for configuring the collection of IBM Cloud VPC Flow Logs with IBM Cloud Object Storage.Note: VPC Flow Logs are only available on VPC Infrastructure Gen 2 Console S
This document provides instructions for configuring the collection of IBM Cloud VPC Flow Logs with IBM Cloud Object Storage.Note: VPC Flow Logs are only available on VPC Infrastructure Gen 2
### Console Steps
#### Create Cloud Object Storage Service
1. First create the cloud object storage service.
2. Using the search bar type "cloud object storage" to be brought to the configuration page.

3. Select your desired storage plan, name your server, and select your resource group then click create.

#### Create Object Storage Bucket
1. From the Cloud Object Storage page click Buckets to create a storage bucket.

2. Choose a bucket name and add an expiration rule for as many days as you'd like to keep the raw logs.

#### Create Service credentials
1. Click service credentials on the Cloud Object Service page to create credentials Netography will use to access the flow logs.
2. Give it a name and use the reader role.

3. Click the chevron next to the key name as it will have the necessary information for the Netography Portal.

#### Grant Service Authorizations
1. From the main menu bar click Manage > Access (IAM)

2. The VPC Flow Logs need the ability to write to the Cloud Object Storage Bucket.
3. Click Authorizations in the left navigation.
4. Use Infrastructure Service for Source service.
5. This will then reveal the Resource Type drop down, select Flow Logs for VPC.
6. Then select Cloud Object Storage for Target service.
7. Select the Cloud Object Storage service we created earlier for the Service instance.
8. Select Write for the Service access.

#### Create Flow Logs
1. In the main search bar type 'flow logs' and click Flow Logs for VPC.

2. Provide a name for the flow log collector.
3. Select your resource group.
4. Attach it to the VPC
5. Select your VPC, Cloud Object Storage Service, and Bucket.
6. Click Create flow log

7. You should now see the flow log collector.
8. Click on the Object Storage Bucket to see the flow logs in the buck.
 
### Netography Portal Steps
Navigate to Traffic Sources, and click "Add Traffic Source", then select `IBM COS`

#### Configuration
The following fields are specific to the IBM COS configuration.
| Field | Required | Description | Examples |
| -------- | -------- | --------------------------- | -------- |
| `Region` | yes | Location of the flow source | us-east |
| `Bucket` | yes | The COS bucket name | |
| `Prefix` | | Optional folder prefix | |
#### Authentication
The following fields are necessary for the integration to authenticate with IBM.
| Field | Required | Description |
| --------------------- | -------- | ------------------------------------------------------------------------------------------------------------------------------ |
| `API Key` | yes | The API key that is associated for the Service ID |
| `Service Instance ID` | yes | Unique identifier for the instance of Object Storage the credential accesses. This is also referred to as a service credential |
# Oracle Cloud VCN Flow Logs via Cloud Object Storage Setup
Console Steps Create User Group Using the search bar type "identity" and click "Groups" under Services to be brought to the configuration page. Click "Create Group" Fill in the name and description. Y
### Console Steps
#### Create User Group
1. Using the search bar type "identity" and click "Groups" under Services to be brought to the configuration page.
2. Click "Create Group"
3. Fill in the name and description. You can optionally add your desired tags.\

#### Create Access Policy
1. Using the search bar type "identity" and click "Groups" under Services to be brought to the configuration page.
2. Click "Create Policy"
3. Fill in the name and description. You can optionally add your desired tags under advanced.
4. Choose the compartment to limit the policy to.
5. Next to Policy Builder click "Customize"
6. Fill in the following policies. Replace groupname with the group we created. Replace region with the region the object storage being used is in. Tenancy can be replaced with a stricter scope such as a compartment.
```
allow group to read object-family in tenancy
allow group to read virtual-network-family in tenancy
allow group to read instance-family in tenancy
allow service objectstorage- to manage object-family in tenancy
```

#### Create User
1. Using the search bar type "identity" and click "Users" under Services to be brought to the configuration page.
2. Click "Create User"
3. Fill in the name and description.
4. You can optionally add an email address and your desired tags under advanced.
5. Click on the user you just created and click "Add User to Group" then select the group we created. Click "Add"
6. In the User Information tab click "copy" next to "OCID". Make note of this as it will be used in the Netography portal.\

#### Create Flow Logs
You can enable flow logs *for a given subnet*, which means traffic is logged for all the existing and future VNICs in that subnet. Each flow log record contains information about traffic for a single VNIC. After flow logs are enabled for a subnet, a batch of flow logs for each VNIC is collected in one-minute capture windows. It takes under eight minutes to process a batch, after which the flow logs are available for viewing.
1. Using the search bar type "virtual" and click "Virtual Cloud Networks" under Services to be brought to the configuration page.
2. Select the subnet you wish to turn flow logs on.
3. Click the toggle under "Enable Log"
4. Select the proper compartment
5. Select your log group or click "Create New Group"
6. Enter the desired log name
7. Leave retention period default
8. Check "Enable Legacy Archival Logs"
9. Click "Enable Log"\

#### Create Service Connector
1. Go to the **Logging** section and select the **Service Connectors** option
2. Click **Create Service Connector**
3. Populate details for **Connector name** and the **description**.
4. Click **Create.**\
\
\

#### Setup Object Lifecycle
To reduce the amount of flow logs in object storage you can configure an object lifecycle to expire objects after a number of days.
1. In the bucket you just created click "Lifecycle Policy Rules"
2. Enter a name for your policy
3. Ensure "Objects" is the target.
4. Select "Delete" for Lifecycle Action
5. Enter your desired days after which the objects expire.
6. Ensure state is enabled\

#### Obtain Tenancy OCID
1. Click on your profile icon in the upper right.
2. Click on Tenancy.
3. Under Tenancy Information click copy next to OCID.\
\

### Netography Portal Steps
Navigate to Traffic Sources, and click "Add Traffic Source", then select `Oracle COS`

#### Configuration
The following fields are specific to the Oracle COS configuration.
| Field | Required | Description | Example |
| -------- | -------- | --------------------------- | ------------ |
| `Region` | yes | Location of the flow source | us-sanjose-1 |
| `Bucket` | yes | The COS bucket name | |
| `Prefix` | | Optional folder prefix | |
#### Authentication
The following fields are necessary for the integration to authenticate with Oracle COS.
| `Account Name` | yes | The account name to use for this stream |
| -------------- | --- | -------------------------------------------------------------------------------------------------------------------- |
| `User OCID` | yes | Oracle assigns each user a unique ID called an Oracle Cloud ID (OCID) |
| `Tenancy OCID` | yes | Every Oracle Cloud Infrastructure resource has an Oracle-assigned unique ID called an Oracle Cloud Identifier (OCID) |
To complete the authentication setup, you will need to obtain the public key and fingerprint that will be generated automatically after the form is submitted. Once the integration is created in the Netography Portal, return to edit the Flow Source that was just created.

Make note of the public key and fingerprint. This information will be used in the post configuration step within COS.

### Console Steps (Continued)
{% hint style="info" %}
**This step uses the public key generated after configuring the Cloud Provider in the Netography Portal.**
{% endhint %}
#### Add API Key to User
1. Click "API Keys" and Add Public Key

2. Select paste public keys and paste the public key.

3. You should now see a fingerprint and it should match the fingerprint for the public key.

# Ingest DNS Logs
See DNS in Fusion for more information about how to use DNS resolver logs in Fusion. If you are setting up AWS or GCP for the first time, the Quick Start Guides for AWS and GCP have end-to-end steps f
See [DNS in Fusion](/ingest-network-traffic-logs/dns-logs/dns-in-fusion-copy) for more information about how to use DNS resolver logs in Fusion.
If you are setting up AWS or GCP for the first time, the [Quick Start Guides](/) for AWS and GCP have end-to-end steps for configuring DNS resolver logs, along with flow logs and context enrichment.
### DNS Resolver Log Sources
#### AWS Route 53
[AWS Route 53 DNS Logs via S3 Setup (Console)](/ingest-network-traffic-logs/dns-logs/dns-source-aws)
#### GCP Cloud DNS
[GCP Cloud DNS Logs via Pub/Sub Setup](/ingest-network-traffic-logs/dns-logs/dns-source-gcp)
#### Cisco Umbrella
[Cisco Umbrella DNS Logs via S3 Setup (Console)](/ingest-network-traffic-logs/dns-logs/cisco-umbrella-dns-logs-via-s3-setup-console)
#### Infoblox NIOS
Infoblox NIOS support is in Early Access currently. Contact Netography Support for access to this capability.
### Configure internal domains in Traffic Classification
Once you have configured a traffic source for DNS in Fusion, you should also set the **Internal Domains** for your organization. This will mark DNS queries to internal domains as **internal** in Fusion.
In the Fusion Portal, go to **Settings > Traffic Classification**, and then select the **DNS** tab.
Add your internal domains to this page's **Internal Domains** section.
# Use DNS in Fusion
Recursive DNS request and response logs are a valuable data source for network forensics. Fusion supports DNS log ingestion from Amazon Web Services (AWS) Route 53 and Google Cloud Platform (GCP) . Su
Recursive DNS request and response logs are a valuable data source for network forensics.
Fusion supports DNS log ingestion from **Amazon Web Services (AWS) Route 53** and **Google Cloud Platform (GCP)**. Support for Infoblox NIOS, Cisco Umbrella, and Azure Firewall DNS Proxy are on the product roadmap - if you are using one of these and would like to ingest it, reach out to Support.
Combined with network flow metadata, Fusion becomes an even more robust system for network forensics, compromise detection, and network visibility.
By analyzing the DNS requests made in your network, you can use Fusion to:
* Reconstruct event timelines post-incident.
* Improve mean time to resolve events through enhanced DNS and Flow data visualization.
* Highlight patterns of communications with suspicious or malicious domains.
* Identify DNS patterns indicative of malware or command and control servers.
* Add DNS-specific fields in NQL for traffic forensic analysis.
* Use detection models based on DNS traffic.
* See dashboard visualizations and metrics for DNS activity in the network.
### Ingesting DNS Logs to Fusion
See [Ingesting DNS Logs to Fusion](/ingest-network-traffic-logs/dns-logs).
### Configure internal domains in Traffic Classification
See [Ingesting DNS Logs to Fusion](/ingest-network-traffic-logs/dns-logs)
### Using DNS in the Fusion Portal
#### Terminology: Flow, DNS, and Traffic
You may notice the terms **Flow**, **DNS**, and **Traffic** throughout the portal.
* **Flow** only relates to network flow records.
* **DNS** only relates to the DNS resolver records.
* **Traffic** is the term used for the combination of **Flow** and **DNS**.
#### Using DNS in the Global filter
Click the filter button (the rounded button in the top-left of Portal that says **Flow**, **Traffic**, **DNS**, **Events**, or **Blocks**). to change the filter to **DNS** or **Traffic**.
Changing the filter to **DNS** permits Fusion to perform operations related to DNS records.
Changing the filter to **Traffic** permits Fusion to perform operations related to DNS **and** Flow records.

#### Using DNS in Detection Models
The **Traffic Type** field is present when you create or edit a detection model. Selecting **DNS** lets you build DNS-based detections.

#### Using DNS in Events
When a Detection Model with **Traffic Type DNS** generates an event, the **traffic** column displays **DNS**.

#### Using DNS in Dashboards
A new system dashboard named **DNS Overview** is now available.
DNS can be used in individual Dashboard Widgets when you are creating or modifying a dashboard by selecting the category **DNS** or **Traffic**.
 
# AWS Route 53 DNS Logs via S3 Setup (Console)
If you have already configured your AWS account to ingest VPC flow logs to Fusion using an S3 bucket and IAM role, the additional steps required to ingest DNS resolver query logs are: Configure Resolv
If you have already configured your AWS account to ingest VPC flow logs to Fusion using an S3 bucket and IAM role, the additional steps required to ingest DNS resolver query logs are:
1. Configure Resolver Query Logging to an S3 bucket in AWS Route 53
2. Add a DNS AWS S3 traffic source in Fusion for each VPC configured to log resolver queries.
You must collect the information in the table below to add the traffic source to Fusion in step 2.
| Field | Description | Example |
| ------------------ | --------------------------------------------------- | ------------------------------------------------------- |
| VPC ID | VPC ID configured for resolver query logging | `vpc-04abc123000de4500` |
| Account ID | AWS Account ID | `123456789012` |
| Region | The region of the VPC | `us-east-1` |
| Bucket | The S3 bucket name | `bucket_name` |
| Bucket Region | The region of the S3 bucket | `us-east-1` |
| Prefix | Folder prefix | `dnslogs` |
| IAM Role ARN | The IAM role ARN used by Fusion to integrate to AWS | `arn:aws:iam::123456789012:role/NetographyRole` |
| SQS URL (optional) | Only needed if SQS has been configured | `https://sqs.us-east-1.amazonaws.com/123456789012/logq` |
### Configuring Resolver Query Logging in AWS to an S3 bucket
{% hint style="info" %}
**📘Choosing the S3 bucket to log to**
You can utilize the same S3 bucket you send VPC flow logs to for resolver query logs. Using the same S3 bucket simplifies configuration, as the existing IAM policy permissions for Fusion to read that bucket have already been configured.
To view the S3 bucket that is configured for an existing VPC configured in Fusion, go to:\
**SETTINGS > Traffic Sources**, click **…** next to the AWS flow source, and select **Edit**.
If you wish to create a new S3 bucket, ensure you update the Resource section of the IAM policy associated with the IAM role you created for Netography to include the new S3 bucket ARN.
{% endhint %}
1. Sign in to the AWS Management Console and open the Route 53 console at\
2. Expand the Route 53 console menu. Choose the three horizontal bars in the console's upper left corner.
3. Within the Resolver menu, choose **Query logging**.
4. In the Region selector, choose the AWS Region where you want to create the query logging configuration. This must be the same region where you created the VPCs for which you want to log DNS queries. If you have VPCs in multiple Regions, you must create one query logging configuration for each Region.
5. Choose **Configure query logging** and fill in the following:
1. Query logging configuration name - Enter a descriptive name for your query logging configuration.
2. Query logs destination - Select **S3 Bucket**
1. Choose the S3 bucket to log to.
2. If you are using the same S3 bucket as you are using for flow logs, you can separate DNS logs from VPC flow logs by adding to the end of the S3 bucket a folder name, such as **dnslogs**.\
**Make a note of the S3 bucket and prefix**
3. VPCs to log queries for - Check the check box for each VPC in the current Region that you want to log then choose **Choose**.\
**Make a note of the the VPC IDs of each VPC you chose.**
For additional details on configuring resolver query logging, see AWS documentation:
### Adding a DNS AWS S3 Traffic Source to Fusion
You must add a new DNS traffic source in Fusion for each VPC configured in the previous step.
1. In Fusion, Navigate to **Settings > Traffic Sources**
2. Click **ADD TRAFFIC SOURCE**
3. In the DNS section, click **AWS S3 VPC**
4. Complete the form with the information you collected in the previous step.
| Field | Required | Description | Examples |
| ------------- | -------- | ------------------------------------------------------------------------------------------- | ------------------------------------------------------- |
| VPC ID | yes | VPC ID of the source | vpc-04abc123000de4500 |
| Account ID | yes | Account ID of the flow source | 123456789012 |
| Region | yes | Location of the source | us-east-1 |
| Bucket | yes | The S3 bucket name | bucket\_name |
| Bucket Region | yes | The region of the S3 bucket | us-east-1 |
| Remove Log | no | Remove the log from the S3 bucket after processing | |
| Prefix | no | Folder prefix | dnslogs |
| SQS URL | no | If provided, SQS will notify Netography that a new object was written for immediate ingest. | |
5. In the **Authentication** section, select **Role** for **AWS Authentication Type** and enter the ARN for the IAM role you are using to integrate Fusion to AWS.
{% hint style="info" %}
**📘Fusion role permissions required to add a new DNS traffic source**
To add a new DNS traffic source, the user's Role in Fusion must have the**Cloud Providers > Manage** permission. This setting is found in **Settings > Roles > Setup**.
{% endhint %}
### Optional AWS Configuration Step: Adding an SNS Topic and SQS Queue
{% hint style="info" %}
**❓Should I skip this step?**
Fusion will poll the configured S3 bucket for new logs every minute. However, if you add a SNS topic and SQS queue for a VPC you configured in the previous step, Fusion will receive a notification from AWS when a new log is available and immediately trigger reading that log. This means that DNS resolver logs will be ingested up to 59 seconds faster (\~30 seconds on average) if you complete this step. The cost of this added efficiency is the additional configuration required for this step (AWS usage charges for SQS/SNS for this purpose are less than 1 cent per VPC per month).
You can safely skip this step and come back to it later if you decide it is important.
{% endhint %}
For each VPC you configured for resolver query logging:
1. Create a SNS topic
2. Create a SQS queue
3. Subscribe the SQS queue to the SNS topic
4. Add event notifications (destined for the SQS queue) in the S3 bucket
5. Add the SQS queue ARN to IAM permission policy attached to the Fusion IAM role.
#### 1. Create a SNS Topic
1. Sign in to the Amazon SNS console at:\
2. On the navigation panel, choose **Topics**.
3. On the Topics page, choose **Create topic**.
4. For Type, choose **Standard**.
5. Enter a Name for the topic (e.g. `fusion_dns_vpc-04abc123000de4500`).
6. Choose **Create topic**.
7. **Make a note of the topic ARN displayed.**
For additional details on creating a SNS topic, see AWS documentation:
#### 2. Create a SQS queue
1. Open the Amazon SQS console at:\
2. Choose **Create queue**.
3. For Type, use the default **Standard queue type**.
4. Enter a Name for your queue (e.g. `fusion_dns_vpc-04abc123000de4500`).
5. In the Configuration section, set the Message retention period to **1 day**.
6. In the Access Policy section, set the Method to **Advanced**, and paste the following JSON, updating the **aws:SourceArn** value from
`"arn:aws:s3:::"` to the S3 bucket ARN you are using.
{% tabs %}
{% tab title="JSON" %}
````
```json
{
"Version": "2012-10-17",
"Id": "PushMessageToSQSPolicy",
"Statement": [
{
"Sid": "allow-sns-to-send-message-to-sqs",
"Effect": "Allow",
"Principal": {
"AWS": "*"
},
"Action": "sqs:SendMessage",
"Resource": "*",
"Condition": {
"StringLike": {
"aws:SourceArn": "arn:aws:s3:::"
}
}
}
]
}
```
````
{% endtab %}
{% endtabs %}
7. Choose **Create queue**. Amazon SQS creates the queue and displays the queue's Details page.
For additional details on creating a SQS queue, see AWS documentation:
#### 3. Subscribe SQS Queue to SNS Topic
1. After creating the queue, you will see the queue's Details page. Under the SNS Subscriptions Tab, select the **Subscribe to Amazon SNS Topic** button.
2. Choose **Enter Amazon SNS topic ARN** and then enter the SNS topic ARN you noted in the previous step.
3. Choose **Save**.
4. **Make a note of your SQS URL and SQS ARN.**
#### 4. Add event notifications (destined for the SQS queue) in the S3 bucket
1. In the AWS console, navigate to **S3**, select your S3 bucket, and click the **Properties** tab.
2. In the **Event Notifications** section, click **Create event notification**.
3. Enter a name for the notification (e.g. `fusion_dns_notification_vpc-04abc123000de4500`).
4. The **prefix** field needs to be set to the path to which the resolver logs for the VPC are being written. This is *NOT* the same prefix as you set when first configuring the DNS resolver query logs for the VPC (but it starts with that if you set it).
If you set a prefix when configuring the DNS resolver query logs for the VPC to `dnslogs`, this path will be: `dnslogs/AWSLogs/ACCOUNTID/vpcdnsquerylogs/VPCID`. For example, if the query log prefix was set to `dnslogs`, AWS account ID is `1234567`, and the VPC ID is `vpc-987654321`, the prefix field should be set to: `dnslogs/AWSLogs/1234567/vpcdnsquerylogs/vpc-987654321`.
If you did not set a prefix, this path will be: `AWSLogs/ACCOUNTID/vpcdnsquerylogs/VPCID`. For example, if the AWS account ID is `1234567`, and the VPC ID is `vpc-987654321`, the prefix field should be set to: `AWSLogs/1234567/vpcdnsquerylogs/vpc-987654321`.
5. In the **Event Types** section, check **All objects create events**.
6. In the **Destination** section, select **SQS Queue**.
7. Enter the **SQS Queue ARN**
8. Click **Save**.
#### 5. Add SQS ARN to IAM permission policy attached to the Fusion IAM role
To integrate with AWS, Fusion is configured with an IAM role with a permission policy attached. You must add each SQS ARN you created in the previous steps to the **Resource** section of this permission policy so that Fusion can receive notifications that new logs are available to ingest.
If you are creating multiple SQS queues, you can collect all the SQS ARN you created in the previous steps and add them to the permission policy in one final step.
{% hint style="info" %}
**📘Identifying the right IAM permission policy to update**
The IAM policy name is`NetographyPolicy`in Fusion's default CloudFormation, but if it was created with the AWS Console or a non-default name is used, you will need to find the right policy. If you have a small AWS deployment, searching for `Netography` or `Fusion` may be a quick way to find it.
If you do not know the policy name, you can identify it by:
1. In Fusion, navigate to **Settings > Traffic Sources**, click **…** next to any AWS flow source using this role, and select **Edit**. Make a note of the **AWS ARN** in the **Authentication** section of this page.
2. In the AWS Console, under **Services** go to **IAM**, select **Roles** from the menu, and then search for the last section of the ARN (e.g. if the ARN is `arn:aws:iam::1234567890:role/NetographyFusionRole`, search for `NetographyFusionRole`).
3. Select the role for the ARN to bring up the role details page. This page will contain the name of the permissions policy associated with this role. Select the permission policy.
{% endhint %}
4. Sign in to the AWS Management Console and open the IAM console at:\
5. In the navigation pane, choose **Policies**.
6. In the list of policies, choose the policy name associated with the Netography Fusion IAM role (see the call-out above if you do not know what this is).
7. Choose the **Permissions tab**, and then choose **Edit**.
8. Choose the **JSON option** to modify your policy.
9. In the **Resource** section of the JSON, add the SQS ARNs that you created in the previous steps.
10. Choose **Save changes** to save your work, setting it as the new default policy version.
For additional details on updating the permission policy, see AWS documentation:
# Cisco Umbrella DNS Logs via S3 Setup (Console)
If you have already configured your Cisco Umbrella DNS Logs be stored in an AWS S3 bucket these steps can have them ingested into Fusion: Enable Cisco Umbrella DNS Log Export to S3: Configure Cisco Um
If you have already configured your Cisco Umbrella DNS Logs be stored in an AWS S3 bucket these steps can have them ingested into Fusion:
1. Enable Cisco Umbrella DNS Log Export to S3: Configure Cisco Umbrella to export DNS logs to an AWS S3 bucket.
2. Cisco Umbrella DNS Query Log Source in Fusion: Add a Cisco Umbrella DNS traffic source in Fusion for each log source.
You will need the following information to configure Fusion:
| Field | Description | Example |
| ------------------ | --------------------------------------------------- | ------------------------------------------------------- |
| Region (optional) | The region of the log source | `us-east-1` |
| Bucket | The S3 bucket name | `bucket_name` |
| Bucket Region | The region of the S3 bucket | `us-east-1` |
| Prefix | Folder prefix | `dnslogs` |
| IAM Role ARN | The IAM role ARN used by Fusion to integrate to AWS | `arn:aws:iam::123456789012:role/NetographyRole` |
| SQS URL (optional) | Only needed if SQS has been configured | `https://sqs.us-east-1.amazonaws.com/123456789012/logq` |
### Step 1: Enable Cisco Umbrella DNS Log Export to S3
1. Log in to the Cisco Umbrella Dashboard.
2. Navigate to Admin > Log Management.
3. Under Log Export Settings, select Amazon S3 as the log destination.
4. Configure the following:
* Bucket Name: The S3 bucket where logs will be exported. If you already have a bucket used for other logs, you can reuse it.
* Region: The AWS region of the S3 bucket.
* Prefix: Specify a prefix to separate Cisco Umbrella logs from other logs (e.g., cisco-umbrella-logs).
5. Save the configuration and confirm that Cisco Umbrella is exporting logs to the bucket.
### Step 2: Add a Cisco Umbrella DNS Traffic Source in Fusion
1. In Fusion, Navigate to **Settings > Traffic Sources**
2. Click **ADD TRAFFIC SOURCE**
3. In the DNS section, click **Cisco Umbrella**
4. Complete the form with the information you collected in the previous step.
| Field | Required | Description | Examples |
| ---------------- | -------- | ------------------------------------------------------------------------------------------ | ------------------------------------------------------- |
| Name | yes | Name of the traffic source | my-query-logs |
| S3 Bucket Name | yes | S3 bucket where Cisco Umbrella logs are stored | umbrella-dns-logs |
| S3 Bucket Region | yes | AWS region of the S3 bucket | us-east-1 |
| Prefix | no | Folder prefix for Cisco Umbrella logs | cisco-umbrella-logs |
| SQS URL | no | If provided, SQS will notify Netography that a new object was written for immediate ingest | |
5. In the **Authentication** section, select **Role** for **AWS Authentication Type** and enter the ARN for the IAM role you are using to integrate Fusion to AWS.
{% hint style="info" %}
**📘Fusion role permissions required to add a new DNS traffic source**
To add a new DNS traffic source, the user's Role in Fusion must have the **Cloud Providers > Manage** permission. This setting is found in **Settings > Roles > Setup**.
{% endhint %}
### Optional AWS Configuration Step: Adding an SNS Topic and SQS Queue
{% hint style="info" %}
**❓Should I skip this step?**
Fusion will poll the configured S3 bucket for new logs every minute. However, if you add a SNS topic and SQS queue for a VPC you configured in the previous step, Fusion will receive a notification from AWS when a new log is available and immediately trigger reading that log. This means that DNS resolver logs will be ingested up to 59 seconds faster (\~30 seconds on average) if you complete this step. The cost of this added efficiency is the additional configuration required for this step (AWS usage charges for SQS/SNS for this purpose are less than 1 cent per log source per month).
You can safely skip this step and come back to it later if you decide it is important.
{% endhint %}
For each traffic source you configured for resolver query logging:
1. Create a SNS topic
2. Create a SQS queue
3. Subscribe the SQS queue to the SNS topic
4. Add event notifications (destined for the SQS queue) in the S3 bucket
5. Add the SQS queue ARN to IAM permission policy attached to the Fusion IAM role.
#### 1. Create a SNS Topic
1. Sign in to the Amazon SNS console at:\
2. On the navigation panel, choose **Topics**.
3. On the Topics page, choose **Create topic**.
4. For Type, choose **Standard**.
5. Enter a Name for the topic (e.g. `fusion_umbrella-dns-logs_1234`).
6. Choose **Create topic**.
7. **Make a note of the topic ARN displayed.**
For additional details on creating a SNS topic, see AWS documentation:
#### 2. Create a SQS queue
1. Open the Amazon SQS console at:\
2. Choose **Create queue**.
3. For Type, use the default **Standard queue type**.
4. Enter a Name for your queue (e.g. `fusion_umbrella-dns-logs_1234`).
5. In the Configuration section, set the Message retention period to **1 day**.
6. In the Access Policy section, set the Method to **Advanced**, and paste the following JSON, updating the **aws:SourceArn** value from
`"arn:aws:s3:::"` to the S3 bucket ARN you are using.
{% tabs %}
{% tab title="JSON" %}
````
```json
{
"Version": "2012-10-17",
"Id": "PushMessageToSQSPolicy",
"Statement": [
{
"Sid": "allow-sns-to-send-message-to-sqs",
"Effect": "Allow",
"Principal": {
"AWS": "*"
},
"Action": "sqs:SendMessage",
"Resource": "*",
"Condition": {
"StringLike": {
"aws:SourceArn": "arn:aws:s3:::"
}
}
}
]
}
```
````
{% endtab %}
{% endtabs %}
7. Choose **Create queue**. Amazon SQS creates the queue and displays the queue's Details page.
For additional details on creating a SQS queue, see AWS documentation:
#### 3. Subscribe SQS Queue to SNS Topic
1. After creating the queue, you will see the queue's Details page. Under the SNS Subscriptions Tab, select the **Subscribe to Amazon SNS Topic** button.
2. Choose **Enter Amazon SNS topic ARN** and then enter the SNS topic ARN you noted in the previous step.
3. Choose **Save**.
4. **Make a note of your SQS URL and SQS ARN.**
#### 4. Add event notifications (destined for the SQS queue) in the S3 bucket
1. In the AWS console, navigate to **S3**, select your S3 bucket, and click the **Properties** tab.
2. In the **Event Notifications** section, click **Create event notification**.
3. Enter a name for the notification (e.g. `fusion_umbrella-dns-notification_1234`).
4. The **prefix** field needs to be set to the path to which the resolver logs for the VPC are being written. This is *NOT* the same prefix as you set when first configuring the DNS resolver query logs for the VPC (but it starts with that if you set it).
If you set a prefix when configuring the DNS resolver query logs for the traffic source to `dnslogs`, this path will be: `dnslogs/`.
If you did not set a prefix, this path will be: `/`.
5. In the **Event Types** section, check **All objects create events**.
6. In the **Destination** section, select **SQS Queue**.
7. Enter the **SQS Queue ARN**
8. Click **Save**.
#### 5. Add SQS ARN to IAM permission policy attached to the Fusion IAM role
To integrate with AWS, Fusion is configured with an IAM role with a permission policy attached. You must add each SQS ARN you created in the previous steps to the **Resource** section of this permission policy so that Fusion can receive notifications that new logs are available to ingest.
If you are creating multiple SQS queues, you can collect all the SQS ARN you created in the previous steps and add them to the permission policy in one final step.
{% hint style="info" %}
**📘Identifying the right IAM permission policy to update**
The IAM policy name is`NetographyPolicy`in Fusion's default CloudFormation, but if it was created with the AWS Console or a non-default name is used, you will need to find the right policy. If you have a small AWS deployment, searching for `Netography` or `Fusion` may be a quick way to find it.
If you do not know the policy name, you can identify it by:
1. In Fusion, navigate to **Settings > Traffic Sources**, click **…** next to any AWS flow source using this role, and select **Edit**. Make a note of the **AWS ARN** in the **Authentication** section of this page.
2. In the AWS Console, under **Services** go to **IAM**, select **Roles** from the menu, and then search for the last section of the ARN (e.g. if the ARN is `arn:aws:iam::1234567890:role/NetographyFusionRole`, search for `NetographyFusionRole`).
3. Select the role for the ARN to bring up the role details page. This page will contain the name of the permissions policy associated with this role. Select the permission policy.
{% endhint %}
4. Sign in to the AWS Management Console and open the IAM console at:\
5. In the navigation pane, choose **Policies**.
6. In the list of policies, choose the policy name associated with the Netography Fusion IAM role (see the call-out above if you do not know what this is).
7. Choose the **Permissions tab**, and then choose **Edit**.
8. Choose the **JSON option** to modify your policy.
9. In the **Resource** section of the JSON, add the SQS ARNs that you created in the previous steps.
10. Choose **Save changes** to save your work, setting it as the new default policy version.
For additional details on updating the permission policy, see AWS documentation:
# GCP Cloud DNS Logs via Pub/Sub Setup
Vectra Fusion ingests Google Cloud Platform (GCP) Cloud DNS logs via a GCP Pub/Sub subscription. The steps to integrate with GCP are: Prerequisite: If you have a Domain Restricted Sharing Organiza
Vectra Fusion ingests Google Cloud Platform (GCP) Cloud DNS logs via a GCP Pub/Sub subscription. The steps to integrate with GCP are:
1. Prerequisite: If you have a Domain Restricted Sharing Organization Policy, add Vectra to it
2. Enable Cloud DNS logs
3. Create a Pub/Sub topic
4. Create a Cloud Logging Sink Pub/Sub for the topic
5. Create a Pub/Sub Pull Subscription to the topic
6. Add Vectra's GCP service account as a principal for the Pub/Sub subscription
7. In Fusion, Add GCP as a new DNS traffic source
{% hint style="info" %}
**ℹ️Cloud DNS and VPC Flow Logs use a separate Pub/Sub Subscription in Fusion**
Fusion reads GCP Cloud DNS logs from a separate Pub/Sub Subscription than GCP VPC flow logs. If you have already setup GCP VPC flow logs, the easiest option is to follow the instructions below to create a new Cloud Logging Sink, Pub/Sub Topic, and Pub/Sub Pull Subscription for Cloud DNS.
It is possible to create a combined Cloud Logging Sink and Pub/Sub Topic for both VPC flow logs and Cloud DNS logs, and then use a Pub/Sub Subscription filter to deliver only logs to the correct destination, but this design incurs Pub/Sub message delivery fees for all the messages filtered out of each subscription, so it is not recommended.
{% endhint %}
{% hint style="success" %}
**👍You can onboard DNS logs for an entire GCP organization or folder by following these steps one time**
You only need to create 1 GCP Pub/Sub topic, 1 GCP Cloud aggregated Logging Sink, 1 GCP Pub/Sub Subscription, and 1 Fusion GCP DNS traffic source to onboard GCP Cloud DNS logs to Fusion across networks, projects, and folders. If you need more granular control over which Cloud DNS logs should be routed to Vectra, create 1 GCP Pub/Sub topic, 1 GCP Pub/Sub Subscription, and 1 Fusion GCP DNS traffic source. You can then make as many Cloud Logging Sinks as you need to route all the Cloud DNS logs to the one topic you created.
{% endhint %}
In addition to ingesting Cloud DNS logs, you may want to also ingest VPC flow logs, and enrich IP addresses in Fusion from GCP with context with the [GCP Context Integration](/enrich-traffic-with-context/configure-context-integrations/gcp).
### Prerequisites
### If you have a Domain Restricted Sharing Organization Policy
If your GCP organization has an Organization Policy constraint for Domain Restricted Sharing `constraints/iam.allowedPolicyMemberDomains`, you must add a rule to that policy to allow Vectra's GCP customer ID `C04ddcbu8`before adding the principal to the Pub/Sub subscription.
**If you have GCP VPC flow logs in Fusion and use the same project for the Pub/Sub topic and subscription, you already have this rule if it is needed.**
**This constraint is the default setting for all GCP organizations created on or after May 3, 2024.**
If this policy restriction exists and you do not add the rule, you will receive the following error when you save the Pub/Sub Subscription:\
**IAM policy update failed** - The ‘Domain Restricted Sharing’ organization policy (`constraints/iam.allowedPolicyMemberDomains`) is enforced.
For detailed instructions and options for configuration, see [target="\_blank">GCP: Restricting Domains](https://cloud.google.com/resource-manager/docs/organization-policy/restricting-domains)
#### Domain Restricted Sharing Configuration
| Field | Value |
| -------------- | ----------- |
| `Custom Value` | `C04ddcbu8` |
#### GCP Console Steps
You must be an [Organization Policy Administrator (roles/orgpolicy.policyAdmin)](https://cloud.google.com/resource-manager/docs/access-control-org#orgpolicy.policyAdmin) to perform these steps. The Organization Administrator role does NOT contain these permissions.
To update your Organization Policy to allow you to grant Vectra's GCP service account access to the Pub/Sub subscription:
1. Go to the **Organization Policies** page in the Google Cloud console **IAM & Admin** section.
2. From the project picker (the box directly to the right of the Google Cloud logo at the top of your GCP console), select your GCP organization (you can choose the project you will create the Pub/Sub subscription if you prefer a more granular policy).
3. Next to where it says **Filter** above the list of policies, type **Domain restricted sharing**.
4. You should see 1 policy with that name in the list, with ID `constraints/iam.allowedPolicyMemberDomains`. Click **⋮** and select **Edit Policy**.
5. Under **Policy source**, select the **Override parent's policy** button.
6. Under **Policy enforcement**, select **Merge with parent**.\
6a. Under **Rules**, if you see an existing rule with a **⌄**, follow this step: click the **⌄**. It will open a box that says **Edit Rule**. In that box, select the **ADD VALUE** button. It will create a new empty box above the button. In that box enter `C04ddcbu8`.\
6b. Under **Rules**, if you see a warning that *At least one rule is required in organization policies.*, click the **ADD A RULE** button below it. It will open a **New Rule** box. In the **Policy values** drop-down, select **Custom**. In the **Policy type** drop-down, select **Allow**. In the empty box under **Custom values**, enter `C04ddcbu8`.
7. Select the **Set Policy** button at bottom of the page.
## GCP Setup Steps
### 1. Enable Cloud DNS Logs
You can skip this step if Cloud DNS logs are already enabled for VPC networks and public zones you want to monitor.
Follow these steps to enable Cloud DNS logs: [GCP > Cloud DNS > Use logging and monitoring](https://cloud.google.com/dns/docs/monitoring).
### 2. Create a Cloud Pub/Sub topic
Create a Cloud Pub/Sub topic to publish Cloud DNS logs to. If you are onboarding an individual GCP project, you can create the topic as part of creating the sink in step 3. If you are onboarding multiple projects at an organization or folder level, you can create a single topic in a designated project that you will use for centralized logging resources, and then use this one topic as the destination for a single aggregated sink, multiple individual project Cloud Logging Sinks, or a combination of the two.
To separately create the topic, follow these steps using the configuration settings below: [GCP: Create a Topic](https://cloud.google.com/pubsub/docs/create-topic#create_a_topic_2)
#### Pub/Sub Topic Configuration
| Field | Value |
| ---------------------------- | --------------------------------------------- |
| `Topic ID` | Any value ( e.g. `neto-dnslogs-pubsub-topic`) |
| `Add a default subscription` | `No` |
| `Use a schema` | `No` |
| `Enable ingestion` | `No` |
| `Enable message retention` | `Yes`- `1 Day` |
Note: GCP charges for unacknowledged message retention over one day. In most circumstances, the messages will be acknowledged and removed from the topic in real time, but retention will ensure no data is lost unless the logs are not read in that period. You can adjust the retention period based on your organization's requirements.
#### GCP Console Steps
1. Go to the **Pub/Sub Topics** page in the Google Cloud console.
2. Click **Create Topic**.
3. Fill out the form using the above configuration values, then click **Save**.
### 3. Create a Cloud Logging Sink Pub/Sub
Create a Cloud Logging Sink with a destination of Cloud Pub/Sub topic, using the topic you created in step 2 or creating the topic in the process.
{% hint style="info" %}
**ℹ️Using an aggregated sink for onboarding all projects in a GCP organization or folder**
If you are onboarding all the projects in a GCP organization, or all the projects that are children of a folder, you can use an aggregated sink to simplify the deployment. Using an aggregated sink lets you create 1 sink for a GCP organization or folder rather than 1 sink per project.
When you create an aggregated sink following these steps, all logs that are enabled in all child projects (including nested folders) will be routed to the aggregated sink. This will include any new projects that get added as children and any new enabled logs will be automatically included.
An aggregated sink at the organization or folder level is ideal for onboarding all enabled logs within an organization or folder. If you have multiple folders to onboard (not nested within each other), you can create one aggregated sink for each folder and route each of those sinks to the same Pub/Sub topic.
**Choosing the correct design pattern for GCP logging sinks**
There is not one design for GCP logging sinks that is right for all organizations. Contact Vectra Support if you want further guidance in this area. We would be happy to set up a design session to discuss your specific organization's use case and requirements and determine the best approach together, or we could review a proposed design before you implement it.
**Using exclusion filters to exclude project(s) or subnetwork(s)**
If you want to include all the enabled flow logs by default but exclude specific projects or subnetworks (or any other criteria you can write a filter for in GCP), you can add up to 50 exclusion filters to a sink (and each filter can be 20k characters with logical operators).
To exclude a project: `logName:projects/PROJECT_ID`
For more filter examples, see [GCP Logging > Sample queries](https://cloud.google.com/logging/docs/view/query-library).
**Additional steps when creating an aggregated sink**
To use an aggregated sink, you will need `Owner` access to the sink's destination, and to perform the following steps when creating the sink:
1. Select the organization or folder to onboard in the GCP project picker.
2. When creating the sink, select `Include logs ingested by this folder and all child resources` in the section **Choose logs to include in sink** (this option will not appear if you selected a project).
3. Add the sink's **writer identity** as a principal by using IAM, and then grant it the Pub/Sub Publisher role ( `roles/pubsub.publisher`). See [GCP: Route logs to supported destinations > Set destination permissions](https://cloud.google.com/logging/docs/export/configure_export_v2#dest-auth). *This step may not be required in your organization.*
For more information on aggregated sink configuration, see [GCP: Collate and route organization- and folder-level logs to supported destinations](https://cloud.google.com/logging/docs/export/aggregated_sinks#create_an_aggregated_sink)
{% endhint %}
Follow these steps using the configuration settings below: [GCP: Create a sink](https://cloud.google.com/logging/docs/export/configure_export_v2#creating_sink).
#### Cloud Logging Sink Configuration
| Field | Value |
| -------------------------------------- | ---------------------------------------------------- |
| `Sink name` | Any value ( e.g. `neto-dnslogs-sink`) |
| `Sink description` | Any value (e.g. Vectra Fusion DNS log ingest) |
| `Sink destination service type` | `Cloud Pub/Sub topic` |
| `Sink destination Cloud Pub/Sub topic` | Create a topic or use topic created in previous step |
| `Inclusion filter` | `resource.type="dns_query"` |
| Enable message retention | `Yes`- `1 Day` |
**Inclusion Filter**
The inclusion filter `resource.type="dns_query"` will include all Cloud DNS logs in the sink. You can add filters using inclusion or exclusion based on your desired configuration.
#### GCP Console Steps
1. Go to the **Log Router** page in the Google Cloud console.
2. Select the project (or folder or organization if using an aggregated sink) to create the sink in.
3. Click **Create sink**.
4. Fill out the form using the above configuration values, then click **Save**
### 4. Create a Pub/Sub Pull Subscription to the topic
Follow these steps using the configuration settings below: [GCP: Create a pull subscription](https://cloud.google.com/pubsub/docs/create-subscription#create_a_pull_subscription).
#### Pub/Sub Subscription Configuration
| Field | Value |
| ---------------------------- | -------------------------------------------------------------------- |
| `Subscription ID` | Any value ( e.g. `neto-dnslogs-sub`) |
| `Cloud Pub/Sub Topic` | `Topic ID` from previous steps (if creating from Subscriptions page) |
| `Delivery Type` | `Pull` |
| `Message retention duration` | `1 Day` *(or based on your requirements)* |
| `Retry policy` | `Retry after exponential backoff delay` (Default min/max values) |
Default values for all other fields can be used.
#### GCP Console Steps
1. Go to the **Topics** page in the Google Cloud console.
2. Click **⋮** next to the topic you created in previous step.
3. From the context menu, select **Create Subscription**.
4. Fill out the form using the above configuration values, then click **Save**.
Note: Alternatively, you can create a subscription from the **Subscriptions** page by entering the `Topic ID` from the previous step.
### 5. Add Vectra's GCP service account as a principal to the Pub/Sub subscription
To grant Vectra access to read logs from the Pub/Sub subscription, add the Vectra GCP service account as a new principal in the subscription.
Follow these steps to add a principal to the subscription: [GCP: Access Control for Pub/Sub > Controlling access through the Google Cloud Console](https://cloud.google.com/pubsub/docs/access-control#console)
#### Pub/Sub Subscription Principal Configuration
| Field | Value |
| ----------- | --------------------------------------------- |
| `Principal` | `sa-cloud@netography.iam.gserviceaccount.com` |
| `Role` | `Pub/Sub Subscriber` |
#### GCP Console Steps
1. Go to the **Subscriptions** page in the Google Cloud console in the **Pub/Sub** section.
2. Select the subscription you created in the previous step to bring up the subscription info panel on right.
3. Select **Add Principal** in the info panel for the subscription.
4. Fill out the form using the above configuration values, then click **Save**.
## Vectra Fusion Setup
### 6. Add a new GCP DNS traffic source to Fusion
In the Fusion portal, click the gear icon to go to Settings, navigate to **Traffic Sources**, click **Add Traffic Source**, and under the **DNS** section, select **GCP**, and fill out the form using the configuration below.
#### GCP DNS Traffic Source Configuration
The following fields are specific to the GCP configuration.
| Field | Required | Description |
| ----------------- | -------- | ----------------------------------------------------- |
| `Project ID` | yes | GCP Project ID containing the Pub/Sub subscription |
| `Subscription ID` | yes | GCP Pub/Sub Subscription ID (e.g. `neto-dnslogs-sub`) |
Finding the `Subscription ID`:
* *Subscription ID* is the name you gave the subscription in the previous step.
* It is listed in Pub/Sub subscriptions in the GCP console in the table column `Subscription ID`.
* If you select a subscription by clicking the ID on that page, the Subscription detail page has the subscription ID directly below the Google Cloud logo (between the **←** and **Edit** buttons).
* The subscription ID is the part of the subscription name after the last / (eg. if subscription name is `projects/yourproject/subscriptions/neto-dnslogs-sub` then subscription ID is `neto-dnslogs-sub`.
# Infoblox NIOS DNS Logs via NetoDNS syslog
Vectra Fusion ingests Infoblox NIOS DNS logs via `netodns`, a software component from Vectra that you deploy and operates as a syslog listener in your local environment. You configure Infoblox NIOS to send query logs via syslog to this component, which then utilizes the Vectra Fusion API to deliver the logs securely to Fusion.
### Step 1. Deploy NetoDNS
First, you must deploy `netodns` to a system in your environment. If you have deployed the NetoFlow Collector, deployment and configuration follow similar steps.
* `netodns` listens on TCP port 514 (syslog), and needs network access to allow an inbound connection to this port from your Infoblox NIOS system that will be sending syslog output.
* You should restrict network access to `netodns` to only the Infoblox NIOS IP(s) to prevent other systems from also sending syslog to this device.
### Step 2. Infoblox NIOS Configuration
> ℹ️ Impact of enabling query logging on Infoblox NIOS
>
> Enabling `queries` and `responses` logging in Infoblox will have some impact on NIOS system performance, the extent to which is highly dependent on your configuration, system specs, and volume.
>
> If you have a large Infoblox Grid deployment, it is recommended you incrementally enable syslog on members of the grid and monitor the Infoblox system utilization to ensure it has adequate system resources with this additional logging enabled.
>
> If you have scaling issues deploying this configuration, contact Vectra Support to discuss. Vectra chose syslog as the most real-time and compatible method for log ingest across Infoblox NIOS deployments and versions, but there are alternative methods that may be supported in the future by Fusion.
Configure Infoblox NIOS to send `queries` and `responses` via syslog (TCP/514) to `netodns`. Consult Infoblox documentation for your specific product and version for the updated configuration steps for doing so.
See:
#### Configuring Syslog in Infoblox NIOS
To configure a NIOS appliance to send syslog to `netodns`, complete the following:
1. From the **Grid** tab, select the \*\*Grid Manager \*\*tab -> **Members** tab, and then click \*\*Grid Properties \*\*-> \*\*Edit \*\*from the Toolbar.
2. In the *Grid Properties* editor, select the\*\* Monitoring\*\* tab, and then configure syslog output, using the following settings.
| Setting | Value |
| ------------------------------ | ------------------------------------------------- |
| Log to External Syslog Servers | Enabled |
| Address | IP/FQDN of `netodns` deployed in your environment |
| Transport | TCP |
| Source | Any |
| Node ID | LAN |
| Port | 514 |
| Severity | Info |
| Logging Category | DNS Logging Categories:`queries` `responses` |
### Vectra Fusion setup
Once `netodns` receives syslog from Infoblox NIOS, it will add a traffic source for Infoblox NIOS to Fusion and you will see DNS traffic in the Fusion Portal. No configuration is required in the Fusion portal.
# Ingest NetFlow & sFlow
Vectra Fusion collects NetFlow, sFlow, and IPFIX from network devices.
Vectra Fusion collects flow records from network devices, including routers, switches, firewalls, and any other device that can output NetFlow, sFlow, or IPFIX.
There are two methods for ingesting these flow records into Fusion:
1. Directly point your network devices to send NetFlow/sFlow to your Vectra Fusion ingest IP and port. This delivers flow records to Fusion via unencrypted UDP packets.
2. Deploy a NetoFlow Connector in your environment and point your network devices to send NetFlow/sFlow to the NetoFlow Connector. The NetoFlow Connector uses TLS over HTTPS, authenticated with a Vectra API key, to deliver the flow records to Fusion in a secure, encrypted, and reliable transport.
### NetFlow and sFlow
See [NetFlow and sFlow](/ingest-network-traffic-logs/netflow-sflow/netflow-and-sflow) for additional details on choosing between NetFlow and sFlow and configuration details for using those formats with your network devices.
### Directly ingest NetFlow from your network devices
#### Add a device traffic source in Fusion
To start ingesting directly from a network device, in the Fusion Portal, go to **Settings**, **Traffic Sources**, and click the **Add a Traffic Source** button. Select **Device** from the list of Flow Sources listed on the **Add Traffic Source** page.

Add flow source from a network device
Fill out the Add Device configuration form. The *Device Name*, *Sample Rate*, and *IP Addresses* fields are required. All other fields are optional. The BGP configuration on the second screen is only required if you are using BGP in a response policy to do automated blocking and can usually be omitted.
Note the IP address and port displayed on this page on the right-hand side where it says **Your Ingest IP**. You will need this when configuring your network devices.
#### Write down your Fusion Ingest IP:port
Now that you have created a device traffic source, you can start sending NetFlow or sFlow to the ingest IP and port for your account. If you did not copy this when adding a device source, the ingest IP:port is available by going to **Settings**, **Overview**, and looking at the **Ingest IP** field on that page.
#### Configure your network devices to send NetFlow to Fusion
You will now configure your network device to send NetFlow to the Ingest IP. Consult your network device documentation for the exact instructions on configuring it to export NetFlow or sFlow.
Fill out the configuration form
You can find more detailed information on our [sFlow](https://docs.netography.com/ingest-network-traffic-logs/netflow-sflow/netflow-and-sflow#sflow) and [NetFlow](https://docs.netography.com/ingest-network-traffic-logs/netflow-sflow/netflow-and-sflow#netflow) references.
# Ingest NetFlow/sFlow from network devices via direct UDP
Send NetFlow or sFlow directly to your Vectra Fusion ingest IP and port.
Vectra Fusion collects flow records from network devices, including routers, switches, firewalls, and any other device that can output NetFlow, sFlow, or IPFIX.
This page documents how to directly point your network devices to send NetFlow or sFlow to your Vectra Fusion ingest IP and port. This delivers flow records to Fusion via unencrypted UDP packets.
If you want to deliver NetFlow or sFlow from your network devices via a TLS-encrypted reliable API connection to the Vectra Fusion SaaS, see: [Ingest NetFlow/sFlow via the NetoFlow Connector](/ingest-network-traffic-logs/netflow-sflow/traffic-source-netoflow).
For more details on NetFlow and sFlow and configuration tips, see: [NetFlow and sFlow](/ingest-network-traffic-logs/netflow-sflow/netflow-and-sflow).
### Steps to Ingest NetFlow/sFlow via direct UDP
There are 2 steps involved in this process:
1. Add a new Device traffic source in Fusion.
2. Configure your network devices to export NetFlow or sFlow to your Vectra Fusion ingest IP and port.
#### 1. Add a new Device traffic source in Fusion
To start ingesting directly from a network device, in the Fusion Portal, go to **Settings**, **Traffic Sources**, and click the **Add a Traffic Source** button. Select **Device** from the list of Flow Sources listed on the **Add Traffic Source** page.

Add flow source from a network device
Fill out the Add Device configuration form. The *Device Name*, *Sample Rate*, and *IP Addresses* fields are required. All other fields are optional. The BGP configuration on the second screen is only required if you are using BGP in a response policy to do automated blocking and can usually be omitted.
Note the IP address and port displayed on this page on the right-hand side where it says **Your Ingest IP**. You will need this when configuring your network devices.
#### Write down your Fusion Ingest IP:port
Now that you have created a device traffic source, you can start sending NetFlow or sFlow to the ingest IP and port for your account. If you did not copy this when adding a device source, the ingest IP:port is available by going to **Settings**, **Overview**, and looking at the **Ingest IP** field on that page.
#### 2. Configure your network devices to send NetFlow to Fusion
You will now configure your network device to send NetFlow to the Ingest IP. Consult your network device documentation for the exact instructions on configuring it to export NetFlow or sFlow.
# Ingest NetFlow/sFlow via the NetoFlow Connector
Add NetFlow or sFlow to Vectra Fusion through the NetoFlow Connector.
Vectra Fusion collects flow records from network devices, including routers, switches, firewalls, and any other device that can output NetFlow, sFlow, or IPFIX.
This page documents how to add NetFlow or sFlow to Fusion by deploying the NetoFlow Connector within your environment and pointing your network devices to that system. This creates a TLS-encrypted reliable API connection to Fusion for ingesting these records. If you want to directly point your network devices to the Vectra Fusion SaaS ingest IP, see [Directly ingest NetFlow/sFlow from network devices](/ingest-network-traffic-logs/netflow-sflow/ingesting-netflow-direct)
For more details on NetFlow and sFlow and configuration tips, see: [NetFlow and sFlow](/ingest-network-traffic-logs/netflow-sflow/netflow-and-sflow).
### Steps to Ingest NetFlow/sFlow via the NetoFlow Connector
There are 3 steps involved in this process:
1. Add a new Device traffic source in Fusion for each network device that will be sending NetFlow or sFlow
2. Deploy NetoFlow Connector locally.
3. Configure your network devices to export NetFlow or sFlow to the NetoFlow Connector.
### 1. Add device traffic sources in Fusion
Add a new traffic source in Fusion for each network device that will deliver NetFlow or sFlow to the NetoFlow Connector. If you do not know all the devices yet, you can proceed with the next steps and then come back and add them later.
Go to **Settings**, **Traffic Sources**, and click the **Add a Traffic Source** button in the Fusion Portal. Select **Device** from the list of Flow Sources on the **Add Traffic Source** page.

Add flow source from a network device
Fill out the Add Device configuration form. The *Device Name*, *Sample Rate*, and *IP Addresses* fields are required. All other fields are optional. The BGP configuration on the second screen is only required if you are using BGP in a response policy to do automated blocking and can usually be omitted.
### 2. Deploy NetoFlow Connector
For instructions on deploying and running the NetoFlow Connector locally, see: [NetoFlow Connector Documentation](/netoflow-connector/about).
### 3. Configure your network devices to export NetFlow or sFlow
You will now configure your network devices to send NetFlow to the IP and port you deployed NetoFlow to listen on in the previous step. Consult your network device documentation for the exact instructions on configuring it to export NetFlow or sFlow.
# NetFlow and sFlow
NetFlow About NetFlow NetFlow is a telemetry protocol that allows for the collection of IP statistics on interfaces where it is enabled. a "flow" is a unidirectional data set. That is to say, it's one
## NetFlow
### About NetFlow
NetFlow is a telemetry protocol that allows for the collection of IP statistics on interfaces where it is enabled. a "flow" is a unidirectional data set. That is to say, it's one side of the connection not both. Once selected and collected this data is then exported in binary format to a remote collector. Typically, routing platforms export netflow whereas switching platforms export sflow.
### NetFlow Versions Supported
* v5
* v9
* v10 (IPFIX)
#### NetFlow Version Differences of Note
* v5 does not support IPV6 due to its specification. IP fields are not big enough to hold an IPV6 address
* v9, v10 are template based which gives flexibility however these templates are often set by vendors and not configurable by the end user.
* v9, v10 templates are NOT sent with the records themselves but at an independent interval. Templates have to be received before data can be decoded. Also if scaling horizontally, templates need to be replicated to other collectors or they will not be able to decode flows.
* v9, v10 sample rate is no longer reported in every flow packet. It it typically defined in an options template which comes at a configurable interval.
#### NetFlow Configuration Recommendations
* Set `active-timeout` to 60
* Set `run-length` to 0 if it exists on your platform
* Only sample input on chosen interfaces
* Follow sample rate table below based on traffic volume, and then adjust once configured
## sFlow
### About sFlow
sFlow is a telemetry protocol that allows for the collection of IP statistics and counters on interfaces where it is enabled. sFlow is implemented on most switching platforms and employs packet sampling as a means to select which IP communications to export to a specified collector. sFlow copies the entire packet header so there is enhanced visibility into other layers.
### sFlow Versions Supported
* v5
#### sFlow Configuration Recommendations
* Only sample input/ingress on chosen interfaces
* Follow sample rate table below based on traffic volume, and then adjust once configured
* Note: Netography does not currently ingest counter records
### Comparing NetFlow and sFlow
#### Flow Sampling (NetFlow) vs. Packet Sampling (sFlow)
There is no superior solution between the two as each has its advantages and disadvantages. With flow sampling, the device picks a 5-tuple (source IP, source port, destination IP, destination port, protocol) depending on the sampling algorithm and tracks relevant statistics for the flow's duration, then exports them at the appropriate time. With packet sampling, the exporter picks every Nth packet and reports the details of that packet.
#### NetFlow Advantages
* Full byte and packet counts for a chosen flow
* All seen TCP Flags for a chosen flow
* Flow start time, end time, and duration
#### sFlow Advantages
* Full packet header and up to 128 bytes of payload
* Less latency in delivering records
* Utilizes fewer resources on devices generating records
#### Netography Use Case Recommendation
NetFlow has a considerable advantage in understanding the complete communication between various devices on the network. However, sFlow will provide more timely updates, so if understanding traffic within seconds is desirable, then sFlow may be a better choice. If the packet headers provided by your particular devices is useful in the sFlow records, that may be a benefit to sFlow.
## Sample Rate Guide Table
The table below is a good starting point for configuring a sample rate based on the network device bandwidth volume. Once you see the volume of flow records generated with this sample rate, consider making additional adjustments to tune this setting. A lower sample rate will produce more records but provide a higher level of granularity.
| Bandwith | Sample Rate |
| --------------------- | ----------- |
| N < 1 Gbps | 10 |
| 1 Gbps < N < 10 Gbps | 100 |
| 10 Gbps < N < 25 Gbps | 1000 |
| N > 25 Gbps | 8000 |
# Configure Context Integrations
Context integrations add third-party asset context to Vectra Fusion.
## About Context Integrations
Context integrations provide enriched asset context to Vectra Fusion from third-party products. This is done by reading asset information from the external product (generally via an API) and then adding asset information as context [Labels](/enrich-traffic-with-context/configure-context-integrations) associated with the asset's IP address.
### Types of context integrations
* **SaaS** - Directly integrated into Vectra Fusion - can only be configured and deployed in the Vectra Fusion SaaS.
* **NetoFuse** - NetoFuse modules can be deployed as a context integration in the Vectra Fusion Portal or deployed locally (as a container or software package) in your environment. Local deployments are useful for on-prem integrations or to maintain control of the configuration, connection, and credentials to a third-party data source locally.
* **Cloud Function** - AWS, Azure, and GCP also support deploying a cloud function via Terraform as part of the Vectra cloud onboarding automation. In this case, context enrichment information is gathered from within your cloud environment, and the function then uses a Fusion API key to make an outbound connection to Fusion to send it to the API. No inbound access to your cloud accounts is used for context enrichment when using a Cloud Function.
To understand more about the difference between Context Integrations and NetoFuse modules, see [About NetoFuse](/netofuse/about).
## Available Context Integrations
### Cloud Providers
| Vendor | Product | Type |
| --------------------- | ------------------------------------------------------------------------------------------------------- | -------------------- |
| Amazon | [Amazon Web Services](/enrich-traffic-with-context/configure-context-integrations/aws) | SaaS, Cloud Function |
| Google Cloud Platform | [Google Cloud Platform](/enrich-traffic-with-context/configure-context-integrations/gcp) | SaaS, Cloud Function |
| IBM | [IBM Cloud](/enrich-traffic-with-context/configure-context-integrations/ibm) | SaaS |
| Microsoft | [Microsoft Azure](/enrich-traffic-with-context/configure-context-integrations/azure) | SaaS, Cloud Function |
| Oracle | [Oracle Cloud Infrastructure](/enrich-traffic-with-context/configure-context-integrations/oracle-cloud) | SaaS |
### Asset Management / Device Inventory
| Vendor | Product(s) | Type |
| -------- | ----------------------------------------------------------------------------------------------- | -------- |
| Axonius | [Axonius Platform](/enrich-traffic-with-context/configure-context-integrations/axonius-context) | NetoFuse |
| Device42 | [Device42](/enrich-traffic-with-context/configure-context-integrations/device42-context) | NetoFuse |
| RunZero | [RunZero](/enrich-traffic-with-context/configure-context-integrations/runzero-context) | NetoFuse |
| Tanium | [Tanium](/enrich-traffic-with-context/configure-context-integrations/tanium-context) | NetoFuse |
### Cloud Security
| Vendor | Product | Type |
| ------ | ---------------------------------------------------------------------- | -------- |
| Wiz | [Wiz](/enrich-traffic-with-context/configure-context-integrations/wiz) | NetoFuse |
### Endpoint Protection Platforms
| Vendor | Product | Type |
| ----------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------- |
| Crowdstrike |
CSV files in any format CSV files in Vectra label format JSON
| NetoFuse |
| [Netography Fusion API Reference](https://docs.netography.com/api-reference) |
CSV files in Vectra label format JSON
| REST API |
## Adding a Context Integration
In the Vectra Fusion Portal:
1. Select **Settings** at the bottom of the left-hand navigation menu
2. Select **Context Integrations** in the **Data Management** section.
3. Select the **Add Integration** button.
4. Select a context integration from the list provided.
5. Follow the configuration steps in the documentation for the context integration you selected.
# AWS
Enrich asset context with asset information from AWS
## About the AWS Context Integration
This context integration adds asset information retrieved from AWS as context labels in Vectra Fusion.
{% hint style="info" %}
**Cloud Context Enrichment: Add a Context Integration vs. Deploying Cloud Function**
AWS, Azure, and GCP have 2 options for how to enrich asset context.
**Option 1: Add a context integration in Fusion Portal**
You give permission in your cloud account(s) for Vectra to read asset meta-data from it, and then add a context integration for that cloud account in Fusion to retrieve that information. After configuring permissions in your cloud, the configuration and data gathering occurs from the Vectra Fusion SaaS to your cloud accounts. You will need to add and configure 1 context integration in Fusion per AWS account, Azure subscription, or GCP project.
**Option 2: Deploy a cloud function with Vectra's Cloud onboarding automation via Terraform**
You deploy the Vectra cloud onboarding automation using Terraform, which configures all the permissions required and creates a cloud function that runs within your cloud on a scheduled basis. That function gathers all the asset meta-data locally within your cloud, and then uploads the data via the Vectra Fusion API. Vectra never has any permission to directly access and read the asset meta-data in your cloud in this option. You can deploy this automation one time for each AWS organization, Azure tenant, or GCP organization, making it a more easily scalable solution for larger environments. For more details on this option, access Vectra's Terraform automation at our GitHub repo: . For access to the repo, reach out to your Vectra contact.
{% endhint %}
## AWS Configuration
{% hint style="info" %}
**Choosing between IAM Role and IAM User authentication**
Vectra supports 2 methods for authentication with AWS:
1. IAM Roles using a Custom Trust Policy created by Vectra
2. IAM user via an Access Key ID & Secret Access Key
Vectra and AWS recommend using **IAM Role** authentication for a production deployment.
For more details, see: [AWS > Documentation > AWS Identity and Access Management > User Guide > Security best practices in IAM > Require workloads to use temporary credentials with IAM roles to access AWS](https://docs.aws.amazon.com/IAM/latest/UserGuide/best-practices.html#bp-workloads-use-roles)
{% endhint %}
### If you have already created an AWS IAM role
You can use the same IAM role you previously configured for collecting VPC Flow Logs. If you already configured [Flow Collection](https://docs.netography.com/ingest-network-traffic-logs/flow-logs) for your AWS environment and used a permission policy that includes `AmazonEC2ReadOnlyAccess`, no additional AWS configuration is needed. Use the same`ARN`, and skip to the Vectra Fusion Configuration section.
If you have an existing AWS IAM Role but it does not have the permissions set or you want to verify the proper permissions, see the [Permission Policy](#permission-policy) section below.
### Creating AWS IAM Role (recommended authentication option)
To use IAM role authentication for Vectra Fusion, first you will go to the Vectra Fusion Portal and gather the required fields, and then you will go to AWS and create the IAM role.
#### Retrieve AWS Custom Trust Policy fields from the Vectra Fusion Portal
In the Vectra Fusion Portal, go to **Account Settings** by clicking the gear icon in top-right corner, scroll down to the **AWS Custom Trust Policy** section, and retrieve the **Account ID**, **sts:ExternalID**, and **Trust Policy** values.
| Field from Vectra Fusion Account Settings | Description |
| ------------------------------------------ | ---------------------------------------------- |
| AWS Custom Trust Policy > **Account ID** | Vectra AWS Account ID used for integration |
| AWS Custom Trust Policy > **External ID** | Vectra issued field used for AWS role creation |
| AWS Custom Trust Policy > **Trust Policy** | Vectra Trust Policy used for AWS role creation |
#### Create a new AWS IAM Role
In AWS, you will create a new IAM role that will delegate access to Vectra using the fields you gathered in the previous step. In addition to those fields, you will need to assign the IAM Role a permission policy.
**Permission Policy**
| AWS Permissions Policy Required |
| ------------------------------- |
| `AmazonEC2ReadOnlyAccess` |
The `AmazonEC2ReadOnlyAccess` permission policy required for only the AWS context integration is listed below. If you have an existing IAM role permission policy, add these statements to it to make it compatible with the AWS context integration (instructions for editing this policy are available at [AWS > Documentation > AWS Identity and Access Management > User Guide > Editing customer managed policies (console)](https://docs.aws.amazon.com/IAM/latest/UserGuide/access_policies_manage-edit.html#edit-managed-policy-console).
{% tabs %}
{% tab title="JSON" %}
```
{
"Version": "2012-10-17",
"Statement": [
{
"Sid": "VisualEditor1",
"Effect": "Allow",
"Action": "ec2:Describe*",
"Resource": "*"
},
{
"Sid": "VisualEditor2",
"Effect": "Allow",
"Action": "elasticloadbalancing:Describe*",
"Resource": "*"
},
{
"Sid": "VisualEditor3",
"Effect": "Allow",
"Action": [
"cloudwatch:ListMetrics",
"cloudwatch:GetMetricStatistics",
"cloudwatch:Describe*"
],
"Resource": "*"
},
{
"Sid": "VisualEditor4",
"Effect": "Allow",
"Action": "autoscaling:Describe*",
"Resource": "*"
}
]
}
```
{% endtab %}
{% endtabs %}
**How to create a new AWS IAM Role**
For instructions on creating an IAM role in AWS using a custom trust policy, refer to [AWS > Documentation > AWS Identity and Access Management > User Guide > Creating a role using custom trust policies](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_roles_create_for-custom.html)
For more information on configuring the permissions to the Account ID, refer to [AWS > Documentation > AWS Identity and Access Management > User Guide > How to use an external ID when granting access to your AWS resources to a third party](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_roles_create_for-user_externalid.html).
**Copy the ARN for the newly created IAM Role**
The ARN for the new IAM role you created will be needed in the next step when adding the AWS context integration to Vectra Fusion.
| IAM Role Field Required | Description |
| ----------------------- | ----------------------------------------------------------------------------- |
| **ARN** | The identifier for the IAM role you retrieve from AWS when creating the role. |
### AWS IAM user authentication (alternative authentication option)
{% hint style="danger" %}
**Skip this section if you are using AWS IAM role authentication**
AWS IAM user authentication with an Access Key ID and Access Secret is an alternative approach to using a AWS IAM role. If you are using the AWS IAM role, skip this entirely and go to the Vectra Fusion Configuration next.
{% endhint %}
The instructions below assume that you have not already created an IAM user as part of Flow Collection setup. If you have already created that role and it includes the `AmazonEC2ReadOnlyAccess` permission, skip to the Vectra Fusion Configuration section.
You must have an IAM user with an already configured programmatic access key or create one to use IAM user authentication.
* To create a new user, follow the [AWS official guidance](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_users_create.html) for new IAM user creation.
* To configure a programmatic access key for the IAM user, refer to the [management access keys](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_credentials_access-keys.html#access-keys_required-permissions) documentation.
| Minimum Required Permissions |
| ---------------------------- |
| `AmazonEC2ReadOnlyAccess` |
To configure the integration with this authentication method, the following AWS IAM user fields are required:
| AWS Parameters | Description |
| --------------- | ---------------------------------------------------------------- |
| `Access Key ID` | Authentication field, available in AWS IAM console for IAM user |
| `Access Secret` | Authentication secret, available in AWS IAM console for IAM user |
## Vectra Fusion Configuration
### 1. Navigate to **Settings** -> **Context Integrations** -> **Add Integration**

#### 2. Select **Amazon Web Services**

#### 3. Configure the context integration
a. Fill out the standard fields required for each context integration:
| Field | Description |
| ----------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `Name` | A unique name to identify this instance of the integration (e.g. `aws1`) |
| `Update Interval` | How frequently to retrieve updated information from AWS in seconds |
| `Auto Update` |
Enable to retrieve updated information automatically at the frequency set by the Update Interval If disabled, the integration can be run manually from the list of configured integrations menu by selecting the ... next to the name of the integration and then selecting Run
|
b. Enter the configuration parameters specific to AWS.
| Field | Required | Description | Example |
| ------------------- | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | ------- |
| `Region` | | If you want to retrieve asset meta-data from only a specific region, you can specify it in this field. Leave this field blank to retrieve data from all regions. | |
| `Tag/Label Matches` | | Tag/Label matches represent the names of tags you use within the cloud provide, i.e, a user might choose to tag all of their web servers with a tag `subsystem` that has a value of `web`. | |
c. Enter the authentication information based on the authentication method you configured in AWS.
#### If you are using AWS IAM role authentication, configure AWS ARN for role
d. Select **Role** for the **Authentication Type** field, and then enter the **AWS ARN** for the IAM Role you created in the previous step (or during Flow Collection setup for AWS).

#### If you are using AWS user authentication, configure Access Key ID and Access Secret
{% hint style="danger" %}
**Skip this section if you are using AWS IAM role authentication**
{% endhint %}
e. Select **Key/Secret** for the **Authentication Type** field, and then enter the **Access Key ID** and **Access Key Secret** fields from the AWS Configuration step (or from the Flow Collection setup for AWS).

f. Select **Create and Run** to save the integration.
# Axonius
The Axonius integration adds enriched asset context to Vectra Fusion.
## About
The Axonius context integration provides enriched asset context to Vectra Fusion from Axonius. It connects to the Axonius Platform API to retrieve asset information and then adds [Context Labels](/enrich-traffic-with-context/labels) to Vectra Fusion.
As Axonius is a flexible platform that has a very broad set of potential queries and fields that may be used, you should expect that using this module will require basic familiarity with Axonius.
{% hint style="info" %}
**NetoFuse Modules: Cloud deployment vs. on-prem deployment**
This page documents how to add and configure the context integration in the Vectra Fusion Portal. This will make a direct connection from the Vectra Fusion SaaS in the cloud to the vendor API. If you prefer to deploy the integration within your own environment, go to the module documentation in [NetoFuse Modules](/netofuse/modules).
{% endhint %}
## Adding a Context Integration
In the Netography Fusion Portal:
1. Select **Settings** at the bottom of the left-hand navigation menu
2. Select **Context Integrations** in the **Data Management** section.
3. Select the **Add Integration** button.
4. Select a context integration from the list provided.
5. Follow the configuration steps in the documentation for the context integration you selected.
## Configuring
| Axonius Field | Required | Description |
| ------------------ | -------- | -------------------------------------------------------------------------------- |
| Axonius URL | yes | URL to Axonius API |
| Axonious API Key | yes | Authentication key for Axonius API |
| Axonius API Secret | yes | Authentication secret for Axonius API |
| Saved Query | no | Saved query used to retrieve asset information |
| Query | no | Manually constructed query used to retrieve asset information |
| Entries | no | Axonius API wizard expression used to retrieve asset information |
| Fields | no | List of fields to return from api - required if using Query or Entries parameter |
{% hint style="info" %}
**You must specify one of Saved Query, Query, or Entries**
There are 3 ways to query Axonius with the integration. You can either used the Saved Query parameter, Query (along with Fields), or Entries (along with Fields) to define the assets and fields to retrieve from the Axonius API.
{% endhint %}
## Axonius Configuration
1. Create an API key in Axonius by following the instructions here: [Axonius REST API](https://docs.axonius.com/docs/axonius-rest-api)
2. Optional: You can create a Saved Query in Axonius and then use that to determine what asset information is retrieved from the Axonius API. See: [Creating and Saving a Saved Query in Axonius](https://docs.axonius.com/docs/saved-queries-devices). If you do not specify a saved query, you must instead directly define the query in the Axonius NetoFuse module configuration below.
### Configuring how the Axonius API is queried
Due to the wide variety in how Axonius is used, the `axonius` NetoFuse module does not have a default configuration for what assets and fields to use from Axonius. At a minimum, you must define the query to use with Axonius and the fields to retrieve.
The `axonius` module has three options available for defining what assets are retrieved and what fields are retrieved for those assets:
#### API query option 1: `saved_query`
See step 2 of the Axonius Configuration section above to set a saved query in Axonius.
#### API query option 2: `query` and `fields`
Use the `query` field with a valid Axonius GUI wizard expression. See [Creating Queries with the Query Wizard](https://docs.axonius.com/docs/query-wizard-and-query-filter) for instructions on constructing queries in the Axonius GUI.
The `fields` field contains the list of Axonius fields to return from the API. To see a list of available fields in your Axonius deployment, you can install the Axonius API client and run the following command:
`axonshell devices get-fields`
#### API query option 3: `entries` and `fields`
The `entries` field contains the Axonius API wizard expression used to return the list of devices. You can get help with this by installing the Axonius API client and running the following command:
`axonshell devices get --help-detailed wizard`
The `fields` field contains the list of Axonius fields to return from the API. To see a list of available fields in your Axonius deployment, you can install the Axonius API client and run the following command:
`axonshell devices get-fields`
#### `client_args` adds additional arguments to pass to the Axonius API client
Any `key:value` parameters included in the `client_args:`section of the module configuration will be directly passed as parameters to the Axonius API client.
#### Tips for configuring queries
The module uses the Axonius API client to connect to and retrieve assets from Axonius. This is a freely available client from Axonius, and it is very helpful to have this client installed and configured on your development or local system if you will use this module. Test the queries and field settings you want to use, and inspect the results that are being returned using the `axonshell devices` commands.
For example, this command can be used as a template for testing different field and query configuration options:
`axonshell devices get --fields '' --query ''`
Download the Axonius API client here:
### Transform
The **Advanced** section of the context integration contains the *Transform* field. This field allows you to add, remove, or change the mapping of fields returned by the vendor API to Vectra Fusion context labels.
See the [Context Transforms](/netofuse/context-transforms) documentation section for more instructions on editing this field.
It may be helpful to first configure all the parameters and the transform field with a [NetoFuse](/netofuse/about) container on your local system and then copy those fields into the Portal once you have validated that everything is configured properly.
# Azure
Ernich asset context with asset information from Azure
This context integration adds asset information retrieved from Azure as context labels in Netography Fusion.
{% hint style="info" %}
**☁️Cloud Context Enrichment: Add a Context Integration vs. Deploying Cloud Function**
AWS, Azure, and GCP have 2 options for how to enrich asset context.
**Option 1: Add a context integration in Fusion Portal**
You give permission in your cloud account(s) for Netography to read asset meta-data from it, and then add a context integration for that cloud account in Fusion to retrieve that information. After configuring permissions in your cloud, the configuration and data gathering occurs from the Netography Fusion SaaS to your cloud accounts. You will need to add and configure 1 context integration in Fusion per AWS account, Azure subscription, or GCP project.
**Option 2: Deploy a cloud function with Netography's Cloud onboarding automation via Terraform**
You deploy the Netography cloud onboarding automation using Terraform, which configures all the permissions required and creates a cloud function that runs within your cloud on a scheduled basis. That function gathers all the asset meta-data locally within your cloud, and then uploads the data via the Netography Fusion API. Netography never has any permission to directly access and read the asset meta-data in your cloud in this option. You can deploy this automation one time for each AWS organization, Azure tenant, or GCP organization, making it a more easily scalable solution for larger environments. For more details on this option, access Netography's Terraform automation at our GitHub repo: . For access to the repo, email your GitHub ID to
{% endhint %}
### Azure Configuration
#### 1. Enter **App registrations** in the search box at the top of the portal

#### 2. Click **New registration**

#### 3. Give this new application a descriptive name

#### 4. Leave **Supported account type** set as default

#### 5. Click **Register**

#### 6. Copy and save the **Application Client ID** and the **Directory Tenant ID**, you'll need this later for integration with Netography Fusion.

#### 7. Click **Add a certificate or secret**

#### 8. Click **New client secret**

#### 9. Add a description and select an expiration consistent with the policies of your organization

#### 10. Click **Add**

#### 11. Copy and save the Client Secret **Value**, you'll need this later for integration with Netography Fusion.

#### 12. Go to **Subscriptions** and select your working subscription

#### 13. Select **Access control (IAM)** from the sidebar

#### 14. Click the **Role assignments** tab

#### 15. Click **Add** then **Add role assignment** from the dropdown

#### 16. Select **Reader** role.

#### 17. Click **Next**

#### 18. Click **Select members**

#### 19. Search for the application name you created earlier in step 3 and select it

#### 20. Click the **Select** button

#### 21. Click **Review + assign**

### Netography Fusion Configuration
#### 1. Navigate to **Settings** -> **Context Integrations** -> **Add Integration**

#### 2. Select **Microsoft Azure**

#### 3. Fill out the Azure Context Integration form:
**Name**: Use any name here.
**Update Interval**: Leave as default.
**Auto Update**: Leave enabled.
**Subscription ID**: The Subscription ID you used to complete the previous instructions in this document.
**Tenant ID**: Your Azure Tenant ID.
**Tag/Label Matches**: Leave as default unless you know how to use this feature.
**Application Client ID**: Paste in the "Applicant (client) ID" you copied from a previous step in this document.
**Client Secret Value**: Paste in the Client Secret **Value** you copied from a previous step in this document.
#### 4. Click **Create and Run**
# Claroty
The Claroty integration adds enriched asset context to Vectra Fusion.
## About
The Claroty NetoFuse module provides enriched asset context to Vectra Fusion from Claroty Industrial Cybersecurity appliances. It connects to the Claroty CTD/EMC API to retrieve asset information and then adds it as [Context Labels](/enrich-traffic-with-context/labels) in Vectra Fusion.
{% hint style="info" %}
**NetoFuse Modules: Cloud deployment vs. on-prem deployment**
This page documents how to add and configure the context integration in the Vectra Fusion Portal. This will make a direct connection from the Vectra Fusion SaaS in the cloud to the vendor API. If you prefer to deploy the integration within your own environment, go to the module documentation in [NetoFuse Modules](broken://pages/6i3otB8UAClHx08Umd0Y).
{% endhint %}
### Supported Products
#### Claroty Threat Detection (CTD)
#### Claroty Enterprise Management Console (EMC)
{% hint style="info" %}
**Integrate to Claroty EMC if you have deployed it, and Claroty CTD if not**
Claroty EMC aggregates data from multiple Claroty CTD appliances. Therefore, if you have deployed one or more Claroty EMCs in your environment, follow the configuration steps for each Claroty EMC appliance rather than each Claroty CTD.
The API and configuration steps are identical for both CTD and EMC appliances, so they are not differentiated in the documentation or in the `claroty` NetoFuse module.
{% endhint %}
## Configuring
All the fields required and optional for this integration are listed here.
| Field | Required | Description |
| ---------------- | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Claroty URL | Yes | URL used to access Claroty appliance |
| Claroty Username | Yes | Username to authenticate with |
| Claroty Password | Yes | Password to authenticate with |
| Per Page | Yes | Number of results to return per page from Claroty API (default 5000) |
| Fields | Yes | The fields to return from the Claroty API. If left blank, all asset fields are returned by the API, increasing the load on the Claroty appliance. You also must add fields to the Transform field in the Advanced section to map it to a Vectra context label name. |
Consult the *Claroty Web API User Guide* for further assistance configuring these parameters, and use the *Claroty API Explorer* to experiment with parameters.
If you need to filter the list of assets returned by the Claroty API, additional parameters for configuration are available when using the [Claroty](/netofuse/modules/claroty) NetoFuse module on-prem. Vectra Support can assist you if you want to add any of these parameters to a cloud deployment of this integration.
## Claroty CTD/EMC Configuration
### Create a read-only account in Claroty
1. Login to the Claroty CTD or EMC appliance.
2. Click the gear icon in the bottom left of screen.
3. Select User Management > Users and click `+` to add a user.
4. Add a user (e.g. `neto-api-user`) and save.
5. Go to User Management > Groups and click `+` to add a group.
6. Add a group (e.g., `Read Only API Group`), add the user you created.
7. Provide read permissions for the site(s) and assets as appropriate.
You can select more granular permissions for the group based on the data you want to be read from the system.
Consult the Claroty documentation if you encounter problems creating a user.
Use the account you just created, along with the URL to the appliance you created the account on, to configure the `claroty` NetoFuse module.
### Transform
The **Advanced** section of the context integration contains the *Transform* field. This field allows you to add, remove, or change the mapping of fields returned by the vendor API to Vectra Fusion context labels.
See the [Context Transforms](/netofuse/context-transforms) documentation section for more instructions on editing this field.
It may be helpful to first configure all the parameters and the transform field with a [NetoFuse](/netofuse/about) container on your local system and then copy those fields into the Portal once you have validated that everything is configured properly.
# CrowdStrike Falcon Discover
Configure CrowdStrike Falcon Discover for the Vectra context integration.
{% hint style="warning" %}
**The CrowdStrike Falcon Discover module is required for this integration.**
{% endhint %}
This document provides instructions for configuring CrowdStrike in order for the Vectra context integration to have the correct access to pull label contexts.
## Prerequisites
Before configuring the CrowdStrike Falcon Discover context integration in Vectra, you will need to have an API user created in CrowdStrike.
### Configure an API Client
* On the left hand menu expand the "Support and resources" submenu.
* Then click on API clients and keys.\

* Click on the "add new API client" button in the top right\

* Fill out the client name.
* Give the key a description.
* In the API Scopes table select Read permission for "Hosts" and "Assets.
* Click Create at the bottom to create this api client.\

* After clicking "Create" you will be presented with a screen that shows the credentials like below. Make note of the `CLIENT ID`, `SECRET` and subdomain from the `BASE URL`.
* Note: The Subdomain of the base URL is what to select for Cloud abbreviation.
**📘 If the BASE URL is api.crowdstrike.com then your cloud is US-1.**

## Vectra portal steps
Navigate to Integrations (make sure you are on the Context tab) and click "Add Integration", then select `CrowdStrike Falcon Discover`

### Configuration
The following fields are specific to the CrowdStrike Falcon Discover integration.
| Field | Required | Description | Example |
| -------------------- | -------- | -------------------------------------------------------------------------------- | ------------------------------------------------------ |
| `Cloud Abbreviation` | yes | The falcon cloud to query. Found as the subdomain from the CrowdStrike`BASE URL` | US 2 |
| `Filter` | | An optional FQL string to be used when filtering results. | entity\_type:'managed'+last\_seen\_timestamp:<'now-3d' |
| `Sort` | | An optional FQL sort string. | last\_seen\_timestamp.desc |
### Authentication
The following fields are necessary for the integration to authenticate with CrowdStrike.
| Field | Required | Description |
| --------------- | -------- | --------------------------- |
| `Client ID` | yes | The CrowdStrike `CLIENT ID` |
| `Client Secret` | yes | The CrowdStrike `SECRET` |
# CrowdStrike Falcon Protect
Configure CrowdStrike Falcon Protect for the Vectra context integration.
This document provides instructions for configuring CrowdStrike in order for the Vectra context integration to have the correct access to pull label contexts.
## Prerequisites
Before configuring the CrowdStrike Falcon Protect context integration in Vectra, you will need to have an API user created in CrowdStrike.
### Configure an API Client
* On the left hand menu expand the "Support and resources" submenu.
* Then click on API clients and keys.\

* Click on the "Create API client" button in the top right\

* Fill out the client name.
* Give the key a description.
* In the API Scopes table select Read permission for "Hosts".
* Click add at the bottom to create this api client.
**📘The CrowdStrike Falcon Protect setup uses the same steps as Discover but only the Read permission is required for Hosts, as exampled below in the Add new API client window:**

* After clicking "Create" you will be presented with a screen that shows the credentials like below. Make note of the `CLIENT ID`, `SECRET` and subdomain from the `BASE URL`.
* Note: The Subdomain of the base URL is what to select for Cloud abbreviation.
**📘 If the BASE URL is api.crowdstrike.com then your cloud is US-1.**

## Vectra portal steps
Navigate to Integrations (make sure you are on the Context tab) and click "Add Integration", then select `CrowdStrike Falcon Protect`

### Configuration
The following fields are specific to the CrowdStrike Falcon Protect integration.
| Field | Required | Description | Example |
| -------------------- | -------- | -------------------------------------------------------------------------------- | ------------------------------------------------------ |
| `Cloud Abbreviation` | yes | The falcon cloud to query. Found as the subdomain from the CrowdStrike`BASE URL` | US 2 |
| `Filter` | | An optional FQL string to be used when filtering results. | entity\_type:'managed'+last\_seen\_timestamp:<'now-3d' |
| `Sort` | | An optional FQL sort string. | last\_seen\_timestamp.desc |
### Authentication
The following fields are necessary for the integration to authenticate with CrowdStrike.
| Field | Required | Description |
| --------------- | -------- | --------------------------- |
| `Client ID` | yes | The CrowdStrike `CLIENT ID` |
| `Client Secret` | yes | The CrowdStrike `SECRET` |
# CSV via S3
The CSV via S3 context Integration method allows you to import Context Labels from a CSV format file stored in an AWS S3 storage bucket. This integration can be set to run manually or to auto-update a
The CSV via S3 context Integration method allows you to import [Context Labels](broken://pages/tHdQlLNEcPVYOcADGLKm) from a CSV format file stored in an AWS S3 storage bucket. This integration can be set to run manually or to auto-update at an interval you specify.
### CSV File Format
The CSV must be a text file and should NOT have any headers.
Multiple labels can be assigned per context by having additional columns.
The format of the CSV file is `ip,context,label1,label2,...`
For example:
```
IP1, Context1, Label1
IP1, Context2, Label1, Label2
IP2, Context1, Label1
IP2, Context2, Label1, Label2, Label3
```
### Netography Portal Steps
Navigate to Integrations (make sure you are on the Context tab) and click "Add Integration", then select `CSV via S3`

#### Configuration
The following fields are specific to the CSV via S3 integration.
| Field | Required | Description | Example |
| --------------- | -------- | ----------------------------------------------------- | --------- |
| `Region` | yes | Location of the Amazon Web Services | us‑east‑1 |
| `Bucket Name` | yes | Name of the s3 bucket from which to pull the csv file | |
| `CSV File Path` | yes | Path to the csv file to import labels from. | |
#### Authentication
Netography Fusion can access your AWS account using one of two different methods:
1. IAM user via an Access Key ID & Secret Access Key
2. IAM Roles using a Custom Trust Policy created by Netography.
**AWS Access Key**
To configure access via Access Key/Secret, select the "Key/Secret" Authentication Type. The values for the ID and Secret are accessible in the AWS IAM console.

**AWS IAM Roles**
You can use an IAM role in Netography Fusion to access your Cloud Flow Logs for flow ingest or account data for the AWS Context Integration. To enable this, go to the portal and retrieve the **AWS Account ID** and **External ID** from your Account Settings. Navigate to the gear button on the top right to view your Account Settings to see the Overview tab as shown below:

In AWS, you will configure permissions using the Account ID grabbed from above to create the IAM Role. When configured, AWS creates the Amazon Resource Number (ARN) for the role. For more information in configuring the permissions to the Account ID, refer to the [external ID guide](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_roles_create_for-user_externalid.html).
{% hint style="warning" %}
**🚧The newly created ARN is required in order to configure IAM role access in the Netography Fusion portal.**
{% endhint %}
Once the ARN has been created, the remaining steps are to toggle the Authentication Type to **Role** in your AWS
S3 configuration settings, input the **AWS Account ID** grabbed earlier from your Netography account settings, and the supply the **ARN configured from AWS** as shown below:

# Device42
The Device42 integration adds enriched asset context to Vectra Fusion.
## About
The Device42 context integration provides enriched asset context to Vectra Fusion from the Device42 asset management platform. It connects to the Device42 API to retrieve asset information from the Devices table and then uploads it as [Context Labels](/enrich-traffic-with-context/labels) to the Vectra Fusion API.
{% hint style="info" %}
**☁️NetoFuse Modules: Cloud deployment vs. on-prem deployment**
This page documents how to add and configure the context integration in the Vectra Fusion Portal. This will make a direct connection from the Vectra Fusion SaaS in the cloud to the vendor API. If you prefer to deploy the integration within your own environment, go to the module documentation in [NetoFuse Modules](broken://pages/6i3otB8UAClHx08Umd0Y).
{% endhint %}
## Adding a Context Integration
In the Vectra Fusion Portal:
1. Select **Settings** at the bottom of the left-hand navigation menu
2. Select **Context Integrations** in the **Data Management** section.
3. Select the **Add Integration** button.
4. Select a context integration from the list provided.
5. Follow the configuration steps in the documentation for the context integration you selected.
## Configuring
| Field | Required | Description |
| ------------- | -------- | ------------------------------------------------------------------------------ |
| URL | Yes | URL to Device42 API |
| Username | Yes | Device42 User Authentication Username, if used instead of Token Authentication |
| Password | Yes | Device42 User Authentication Password, if used instead of Token Authentication |
| IP Fields | Yes | Device42 fields to retrieve via API |
| Fetch Devices | No | If set to true, gathers additional fields from Devices table in Device42 |
| Per Page | No | Number of results per API call (max: 1000) |
### Selecting Token Authentication or User Authentication
*Token authentication is being added in an upcoming release. If you would like to use token authentication now, please contact Vectra Support.*
Device42 can use either Token Authentication or User Authentication to connect to the API. Token authentication is the recommended approach for a production deployment.
The `Username` and `Password` fields are not required if token authentication is used (and conversely, the `Client Key` and `Client Secret` fields are not required if User authentication is used).
## Device42 Configuration
If using Token Authentication, follow Device42 instructions to generate a `Client Key` and `Client Secret` for a production deployment as documented here:
### Transform
The **Advanced** section of the context integration contains the *Transform* field. This field allows you to add, remove, or change the mapping of fields returned by the vendor API to Vectra Fusion context labels.
See the [Context Transforms](/netofuse/context-transforms) documentation section for more instructions on editing this field.
It may be helpful to first configure all the parameters and the transform field with a [NetoFuse](/netofuse/about) container on your local system and then copy those fields into the Portal once you have validated that everything is configured properly.
# GCP
Configure GCP for the Vectra context integration.
This document provides instructions for configuring Google Cloud Provider (GCP) in order for the Vectra context integration to have the correct access to pull label contexts.
{% hint style="info" %}
**Cloud Context Enrichment: Add a Context Integration vs. Deploying Cloud Function**
AWS, Azure, and GCP have 2 options for how to enrich asset context.
**Option 1: Add a context integration in Fusion Portal**
You give permission in your cloud account(s) for Vectra to read asset meta-data from it, and then add a context integration for that cloud account in Fusion to retrieve that information. After configuring permissions in your cloud, the configuration and data gathering occurs from the Vectra Fusion SaaS to your cloud accounts. You will need to add and configure 1 context integration in Fusion per AWS account, Azure subscription, or GCP project.
**Option 2: Deploy a cloud function with Vectra's cloud onboarding automation via Terraform**
You deploy the Vectra cloud onboarding automation using Terraform, which configures all the permissions required and creates a cloud function that runs within your cloud on a scheduled basis. That function gathers all the asset meta-data locally within your cloud, and then uploads the data via the Vectra Fusion API. Vectra never has any permission to directly access and read the asset meta-data in your cloud in this option. You can deploy this automation one time for each AWS organization, Azure tenant, or GCP organization, making it a more easily scalable solution for larger environments. For more details on this option, access Vectra's Terraform automation at our GitHub repo: . For access to the repo, email your GitHub ID to
{% endhint %}
### GCP Configuration
#### 1. Create a GCP service account
Before configuring the GCP context integration in Vectra, you must create a service account in GCP following these steps. For more details, see [GCP: Create service account](https://cloud.google.com/iam/docs/service-accounts-create).
**a. Go to the Service Accounts page**

**b. Click Create Service Account and follow the steps in the wizard.**

**c. Create a service account name; your service account ID email address will be auto-created.**

**d. Click Select a role, use the Filter, type viewer into the filter, click Viewer to give this service account a Viewer role.**

Leave the rest set as default.
#### 2. Create your service account access keys and export a JSON file
**a. Click : to access Actions for your newly created service account, then select Manage keys.**

**b. Click the Add Key menu and select Create new key**

**c. Choose JSON format. This will enable you to export a file that will automate context configuration in Vectra Fusion and reduce setup to one step.**

**d. The JSON file containing your private key will be auto-downloaded to your computer; delete this file once you're done with it.**

#### 3. Create a new context integration in Vectra Fusion and upload your JSON file.
a. In the Fusion portal, select **Settings** > **Context Integrations** > **Add Integration**

b. Select **Google Cloud Platform**

c. Use the "**IMPORT FROM JSON**" button to import the JSON file you exported from GCP.

d. Leave **Zone** blank to include all zones automatically.

e. All fields will be auto-completed, and your private key will be imported.
f. Click **Create and Run** to save.

{% hint style="success" %}
**You're done!**
{% endhint %}
Check **Context Labels** to verify your context integration is working as expected.

# IBM Cloud
Configure IBM Cloud for the Vectra context integration.
## Prerequisites
### Configure API Key
Before configuring the IBM Cloud context integration in Vectra, you will need to have an API key already configured or set up. To set up an IBM Cloud API key, follow the API key creation [procedure](https://www.ibm.com/docs/en/app-connect/container?topic=servers-creating-cloud-api-key#taskcreatingapikey**steps**1).
## Vectra portal steps
Navigate to Integrations (make sure you are on the Context tab) and click "Add Integration", then select `IBM Cloud`

### Configuration
The following fields are specific to the IBM integration.
| Field | Required | Description | Example |
| -------- | -------- | ------------ | ------- |
| `Region` | yes | Cloud Region | us‑east |
### Authentication
The following fields are necessary for the integration to authenticate with IBM.
| Field | Required | Description |
| --------- | -------- | ------------------------------------------------- |
| `API Key` | yes | API Key created earlier for authenticating to IBM |
# Microsoft Defender
Supported Products Microsoft Defender For Endpoint Microsoft Defender XDR ⚖️ Choosing which context integration to use: Both Microsoft Defender context integrations can be used to provide enriched ass
## Supported Products
### [Microsoft Defender For Endpoint](#microsoft-defender-for-endpoint-1)
The Microsoft Defender for Endpoint context integration provides enriched asset context to Vectra Fusion from Microsoft Defender for Endpoint. It connects to the Microsoft Defender for Endpoint API, retrieves asset information associated with a collection of `Machines`, then adds it as [Context Labels](/enrich-traffic-with-context/labels) to Vectra Fusion.
### [Microsoft Defender XDR](#microsoft-defender-xdr-1)
The Microsoft Defender XDR NetoFuse module provides enriched asset context to Vectra Fusion from Microsoft Defender XDR. It connects to the Microsoft Security Graph API, allowing you to define a custom Kusto (KQL) query to retrieve data from any schema available in Microsoft Defender XDR's advanced hunting tool, and then adds the results as [Context Labels](/enrich-traffic-with-context/labels) to Vectra Fusion.
{% hint style="info" %}
**⚖️Choosing which context integration to use**
Both Microsoft Defender context integrations can be used to provide enriched asset context to Vectra Fusion from Microsoft Defender For Endpoint.
The Microsoft Defender for Endpoint NetoFuse module requires no configuration beyond setting up API access and works with all Microsoft Defender for Endpoint deployments.
The Microsoft Defender XDR context integration provides a flexible Kusto (KQL) integration to Microsoft Defender XDR's advanced hunting schemas and is built for advanced users in organizations with Microsoft Defender for Endpoint P2 licenses. This module can be used to query and join information across the full suite of Microsoft XDR products including Endpoint, Identity, Cloud, and E-Mail.
Use of the integrations is not mutually exclusive. You can start with the Microsoft Defender for Endpoint context integration to cover the basic asset information, and then extend that by building Kusto queries to use with the Microsoft Defender XDR context integration as you pinpoint additional context to use for enrichment. If you may want to use both in the future, add both the permissions listed below when creating the Microsoft Entra application used to provide access credentials for the APIs:
* `Machine.Read.All`permission in the `WindowsDefenderATP`API (Microsoft Defender for Endpoint)
* `ThreatHunting.Read.All`permission in the `Microsoft Graph`API (Microsoft Defender XDR)
{% endhint %}
***
## Microsoft Defender for Endpoint
The Microsoft Defender for Endpoint context integration provides enriched asset context to Vectra Fusion from Microsoft Defender for Endpoint. It connects to the Microsoft Defender for Endpoint API, retrieves asset information associated with a collection of `Machines`, then adds it as [Context Labels](/enrich-traffic-with-context/labels) to Vectra Fusion.
This utilizes the Microsoft Defender for Endpoint [List machines API](https://learn.microsoft.com/en-us/microsoft-365/security/defender-endpoint/api/get-machines?view=o365-worldwide).
### Configuring
| Field | Required | Description |
| -------------- | -------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Tenant ID | Yes | Azure tenant ID |
| Application ID | Yes | Azure application id |
| App Secret | Yes | Azure application secret |
| Per Page | Yes | Number of results per API call to retrieve (default 1000) |
| Filter | No | If set, it limits what Machines are retrieved by the API. Microsoft documentation for the `filter` field is available at: [OData queries with Microsoft Defender for Endpoint](https://learn.microsoft.com/en-us/microsoft-365/security/defender-endpoint/exposed-apis-odata-samples?view=o365-worldwide). |
### Microsoft Defender for Endpoint Configuration
You need to create a Microsoft Entra application with`Machine.Read.All` permission in the `WindowsDefenderATP` API. An Azure user with the `Global Administrator` role must perform this step.
See: [Create an app to access Microsoft Defender for Endpoint without a user](https://learn.microsoft.com/en-us/microsoft-365/security/defender-endpoint/api/exposed-apis-create-app-webapp?view=o365-worldwide)
### Transform
The **Advanced** section of the context integration contains the *Transform* field. This field allows you to add, remove, or change the mapping of fields returned by the vendor API to Vectra Fusion context labels.
See the [Context Transforms](/netofuse/context-transforms) documentation section for more instructions on editing this field.
It may be helpful to first configure all the parameters and the transform field with a [NetoFuse](/netofuse/about) container on your local system and then copy those fields into the Portal once you have validated that everything is configured properly.
Comment and uncomment fields in the transform to select which are included as context labels.
***
## Microsoft Defender XDR
The Microsoft Defender XDR NetoFuse module provides enriched asset context to Vectra Fusion from Microsoft Defender XDR. It connects to the Microsoft Security Graph API, allowing you to define a custom Kusto (KQL) query to retrieve data from any schema available in Microsoft Defender XDR's advanced hunting tool, and then adds the results as [Context Labels](/enrich-traffic-with-context/labels) to Vectra Fusion.
This utilizes the `runHuntingQuery`API endpoint in the [Microsoft Security Graph API](https://learn.microsoft.com/en-us/graph/api/resources/security-api-overview?view=graph-rest-1.0#advanced-hunting).
### Requirements
{% hint style="danger" %}
**❗️The Microsoft Defender XDR context integration requires you are using a Microsoft Defender for Endpoint Plan 2 (P2) license from Microsoft to access device information**
Device level data collected through Microsoft Defender for Endpoint is only available through the API this module uses I with a Microsoft Defender for Endpoint Plan 2 (P2) license. If your organization is using a Plan 1 (P1) license, use the Microsoft Defender for Endpoint module and not the Microsoft Defender XDR module. For more details on this, see: [Compare Microsoft endpoint security plans](https://learn.microsoft.com/en-us/microsoft-365/security/defender-endpoint/defender-endpoint-plan-1-2?view=o365-worldwide).
If you are a Microsoft Defender admin, you can go to , and click the Schemas tab to see what access you have to this feature. If you see a `Devices` schema with a `DeviceInfo` table, you have the right access. If that is missing, you may be on a P1 plan or do not have permissions for advanced hunting in your user role.
You could still theoretically use this module without access to the `Devices` schema, but you will need to determine if the schemas available to you can provide asset information that can be used as context labels.
{% endhint %}
### Configuring
| Field | Required | Description |
| -------------- | -------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Tenant ID | Yes | Azure tenant ID |
| Application ID | Yes | Azure application id |
| App Secret | Yes | Azure application secret |
| Queries | Yes | Kusto (KQL) query to use with integration |
| Skip Transform | Yes | KQL supports direct field mapping within the Kusto query, so separate transforms are unnecessary for this module. This is set to`True` by default, and will add context labels for all keys returned in the assets. The `ip` field is required to exist for labels to be uploaded. All other fields are optional.\*\* |
### Microsoft Defender XDR Configuration
You need to create a Microsoft Entra application with the `ThreatHunting.Read.All` permission in the `Microsoft Graph` API. An Azure user with the `Global Administrator` role must perform this step.
See: [Microsoft Graph Documentation > Develop > Authentication and authorization > Get access without a user](https://learn.microsoft.com/en-us/graph/auth-v2-service?tabs=http).
#### Configuring KQL Queries
KQL Queries are the base of the Microsoft Defender XDR module. Developing queries in the [Microsoft Defender Advanced Hunting Portal](https://learn.microsoft.com/en-us/microsoft-365/security/defender/advanced-hunting-overview?view=o365-worldwide) is recommended, and then copy the queries once they return the results you want into the module configuration.
The `DeviceInfo` table in the `Devices` schema is the source of the basic asset information in queries. More information on building KQL queries is available from Microsoft at [Proactively hunt for threats with advanced hunting in Microsoft Defender XDR](https://learn.microsoft.com/en-us/microsoft-365/security/defender/advanced-hunting-overview?view=o365-worldwide\&preserve-view=true) and [Microsoft Security Copilot in advanced hunting](https://learn.microsoft.com/en-us/microsoft-365/security/defender/advanced-hunting-security-copilot?view=o365-worldwide).
**KQL Query Examples**
Below are some KQL query configurations.
**Get Public IP and Device Platform**
{% tabs %}
{% tab title="YAML" %}
```
'DeviceInfo | distinct ip=PublicIP, os=OSPlatform'
```
{% endtab %}
{% endtabs %}
**Retrieve newest Device ID, OS, OS Version and Onboarding Status from Device Info**
{% tabs %}
{% tab title="YAML" %}
```
'DeviceInfo
| distinct ip=PublicIP, os=OSPlatform, osver=OSVersion, msd_exposurelevel=ExposureLevel, msd_devicevalue=AssetValue, msd_osbuild=OSBuild, msd_onboardingstatus=OnboardingStatus, msd_id=DeviceId, Timestamp
| summarize arg_max(Timestamp, *) by msd_id
| project-away Timestamp'
```
{% endtab %}
{% endtabs %}
**Add DeviceName, OS, OSVer, Architecture, Interface Name, Mac Address, Manufacturer, ip, and Logged On Users.**
{% tabs %}
{% tab title="YAML" %}
```
'let base = DeviceNetworkInfo
| where Timestamp > ago(24h)
| mv-expand parsejson(IPAddresses)
| distinct DeviceId, ip=tostring(IPAddresses.IPAddress), ifname=NetworkAdapterName, MacAddress
| join kind=fullouter DeviceEvents on DeviceId
| join kind=fullouter (DeviceInfo
| mv-expand parse_json(LoggedOnUsers)) on DeviceId
| distinct name=DeviceName, os=OSPlatform, osver=OSVersion, arch=OSArchitecture, ifname, manufacturer=Vendor, DeviceId, Timestamp, ip, PublicIP, eventuser=tostring(LoggedOnUsers.UserName), mac_addr=MacAddress
| summarize arg_max(Timestamp, *) by DeviceId;
base
| project-away PublicIP
| union (
base | project-away ip | project-rename ip=PublicIP)
| where not( isempty(ip))'
```
{% endtab %}
{% endtabs %}
### Transform
{% hint style="info" %}
**⚖️Context transforms are not needed for this module, but are supported**
KQL supports direct field mapping within the Kusto query, and as such separate transforms are not necessary for this module. The `skip_transform` setting is set to `True` by default, and will add labels for all keys returned in the assets.
**The `ip` field is required to exist for labels to be uploaded. All other fields are optional.**
If you set `skip_transform` to `False`, you can still use context transforms with this context integration. This would be useful if you wanted to do some more advanced post-processing of the data returned by the KQL query beyond what is natively available with Kusto.
{% endhint %}
The **Advanced** section of the context integration contains the *Transform* field. This field allows you to add, remove, or change the mapping of fields returned by the vendor API to Vectra Fusion context labels.
See the [Context Transforms](/netofuse/context-transforms) documentation section for more instructions on editing this field.
It may be helpful to first configure all the parameters and the transform field with a [NetoFuse](/netofuse/about) container on your local system and then copy those fields into the Portal once you have validated that everything is configured properly.
# Oracle Cloud Infrastructure
This document provides instructions for configuring Oracle Cloud Infrastructure (OCI) in order for the Vectra Context Integration to have the correct access to pull label contexts. Prerequisites B
This document provides instructions for configuring Oracle Cloud Infrastructure (OCI) in order for the Vectra Context Integration to have the correct access to pull label contexts.
## Prerequisites
Before configuring the OCI Context Integration in Vectra, you will need to have a group, policy, user, and tenancy OCID configured in OCI. Refer to the below instructions for more configuration information.
### Create a group
1. In the top left menu click on "Identity & Security" and then click on "Domain" in the next menu to the right
2. If you have more than one domain, select your main domain. If not, skip this step (you'll just see the main domain).
3. On the next screen click "User Management" in the top bar.
4. Scroll down to the Groups section, and click on "Create Group".
4. Name the group `vectra-fusion-context-group` and give it a description of your choice. Then, click "Create" to create the group.
### Create a policy
1. In the top left menu click on "Identity & Security" and then click on "Policies"
2. On the following screen click "Create Policy"
3. Complete the Policy Form as follows:
1. Name: `vectra-fusion-context-policy`
2. Description: `Context Policy for Vectra Fusion`
3. Compartment: Your root compartment (varies)
4. Toggle the manual editor, and then paste the following policy:
```
allow group vectra-fusion-context-group to read virtual-network-family in tenancy
allow group vectra-fusion-context-group to read instance-family in tenancy
```
4. Click "Create" to complete the policy creation.
### Create a User
1. In the top left menu click on "Identity & Security" and then click on "Domain" in the next menu to the right
2. If you have more than one domain, select your main domain. If not, skip this step (you'll just see the main domain).
3. On the next screen click "User Management" in the top bar.
4. Click "Create User".
5. Fill in the User creation form as follows:
1. First Name: `Vectra Fusion`
2. Last Name: `Context User`
3. Username: `vectra-fusion-context-user`
4. Toggle `Use the email address as the username` off.
6. Scroll down, and select the group `vectra-fusion-context-group`. Click "Create" to create the user.
### Obtain User and Tenancy OCIDs
1. On the page of the user we just configured click "Copy" under User Information to copy the User OCID as this is needed for the Vectra Fusion portal configuration.
2. Click on the user icon in the top right corner and select Tenancy from the menu
3. On the tenancy page click the copy button to obtain the tenancy OCID. This is also needed for the Vectra Fusion portal.
1. Also note the region as that will also be required in the Vectra Fusion portal.
## Vectra Fusion Portal Steps
Navigate to Integrations (make sure you are on the Context tab) and click "Add Integration", then select `Oracle Cloud Infrastructure`

### Authentication
The following fields are necessary for the integration to authenticate with Oracle Cloud Infrastructure.
| Field | Required | Description |
| -------------- | -------- | --------------------------------------------------- |
| `User OCID` | yes | User OCID to use for authentication to Oracle Cloud |
| `Tenancy OCID` | yes | Tenancy ocid to use for connecting to Oracle Cloud |
### Configuration
The following fields are specific to the Oracle integration.
| Field | Required | Description | Example |
| ------------------- | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | ------- |
| `Tag/Label Matches` | | Tag/Label matches represent the names of tags you use within the cloud provider. IE. A user might choose to tag all of their web servers with a tag "subsystem" that has a value of "web". | |
#### Retrieve the public key information
Once the integration has been created, return to edit the cloud provider you just created.

Make note of the public key and fingerprint. This information will be used in the post configuration step within COS.

### Oracle Steps (Continued)
### Add API Key to Oracle Cloud User
1. Navigate in the Oracle Cloud GUI to the user we just created under "Identity & Security" > "Users"
2. Select the `vectra-fusion-context-user` user you created.
3. On the top menu click "API Keys".
4. Next click "Add API Key".
5. Select "Paste Public Key" in the "Add API Key" modal.
1. Then, paste the public key from the Vectra context integration into the text area.
6. Click the "Add" button to complete the configuration.
7. Click "Close" on the resulting window titled "Configuration File Preview".
The integration should now be functioning.
# RunZero
The RunZero integration adds enriched asset context to Vectra Fusion.
## About
The RunZero NetoFuse module provides enriched asset context to Vectra Fusion from the RunZero Cyber Asset Attack Surface Management platform. It connects to the RunZero API to retrieve asset information and then adds Context Labels to Vectra Fusion.
{% hint style="info" %}
**NetoFuse Modules: Cloud deployment vs. on-prem deployment**
This page documents how to add and configure the context integration in the Vectra Fusion Portal. This will make a direct connection from the Vectra Fusion SaaS in the cloud to the vendor API. If you prefer to deploy the integration within your own environment, go to the module documentation in [NetoFuse Modules](broken://pages/6i3otB8UAClHx08Umd0Y).
{% endhint %}
## Adding a Context Integration
In the Vectra Fusion Portal:
1. Select **Settings** at the bottom of the left-hand navigation menu
2. Select **Context Integrations** in the **Data Management** section.
3. Select the **Add Integration** button.
4. Select a context integration from the list provided.
5. Follow the configuration steps in the documentation for the context integration you selected.
## Configuring
| Field | Required | Description |
| ------------------ | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| Organization UUUID | Yes | RunZero Organization ID |
| Client ID | Yes | RunZero API client ID |
| Client Secret | Yes | RunZero API client secret |
| Field | No | Filters the fields returned by RunZero API. This is a comma-separated list of fields. Supported fields are available at . If the fields parameter is not provided, all fields will be pulled. Note that the Vectra API does not currently support integer fields. |
## RunZero Configuration
### 1. Register an API client in the RunZero console
Register an API client in the RunZero console to obtain the Client ID and Client Secret for authentication to the API.
### 2. Obtain the RunZero Organization ID to use
A list of all organization IDs for your RunZero account can be retrieved via the RunZero API.
This can be done using RunZero's Swagger API documentation site by going to the API page here:
1. Click the **Authorize** button to open the **Available Authorizations** window.
2. Scroll down to `oauthDefaults (OAuth2, clientCredentials)` section and enter a `client ID` and `client Secret`that you generated in the RunZero console by registering an API client.
3. Click **Authorize** to make the authentication call and receive an API bearer token.
4. Next to the GET `/account/orgs` API documentation, click the **Try it out** button.
5. Click the **Execute** button that appears below the parameters.
6. Scroll down to the response and identify the **Organization ID** to use.
### Transform
The **Advanced** section of the context integration contains the *Transform* field. This field allows you to add, remove, or change the mapping of fields returned by the vendor API to Vectra Fusion context labels.
See the [Context Transforms](/netofuse/context-transforms) documentation section for more instructions on editing this field.
It may be helpful to first configure all the parameters and the transform field with a [NetoFuse](/netofuse/about) container on your local system and then copy those fields into the Portal once you have validated that everything is configured properly.
# SentinelOne
This document provides instructions for configuring SentinelOne in order for the Vectra Context Integration to have the correct access to pull label contexts. Prerequisites Configure API token Bef
This document provides instructions for configuring SentinelOne in order for the Vectra Context Integration to have the correct access to pull label contexts.
## Prerequisites
### Configure API token
Before configuring the SentinelOne Context Integration in Vectra, you will need to an API token configured in SentinelOne. For more information configuring the API token from the SentinelOne management console, see the [API Overview](https://usea1-300-nfr.sentinelone.net/api-doc/overview) documentation.
## Vectra Portal Steps
Navigate to Integrations (make sure you are on the Context tab) and click "Add Integration", then select `SentinelOne`
### Configuration
The following fields are specific to the SentinelOne integration.
| Field | Required | Description | Example |
| ---------------- | -------- | ------------------------------------------------------------------------------------- | --------------------------------------------------------------------------- |
| `Base URL` | yes | The SentinelOne domain URL to query | `https://.sentinelone.net` `https://.sentinelone.com` |
| `Account Id` | | The SentinelOne account ID to query | |
| `Filter Id` | | The SentinelOne filter ID to limit query, SentinelOne API result size limit is 10,000 | |
| `Include Ranger` | | If enabled, include Ranger labels | |
### Authentication
The following fields are necessary for the integration to authenticate with SentinelOne.
| Field | Required | Description |
| ------- | -------- | ----------------------------------- |
| `Token` | yes | API token to use for authentication |
# Tanium
The Tanium integration adds enriched asset context to Vectra Fusion.
## About
The Tanium context integration provides enriched asset context to Vectra Fusion from Tanium. It connects to the Tanium GraphQL API to retrieve asset information and then adds Context Labels to Vectra Fusion.
{% hint style="info" %}
**NetoFuse Modules: Cloud deployment vs. on-prem deployment**
This page documents how to add and configure the context integration in the Vectra Fusion Portal. This will make a direct connection from the Vectra Fusion SaaS in the cloud to the vendor API. If you prefer to deploy the integration within your own environment, go to the module documentation in [NetoFuse Modules](broken://pages/6i3otB8UAClHx08Umd0Y).
{% endhint %}
## Adding a Context Integration
In the Vectra Fusion Portal:
1. Select **Settings** at the bottom of the left-hand navigation menu
2. Select **Context Integrations** in the **Data Management** section.
3. Select the **Add Integration** button.
4. Select a context integration from the list provided.
5. Follow the configuration steps in the documentation for the context integration you selected.
## Configuring
| Field | Required | Description |
| ------- | -------- | --------------------------------- |
| API Key | Yes | API key for Tanium authentication |
| URL | Yes | Tanium server address |
{% hint style="danger" %}
**The Tanium URL must be accessible from the Vectra SaaS for cloud deployment of this context integration**
If your Tanium server is not accessible from external IPs, and you can not or do not want to allow external access to it from the Vectra cloud, you need to deploy NetoFuse on-prem for this integration. See [About NetoFuse](/netofuse/about) for more details on how to deploy on-prem.
If you will be updating network firewall rules to allow this connectivity, the IPs used to connect to Tanium from Vectra can be found in the Fusion Portal under **Settings** > **Overview** in the *System Allow Lists* section under *Integrations*.
{% endhint %}
### Advanced Configuration Options
The following configuration options are available for the module.
| Field | Required | Description |
| ------- | -------- | --------------------------------- |
| API Key | Yes | API key for Tanium authentication |
| URL | Yes | Tanium server address |
#### Methods to gather data from Tanium
The `tanium`module supports 4 different methods for gathering data from Tanium. The best method to use depends on your Tanium deployment and the data you wish to retrieve, and determining this is best done in collaboration with a Tanium subject matter expert within your organization and by using the Tanium API documentation.
#### Fields to retrieve from Tanium
The `fields` configuration option defines what fields are retrieved from the Tanium API. This set of fields can then be used by the transform you define.
If you are using methods `ASSET`, `TDS`, or `TS`, the `fields` value represents a list of fields to retrieve from the GraphQL endpoint. The available field options can be retrieved through the Tanium GraphQL Schema or by navigating to the API Gateway GraphQL Playground in the Tanium console.
If you are using method `ADHOC`, the `fields` value represents a list of sensors you want to retrieve from endpoints. The Sensor name is used and can be retrieved from the sensors page in the Tanium UI.
The default configuration uses the `ASSET` method and this `fields` configuration:
`["computerId","computerName","createdAt","eid","id","ipAddress","manufacturer","operatingSystem","osPlatform","serialNumber","servicePack","userName","updatedAt"]`
If you are using the `TDS`, `TS`, or `ADHOC`methods, you will need to update the `fields` configuration.
Example `fields` configuration for `ADHOC`method:
`["Computer Name", "IP Address", "OS Platform", "OS Name", "OS Generation", "OS Version", "Serial Number", "Service Pack", "User Name", "Last Logged In User"]`
Example`fields` configuration for `TDS`, and `TS` methods:
`["ipAddress", "computerID", "serialNumber", "name", "os{name,platform,generation}","primaryUser{name,email}","lastLoggedInUser"]`
### Transform
The **Advanced** section of the context integration contains the *Transform* field. This field allows you to add, remove, or change the mapping of fields returned by the vendor API to Vectra Fusion context labels.
See the [Context Transforms](/netofuse/context-transforms) documentation section for more instructions on editing this field.
It may be helpful to first configure all the parameters and the transform field with a [NetoFuse](/netofuse/about) container on your local system and then copy those fields into the Portal once you have validated that everything is configured properly.
# Tenable
The Tenable integration adds enriched asset context to Vectra Fusion.
## About
The Tenable Vulnerability Management context integration provides enriched asset context to Vectra Fusion from Tenable Vulnerability Management. It connects to the Tenable API to retrieve asset, vulnerability, and scanner information and then adds [Context Labels](/enrich-traffic-with-context/labels) to Vectra Fusion.
{% hint style="info" %}
**NetoFuse Modules: Cloud deployment vs. on-prem deployment**
This page documents how to add and configure the context integration in the Vectra Fusion Portal. This will make a direct connection from the Vectra Fusion SaaS in the cloud to the vendor API. If you prefer to deploy the integration within your own environment, go to the module documentation in [NetoFuse Modules](broken://pages/6i3otB8UAClHx08Umd0Y).
{% endhint %}
## Adding a Context Integration
In the Vectra Fusion Portal:
1. Select **Settings** at the bottom of the left-hand navigation menu
2. Select **Context Integrations** in the **Data Management** section.
3. Select the **Add Integration** button.
4. Select a context integration from the list provided.
5. Follow the configuration steps in the documentation for the context integration you selected.
## Configuring
| Field | Required | Description |
| ---------- | -------- | ------------------ |
| API Key | Yes | Tenable API Key |
| API Secret | Yes | Tenable API Secret |
### Advanced Configuration Options
These advanced configuration options can be used to specify the data returned by the Tenable API.
| Field | Description | Default Value |
| -------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------- |
| `include_asset_data` | If set to false, no asset data is retrieved, only the vulnerabilities. | `False` |
| `filters` | Filters to apply to asset and vulnerability API calls. More information on this object here: . If another configuration option is already available for the specific filter you want to use, use that one instead of this field. | `None` |
| `cidr_range` | Corresponds to the `cidr_range` filter setting | `None` |
| `severity` |
Comma-separated list of severities to include in vulnerability results. Note that anything less than high is likely to create many context labels that are of low value, which should be avoided.
| `high` |
| `networks` | A comma-separated list of network names. If it is set, the only assets or vulnerabilities included are those in one of the specified networks. | `None` |
| `tags` | A tag to filter assets returned by. A tag has a category name and a value, so the value of this should be written as `“category=value"`. | `None` |
| `scanner_details` | If set to true, retrieve the list of scanners (filtered by the networks and CIDR field above). | `True` |
## Tenable VM Configuration
### Generate a Tenable API Key
Login to your Tenable account and generate an API key at:\
See Tenable documentation if this link has changed or you have any questions about this process:
### Transform
The **Advanced** section of the context integration contains the *Transform* field. This field allows you to add, remove, or change the mapping of fields returned by the vendor API to Vectra Fusion context labels.
See the [Context Transforms](/netofuse/context-transforms) documentation section for more instructions on editing this field.
It may be helpful to first configure all the parameters and the transform field with a [NetoFuse](/netofuse/about) container on your local system and then copy those fields into the Portal once you have validated that everything is configured properly.
# Wiz
Wiz context integration for Vectra Fusion.
{% hint style="info" %}
**📘2 versions of the Wiz context integration are available**
Use *Wiz-2* for new Wiz integrations.
You will see 2 Wiz context integrations in the Fusion Portal (Wiz and Wiz-2). The newest version is **Wiz-2**. **Wiz-2** is built as a NetoFuse module, available for both cloud an on-prem deployment, and has added issue and network exposure handling, along with the flexibility of using NetoFuse transforms to customize the context fields. Both versions will be available for a brief period of time while existing users migrate to the new version, and then `Wiz-2` will be renamed `Wiz` in the Fusion portal.
{% endhint %}
{% hint style="info" %}
**☁️NetoFuse Modules: Cloud deployment vs. On-Prem deployment**
This page documents how to add and configure the NetoFuse module for an on-prem deployment with a container or Python package. If you want to use the cloud deployment model and have this integration run in the Vectra Fusion SaaS, you can add it as a context integration in the Vectra Fusion Portal instead by consulting the [Context Integrations](/enrich-traffic-with-context/configure-context-integrations) documentation.
{% endhint %}
## About
The Wiz context integration provides enriched asset context to Vectra Fusion from the Wiz Cloud Security Platform. It gathers vulnerability data about the cloud assets in your environment from the Wiz API, and adds that as [Context Labels](/enrich-traffic-with-context/labels) in Vectra Fusion.
## Use cases
### Reduce investigation time
An AWS EC2 instance that has only ever communicated to the corporate network makes a new outbound connection to China. You may want to know more about this EC2 instance as you investigate this. The vulnerability context provided by Wiz is immediately available to you without having to pivot to another tool or ask another analyst with direct access to Wiz for this information.
### Enhance monitoring for vulnerable assets
Cloud assets with high-severity vulnerabilities are at higher risk of being exploited and becoming the source of malicious activity. Now that the vulnerability state of these assets is directly available, you can use that information to monitor these assets, including:
* Creating and viewing dashboards focused on activity from the most vulnerable assets
* Create a custom escalation workflow for network activity, such as potential network scanning or exfiltration when it comes from a highly vulnerable asset
* Build custom detections that include the vulnerability state of the asset
You can use the following `NQL` to accomplish this:\
`label.ip.cvss_rating == critical || label.ip.cvss_rating == high`
### Monitor network activity for assets with high-profile vulnerabilities while they are being remediated
A new vulnerability has been released and is being actively exploited in cloud environments. You can focus your attention on the network activity for assets that Wiz has identified as vulnerable to this issue. By watching the assets with a highly visible vulnerability more closely, you can identify potential indicators of compromise and act on them during the critical period before the vulnerability is remediated.
You can use the following `NQL` to accomplish this:\
`label.ip.cve == CVE-2023-0123`
## Context Labels
These context labels are written when using the default module configuration.
| Context Name | Description | Examples |
| ---------------- | --------------------------------------------------------------- | --------------- |
| vuln\_count | The number of vulnerabilities found on the asset | 5 |
| cvss\_rating | The list CVSS ratings of the vulnerabilities found on the asset | critical |
| cve | The CVEs of the vulnerabilities found on the asset | CVE-2023-0123 |
| cvss\_score | List of CVSS scores of the vulnerabilities found on the asset | 9.8, 7.5, 5.0 |
| os | The operating system of the asset | linux |
| wiz\_asset\_name | The name of the asset in Wiz | my-ec2-instance |
If network exposures are enabled, the following additional context labels are available:
| Context Name | Description | Examples |
| ---------------------------------------- | --------------------------------------------------------------------------- | --------------------- |
| wiz\_network\_max\_severity | The highest severity of the network exposure found on the asset | critical |
| wiz\_network\_max\_severity\_value | The CVSS score of the highest severity network exposure found on the asset | 9.8 |
| wiz\_network\_max\_severity\_description | The description of the highest severity network exposure found on the asset | Remote Code Execution |
| | | |
If issue monitoring is enabled, the following additional context labels are available:
| Context Name | Description | Examples |
| -------------------- | ---------------------------------------- | --------------------- |
| wiz\_issue\_id | The IDs of the issue in Wiz | 12345 |
| wiz\_issue\_title | The title list of the issues in Wiz | Remote Code Execution |
| wiz\_issue\_severity | The severities list of the issues in Wiz | critical |
| wiz\_issue\_status | The status list of the issues in Wiz | open |
| wiz\_issue\_type | The type list of the issues in Wiz | vulnerability |
## Configuring
### Configure a service account
A Wiz Service Account is used to authenticate with the Wiz Integration API. The service account must possess these listed permissions:
| Permissions Required |
| ----------------------- |
| create:reports |
| read:reports |
| update:reports |
| read:vulnerabilities |
| read:issues |
| read:network\_exposures |
Consult Wiz documentation for the steps needed to create this account and configure permissions.
### API parameters required
All the fields required for this integration are listed here.
| Wiz Field | Description |
| -------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Wiz API Endpoint URL | The URL for the Wiz API endpoint. Find this parameter in your Wiz tenant by clicking Profile > User Settings and copying the API Endpoint URL field. e.g.`http://api..app.wiz.io/graphql` |
| Wiz Token URL | The URL for the Wiz token endpoint. For all Wiz commercial customers, this should be set to:`https://auth.app.wiz.io/oauth/token` |
| Wiz Client ID | The client ID for the Wiz service account |
| Wiz Client Secret | The client secret for the Wiz service account |
### Configuring Fusion
{% hint style="danger" %}
**❗️Wiz can take many hours to execute the first time it runs, causing a Context deadline exceeded errorin Fusion Portal,**
The Wiz integration can take many hours to run (up to a day) the first time it executes due to the large number of vulnerabilities that may exist within Wiz in total. This will result in a context deadline exceeded error being reported by the Portal when the integration is run by a user in the Portal manually, either during the initial Create and Run step, or when making changes thereafter.
This error indicates that the integration did not complete quickly enough for it to report its state to the Vectra Fusion Portal, but it does not mean that the integration is not working.
Check the audit log to see if the integration completed successfully or if an error was returned by the API.
Check back in the Vectra Fusion Portal in 24 hours to see if the context labels have been successfully populated.
{% endhint %}
## Adding a Context Integration
In the Vectra Fusion Portal:
1. Select **Settings** at the bottom of the left-hand navigation menu
2. Select **Context Integrations** in the **Data Management** section.
3. Select the **Add Integration** button.
4. Select a context integration from the list provided.
5. Follow the configuration steps in the documentation for the context integration you selected.
#### Configuration Parameters
| Field | Description |
| ------------------------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Name | A name for the integration |
| Wiz API Endpoint URL | The URL for the Wiz API endpoint |
| Wiz Token URL | The URL for the Wiz token endpoint |
| Wiz Client ID | The client ID for the Wiz service account |
| Wiz Client Secret | The client secret for the Wiz service account |
| Wiz Project ID | The Wiz project ID to use for the integration. If you would like this to run as global, leave as the default `*` |
| Wiz Severities |
If this is set, vulnerabilities and issues are filtered only to include those with the listed severities. Valid values are LOW, MEDIUM, HIGH, CRITICAL The format for this field is a comma-separated list enclosed in brackets, e.g. \["HIGH","CRITICAL"] All severities are included if this is left blank
|
| Fetch Issues Toggle | Enable this toggle if you would like to fetch issues from Wiz |
| Fetch Network Exposures Toggle | Enable this toggle if you would like to fetch network exposures from Wiz |
| Wiz Audience | This value should always be set to `wiz_api` |
#### Advanced Configuration Parameters
In the **Advanced** Section, you can also configure the following fields *(in most cases, you do not need to change these)*.
| Field | Description |
| --------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Trace Logs | Enable this toggle to capture trace logs for the integration |
| Issue Report ID | The ID of the report to fetch issues from. This is optional and only required if you are close to your report limit in Wiz and want to fetch issues from a specific report. Leave blank if you want to make a new report if does not exist. |
| Transform | See the [Transforms](#transforms) section for more informatio |
#### Transforms
The Advanced section of the context integration contains the Transform field. This field allows you to add, remove, or change the mapping of fields returned by the vendor API to Vectra Fusion context labels.
See the [Context Transforms](/netofuse/context-transforms) documentation section for more instructions on editing this field.
It may be helpful to first configure all the parameters and the transform field with a NetoFuse container on your local system and then copy those fields into the Portal once you have validated that everything is configured
# Understand Context Labels
About Context Labels Context labels are strings that are associated with an IP address in Fusion to help provide context about network activity. Context labels can be used for: Visually differentiatin
### About Context Labels
Context labels are strings that are associated with an IP address in Fusion to help provide context about network activity.
Context labels can be used for:
* Visually differentiating and understanding IP addresses in the Netography portal
* In NQL in the Fusion Potal, in API calls, and in Detection Models for searching and filtering, defining custom alerting conditions, and triggering events
#### Context label format
* Multiple labels can be created for a single IP address within Netography.
* The Netography portal can display multiple labels for an IP in the Properties Tray that appears on the right-hand side of the Fusion Portal when selecting an IP address.
* Context labels have a *context name* and *context value*. The format of a context label is:
label.IP.*context* = *value*. Where *context* and *value* are definable.
* Individual IP addresses can support multiple contexts.
* Each context can support multiple values for each context.
* Context integrations populate IP addresses with context labels. You can also manually add context labels to the system using the Fusion API, importing from CSV files, or by developing your own NetoFuse modules.
{% hint style="warning" %}
**🚧The name context is treated differently than other contexts, as this context used in Netography Fusion charts and tables whereas other contexts are not.**
{% endhint %}
#### Differences from flow tags
Context labels in Netography are set of values applied to an IP address or port number. The Fusion portal will only display the current label values for an IP and does not maintain a historical record of label values (time-series historical support for context labels will be coming in a future update).
Flow tags, on the other hand, are values applied to the flows between Source IP / Source Port to Destination IP / Destination Port pairs and are stored within each matching flow record that Netography stores. As such, there is a historical record of the tag value that was applied when the flow record was stored. Names are only supported in flow tags, and a context structure is not supported.
### Viewing context labels
You can view the context labels currently in your account by going to **Settings > Context Labels**. On this page you can also individually add a label or import a CSV file in the context label format. For more flexible ways of adding context labels, see [Configuring Context Integrations](/enrich-traffic-with-context/configure-context-integrations).
The following fields are required in order to create IP labels within Netography successfully:
* **IP Address:** Specify the target and unique address of the device or resource within your network.
* **Context:** Define the context for your label; the context value is a mechanism to logically group together types of labels to make sense of the labels you apply to the IP addresses in your infrastructure. This can be types of information such as department, security\_policy, hostname, cloud\_provider, etc. You can create a new context value or use an existing value from the drop-down menu.
{% hint style="warning" %}
**🚧Context name characters must be \[A-Za-z0-9\_-]**
{% endhint %}
* **Labels:** Apply the Label value(s) for the given Context. For instance, a context value of “department” might have values of: finance, accounting, and receivables. The same IP address could also have a context value of “location” with the associated label value of Minneapolis.
{% hint style="warning" %}
**🚧Label value characters must be \[^a-zA-Z0-9 .\_/\\-#\~:()]**
{% endhint %}
When you finish typing your label, select the Create option underneath the drop box to create and save the first label. You can repeat this for creating multiple labels.

### Port labels
Port labels in Netography will differ from IP label creation, as they will have the common protocol types and port values mapped to your created port labels. This may be useful if you are using non-standard ports for your applications and want to label those ports.
You can view and edit Port Labels by switching from the **IP Labels** to **Port Labels** tab.
The following fields are required in order to create portal labels within Netography successfully:
* **Port:** Specify the port number of the device or resource within your network.
* **Protocol:** Specify the protocol type associated to your port number by selecting the appropriate value from the dropdown.
* **Label:** You can define the context for your port label, such as categorizing dhcp, calling out cloud provider, etc. You are also able to create multiple labels using the same creation steps in the IP label section earlier.
* 
#### Label Usage Notes:
1. Both Contexts and Label Values are restricted to the following character set: a-z , A-Z , 0-9 ,” “ (space), “\_” (underscore) ,”-” (dash), and “.” (dot/period)
2. The CSV format for both “CSV via S3” integration and portal CSV bulk upload is as follows (the combination of IP and Context should be unique per line in the file). For a more flexible way to import from CSV files that includes header rows you want to dynamically transform into context labels, see [NetoFuse CLI: Upload command](/netofuse/shell-commands).
`IP1,Context1,Label1,Label2`
`IP1,Context2,Label1,Label2`
`IP2,Context3,Label1,Label2`
#### API for Labels
To view how label creation and modification works on our API, please visit the following:
* [IP Labels](https://docs.netography.com/api-reference/netography-apis/labels-ips) for more API information on IP labels.
* [Port Labels](https://docs.netography.com/api-reference/netography-apis/labels-ports) for more API information on Port labels.
* [API Overview](https://docs.netography.com/api-reference) for more general API information.
# Automating Response in Fusion
Fusion allows you to create a set of automated responses to events. A response can be a notification sent to a third-party system or a blocking action provided by a third-party system. To automate a r
Fusion allows you to create a set of automated responses to events. A response can be a notification sent to a third-party system or a blocking action provided by a third-party system.
To automate a response involves two configuration steps:
### 1. [Configuring Response Integrations](/automate-responses/configuring-response-integrations)
Configure a **Response Integration**. Response integrations define the method and system a response event is sent to when a *Response Policy* determines a response action should be triggered.
You must add one or more response integrations to Fusion before a response policy will trigger an action.
### 2. [Configuring Response Policies](/automate-responses/response-policies)
Configure a **Response Policy**. Response policies define automated actions in response to events generated by Detection Models. By creating and configuring response policies, teams can streamline their incident response processes, ensuring timely and appropriate actions are taken when specific conditions are met.
A response policy has one or more response integrations associated with it.
# Configuring Response Integrations
Configure response integrations in Vectra Fusion.
There are four types of response integrations offered by Vectra:
| BLOCK | DNS |
| ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
|
|
### Configuring a Response Integration
In **Settings** > **Response Integrations**, click **Add Integration**. Select one of the available Response Integrations to add and configure it.

See the doc page for the selected Response Integration for more configuration details.
#### Common Configuration Fields
All Response Integrations have the following common fields:
| field | Required | Description | Examples |
| ------------- | -------- | ------------------------------------------------ | --------------------------------------------- |
| `Name` | yes | A unique name for the integration | integration1 |
| `Description` | | Additional information regarding the integration | Test integration signaling our QA environment |
# AWS Route 53 (Response Integration)
DNS Type Response Integration
## Prerequisites
Before configuring the AWS Route 53 Response Integration in Netography. For more information, consult the AWS [hosted zone documentation](https://docs.aws.amazon.com/Route53/latest/DeveloperGuide/hosted-zones-working-with.html).
### Retrieve the Hosted zone ID
You'll need to lookup the `Host Zone ID` value. To do so, first log into the AWS Console.
1. Use the search bar to search for Route53 and select it

2. Click on the link to Hosted zones.

3. The **Hosted zone ID** will be on the right side of the table.

## Netography Portal Steps
In **Settings > Response Integrations**, click **Add Integration**. Select **AWS Route 53**.

### Configuration
The following fields are specific to the AWS Route 53 integration.
| Field | Required | Description | Examples |
| -------------- | -------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------- |
| `Record Name` | yes | Enter the domain name that you want to use to route traffic to your App Runner service. The default value is the name of the hosted zone. For example, if the name of the hosted zone is `example.com` and you want to use `acme.example.com`, enter `acme` | acme |
| `Type` | yes | Choose the applicable DNS record type. When routing traffic to an AWS resource, the only record types available are the record types that are applicable to that resource. | A – IPv4 address |
| `Alias Target` | yes | Enter an Alias Target if you want to route traffic to selected AWS resources, such as CloudFront distributions and Amazon S3 buckets, or if you want to route traffic from one record in a hosted zone to another record. | |
| `Host Zone ID` | yes | Route 53 assigns the ID when you create a hosted zone. The main use for this ID is programmatic access to the hosted zone. | ZAF53OCXXXXXX |
| Check Health | | Evaluate target health or not | |
### Authentication
Netography Fusion can access your AWS account using an IAM user via an Access Key ID & Secret Access Key.
{% hint style="warning" %}
**🚧The AWS Response integration currently does not support the IAM Role authentication type.**
{% endhint %}
**AWS Access Key**
The following fields are necessary for the integration to authenticate with AWS Route 53. The values for the ID and Secret are accessible in the AWS IAM console.

# Big Panda
Configure the BigPanda response integration in Vectra Fusion.
## Prerequisites
Before configuring in the Fusion portal, the Callback URL must be setup in Panther. For more details, follow the [custom headers](https://docs.bigpanda.io/docs/custom-headers) instructions from Big Panda.
## Vectra portal steps
In **Settings > Response Integrations**, click **Add Integration**. Select **BigPanda**

### Configuration
The following fields are specific to the Webhook integration.
| Field | Required | Description | Example |
| ----------------------- | -------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------- |
| `URL` | yes | The Big Panda custom headers URL value configured from the custom headers | `https://integrations.bigpanda.io/oim/api/alerts?app_key=` |
| `Skip SSL Verification` | no | If checked, the server certificate will not be validated against the available certificate authorities. Also won’t require the URL host name to match the common name presented by the certificate | |
| `Headers` | no | Comma separated list of `header: value` pairs | `X-Vectra: Webhook` |
{% hint style="info" %}
**📘After your configuration is submitted, the Big Panda integration will be treated as a standard webhook integration in the Fusion portal.**
{% endhint %}
### Authentication
The following fields may be required for the integration to authenticate using HTTP Basic Auth.
| Field | Required | Description |
| ---------- | -------- | ------------------------ |
| `Username` | no | HTTP Basic Auth ID |
| `Password` | no | HTTP Basic Auth password |
### Additional post configuration
After the Big Panda configuration is setup, you will need to configure a Response Policy in the Fusion portal and a custom log parser in Big Panda to receive events from Fusion.
#### Configure a Response Policy to Sent Events to Big Panda
You can configure response policies in the portal by navigating to **Settings > Response Policies > Add Response Policy**.
#### Configure Big Panda Log Schema
To configure the custom log schema from the Big Panda, follow the [Agent log configuration](https://docs.bigpanda.io/docs/configure-the-bigpanda-agent-log) guide in Big Panda.
To get sample logs from the Fusion Portal, go to **Search -> Events**, select an event. view the **raw record** from the properties tray, select the **JSON** tab, and click the top level clipboard icon as shown below:
# BGP
Traffic Type Response Integration
{% hint style="warning" %}
**Prior to creating a BGP plugin, you will need to configure at least 1 device with a unicast BGP neighbor.**
{% endhint %}
## Prerequisites
Before configuring the BGP Response Integration in Netography, you will need to add a BGP unicast neighbor. Refer to vendor specific documentation and the product you are using for configuration. Below are example links to different vendor BGP configuration documentation:
* [Cisco](https://www.cisco.com/c/en/us/td/docs/ios-xml/ios/iproute_bgp/configuration/xe-16/irg-xe-16-book/bgp-dynamic-neighbors.html)
* [Juniper](https://www.juniper.net/documentation/us/en/software/junos/bgp/topics/ref/statement/neighbor-edit-protocols-bgp.html)
* [Arista](https://arista.my.site.com/AristaCommunity/s/article/bgp-peering-configuration-examples-for-service-providers)
## Netography Portal Steps
In **Settings > Response Integrations**, click **Add Integration**. Select **BGP**

### Configuration
The following fields are specific to the BGP integration.
| Field | Required | Description | Examples |
| ------------------ | -------- | ------------------------------------------------------------------------------------------------- | ----------- |
| `Next Hop` | yes | | 12.12.12.12 |
| `Neighbors` | yes | IPv4/v6 unicast BGP neighbors configured in the Netography Portal. | |
| `Communities` | yes | One or many BGP communities. | 3232:32 |
| `Local Preference` | yes | Used to choose the exit path for an autonomous system. Default 100 | 100 |
| `Factors` | yes | | srcip |
| `Expiration` | | Number of seconds the blocklist will remain active | 3600 |
| `Max` | | Limit on number of blocks | 1000 |
| `Allow List` | | One or many Allow Lists configured in the Netography Portal, or a List of IP or IP/CIDR addresses | |
| `Aggregate` | | Aggregate IP addresses by mask length | |
# Blocklist
Block Type Response Integration
## Usage
The Blocklist integration can be a vital tool for security and access control within your network. By properly configuring the above fields, administrators can craft specific rules to control access based on various factors such as IP addresses, ensuring that only authorized access is permitted.
## Netography Portal Steps
In **Settings > Response Integrations**, click **Add Integration**. Select **Blocklist**\`

## Configuration
This section provides configuration details specific to the Blocklist integration. The Blocklist integration is designed to manage and control access based on various factors, allowing administrators to set rules for blocking or allowing specific IP addresses or ranges. Here's an explanation of the fields you'll need to configure:
| Field | Required | Description | Examples |
| ------------ | -------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------- |
| `Factors` | yes | Specifies the criteria to be considered for the blocklist, such as source IP address. | `srcip` |
| `Expiration` | no | Defines the number of seconds the blocklist will remain active. This helps in temporary blocking if needed. | `3600` |
| `Max` | no | Sets the maximum limit on the number of blocks that can be applied. Useful for controlling resource consumption. | `1000` |
| `Allow List` | no | Specifies one or many Allow Lists configured in the Netography Portal, or a specific list of IPs or IP/CIDR addresses that are exempted from being blocked. | `192.168.1.0/24` |
| `Aggregate` | no | Enables the aggregation of IP addresses by mask length. This can be used to group similar or related IP addresses together for more efficient management. | `/24`, `/32` |
# CrowdStrike
Block Type Response Integration
## Usage
The Crowdstrike Block Type Response Integration offers a robust security solution tailored for enhancing defense against cyber threats. By leveraging Crowdstrike's industry-leading threat intelligence and response capabilities, this integration enables users to automate the process of identifying and blocking malicious activities in real-time. Whether it's stopping a known malware attack or preventing suspicious IP addresses from accessing sensitive resources, the integration provides a streamlined way to enforce security policies and respond to threats.
## Prerequisites
Before configuring the Crowdstrike block type response integration in Netography, you will need to have an API Client setup from Crowdstrike.
### Create an API Client
1. Within your CrowdStrike portal, go to **support and resources**, then select **API clients and keys**

2. Input a name and description for your Netography Crowdstrike Response integration. Ensure that **Read** and **Write** are checked for the Hosts API scope as shown below, and click **ADD** to create your API client details to use.

3. Once created, copy the `CLIENT ID`, `SECRET`, `BASE URL`. These values will be used to onfigure the CrowdStrike response integration in Netography.

## Netography Portal Steps
In **Settings > Response Integrations**, click **Add Integration**. Select **Crowdstrike**

### Configuration
The following fields are specific to the CrowdStrike integration.
| Field | Type | Required | Description | Examples |
| ------------ | ------- | -------- | -------------------------------------------------- | -------- |
| `API URL` | string | yes | The CrowdStrike `BASE_URL` | |
| `Factors` | string | yes | Additional information regarding the integration | srcip |
| `Expiration` | integer | | Number of seconds the blocklist will remain active | |
| `Max` | integer | | Limit on number of blocks | 1000 |
### Authentication
The following fields are necessary for the integration to authenticate with CrowdStrike.
| Field | Required | Description |
| --------------- | -------- | --------------------------- |
| `Client ID` | yes | The CrowdStrike `CLIENT ID` |
| `Client Secret` | yes | The CrowdStrike `SECRET` |
# Email
Notification Type Response Integration
## Usage
The Email Notification Type Response Integration is designed to enhance the communication and awareness of security-related events within an organization. Your users can receive immediate alerts regarding any suspicious or anomalous activities detected within their network. This integration allows for the customization of email content, ensuring that the right people receive the right information at the right time.
Whether it's a critical security breach or an update on system performance, the Email Notification Type Response Integration ensures that stakeholders are kept informed and can take appropriate action promptly.
## Netography Portal Steps
In **Settings > Response Integrations**, click **Add Integration**. Select **Email**

## Configuration
The following fields are specific to the Email integration.
| Field | Required | Description | Examples |
| ------------ | -------- | --------------------------------------- | -------------------------------- |
| `Recipients` | yes | Comma separated list of email addresses | , |
| `CC` | | Comma separated list of email addresses | |
| `BCC` | | Comma separated list of email addresses | |
# Flowspec
Block Type Response Integration
{% hint style="warning" %}
**Prior to creating a Flowspec plugin, you will need to configure at least 1 device with a unicast BGP neighbor.**
{% endhint %}
## Prerequisites
Different vendors and products may have their unique documentation and prerequisites for this setup. Below are example links to configure devices with a unicast BGP neighbor:
* [Cisco](https://www.cisco.com/c/en/us/td/docs/ios-xml/ios/iproute_bgp/configuration/xe-16/irg-xe-16-book/bgp-dynamic-neighbors.html)
* [Juniper](https://www.juniper.net/documentation/us/en/software/junos/bgp/topics/ref/statement/neighbor-edit-protocols-bgp.html)
* [Arista](https://arista.my.site.com/AristaCommunity/s/article/bgp-peering-configuration-examples-for-service-providers)
## Netography Portal Steps
In **Settings > Response Integrations**, click **Add Integration**. Select **Flowspec**\`

## Configuration
The following fields are specific to the Flowspec integration.
| Field | Required | Description | Examples |
| ------------------ | -------- | ------------------------------------------------------------------------------------------------- | -------- |
| `Neighbors` | yes | IPv4/v6 unicast BGP neighbors configured in the Netography Portal. | |
| `Local Preference` | yes | Used to choose the exit path for an autonomous system. Default 100 | 100 |
| `Factors` | yes | | srcip |
| `Expiration` | | Number of seconds the blocklist will remain active | 3600 |
| `Max` | | Limit on number of blocks | 1000 |
| `Allow List` | | One or many Allow Lists configured in the Netography Portal, or a List of IP or IP/CIDR addresses | |
| `Aggregate` | | Aggregate IP addresses by mask length | |
# Flowspec (Custom)
Traffic Type Response Integration
{% hint style="warning" %}
**Prior to creating a Flowspec plugin, you will need to configure at least 1 device with a unicast BGP neighbor.**
{% endhint %}
Flowspec (Custom) differs from [Flowspec](/automate-responses/configuring-response-integrations/flowspec-1) in that it allows for a custom rule to be added. Rules are written in the flowspec token language, e.g. `match destination DSTIP then discard`
## Prerequisites
Different vendors and products may have their unique documentation and prerequisites for this setup. Below are example links to configure devices with a unicast BGP neighbor:
* [Cisco](https://www.cisco.com/c/en/us/td/docs/ios-xml/ios/iproute_bgp/configuration/xe-16/irg-xe-16-book/bgp-dynamic-neighbors.html)
* [Juniper](https://www.juniper.net/documentation/us/en/software/junos/bgp/topics/ref/statement/neighbor-edit-protocols-bgp.html)
* [Arista](https://arista.my.site.com/AristaCommunity/s/article/bgp-peering-configuration-examples-for-service-providers)
## Netography Portal Steps
In **Settings > Response Integrations**, click **Add Integration**. Select **Flowspec (Custom)**

## Configuration
The following fields are specific to the Custom Flowspec integration.
| Field | Required | Description | Examples |
| ------------------ | -------- | ------------------------------------------------------------------------------------------------- | ------------------------------------ |
| `Neighbors` | yes | IPv4/v6 unicast BGP neighbors configured in the Netography Portal. | |
| `Local Preference` | yes | Used to choose the exit path for an autonomous system. Default 100 | 100 |
| `Rule` | yes | Custom flowspec token language | match destination DSTIP then discard |
| `Factors` | yes | | srcip |
| `Expiration` | | Number of seconds the blocklist will remain active | 3600 |
| `Max` | | Limit on number of blocks | 1000 |
| `Allow List` | | One or many Allow Lists configured in the Netography Portal, or a List of IP or IP/CIDR addresses | |
| `Aggregate` | | Aggregate IP addresses by mask length | |
# Microsoft Teams
Notification Type Response Integration
## Prerequisites
You'll need to locate the API endpoint (webhook URL) for the team and channel you want to post to. To configure the webhook URL, consult the [Microsoft Teams webhook](https://learn.microsoft.com/en-us/microsoftteams/platform/webhooks-and-connectors/what-are-webhooks-and-connectors) documentation.
## Netography Portal Steps
In **Settings > Response Integrations**, click **Add Integration**. Select **Microsoft Teams**

## Configuration
The following fields are specific to the Microsoft Teams integration.
| Field | Required | Description |
| ----- | -------- | ----------------------------- |
| `URL` | yes | Microsoft Teams `WEBHOOK URL` |
# NS1
DNS Type Response Integration
## Prerequisites
Before configuring the NS1 Response Integration in Netography, you will need to have an API key configured in NS1. To create your NS1 API key, refer to the NS1 [User & Teams](https://help.ns1.com/hc/en-us/articles/360017341694#UUID-a1f883ee-8f3d-cdbf-252c-fd54ece2c7d7) documentation.
## Netography Portal Steps
In **Settings > Response Integrations**, click **Add Integration**. Select **NS1**

## Configuration
The following fields are specific to the NS1 integration.
| Field | Required | Description | Examples |
| -------- | -------- | ----------------------------------------------------------------------------------------------------------------------------- | -------- |
| `Type` | yes | Indicates the type of record to be created. | CNAME |
| `Domain` | yes | Domain or subdomain to which this record applies. | |
| `Link` | yes | A linked record can be any record type (A, MX, CNAME, etc.), but it must be the same types as a target or it will not resolve | |
| `Zone` | yes | Fully qualified domain name (FQDN) for the zone | |
## Authentication
The following fields are necessary for the integration to authenticate with NS1.
| Field | Required | Description |
| --------- | -------- | --------------- |
| `API Key` | yes | The NS1 API Key |
# Pagerduty
Notification Type Response Integration
In **Settings > Response Integrations**, click **Add Integration**. Select **Pagerduty**\`

## Configuration
The following fields are specific to the Pagerduty integration.
| Field | Required | Description | Example |
| ---------- | -------- | ----------------------------- | ------- |
| `Severity` | yes | Severity level of the message | Info |
## Authentication
The following fields are necessary for the integration to authenticate with Pagerduty.
| Field | Required | Description |
| ----------------- | -------- | ----------------------------- |
| `API Key` | yes | The Pagerduty API Key |
| `Integration Key` | yes | The Pagerduty Integration Key |
# Panther
Prerequisites Before configuring in the Fusion portal, the http source webhook and shared secret authentication method must be setup in Panther. For more details, follow the HTTP log source setup inst
## Prerequisites
Before configuring in the Fusion portal, the http source webhook and shared secret authentication method must be setup in Panther. For more details, follow the [HTTP log source setup](https://docs.panther.com/data-onboarding/data-transports/http#how-to-set-up-an-http-log-source-in-panther) instructions from Panther.
## Netography Portal Steps
In **Settings > Response Integrations**, click **Add Integration**. Select **Panther**.

## Configuration details
The following fields are specific to the Panther integration.
| Field | Required | Description | Example |
| ----------------------- | -------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------- |
| `URL` | yes | The Panther http source webhook URL configured from the HTTP log source setup | `https://name.panther.runpanther.net/example` |
| `Skip SSL Verification` | no | If checked, the server certificate will not be validated against the available certificate authorities. Also won’t require the URL host name to match the common name presented by the certificate | |
| `Headers` | yes | Comma separated list of `header: value` pairs. This will be the shared secret value configured from the HTTP log source setup. | `header: shared-secret` |
{% hint style="info" %}
**📘After your configuration is submitted, the Panther integration will be treated as a standard webhook integration in the Fusion portal.**
{% endhint %}
## Authentication details
The following fields may be used for the integration to authenticate using HTTP Basic Auth.
| Field | Required | Description |
| ---------- | -------- | ------------------------ |
| `Username` | no | HTTP Basic Auth ID |
| `Password` | no | HTTP Basic Auth password |
### Additional post configuration
After the Panther configuration is setup, you will need to configure a Response Policy in the Fusion portal and a custom log schema in Panther to send events from Fusion.
#### Configure a Response Policy to Sent Events to Panther
You can configure response policies in the portal by navigating to **Response -> Response Policies -> Add Response Policy**.
#### Configure Panther Custom Log Schema
To configure the custom log schema from the Panther console, follow the [custom log types](https://docs.panther.com/data-onboarding/custom-log-types) guide in Panther and then navigate to the "Infer schema from sample logs" box or click Select file and choose the log file(s) or paste in the Panther console. Use `JSON` as the Logs Stream Type.
To get logs from the Fusion Portal to use for the Panther custom log types, go to **Search -> Events**, select an event. view the **raw record** from the properties tray, select the **JSON** tab, and click the top level clipboard icon as shown below:
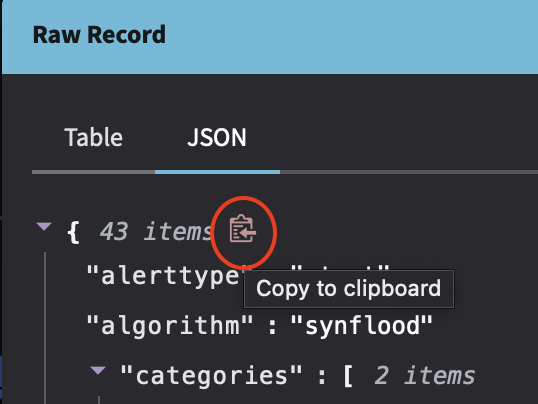
---
[Next Page](/llms-full.txt/1)